Build a language model on your Mac with Language Model Builder
By Flavio
Updated
Tagged: AI
A complete, measured guide to Language Model Builder: plan the run, pick a blueprint and tokenizer, pre-train a small GPT on your Mac, read the loss, sample checkpoints, then fine-tune with SFT and DPO.
Language Model Builder is a free macOS app that teaches you how language models work, then lets you train one yourself.
Everything happens on your Mac. You pick the data, watch the training run, fine-tune the result, and chat with the model you made. No Python, no cloud GPU, no machine learning background needed.
I really like this idea. Language models feel a lot less magical once you’ve watched each part do its job.
This guide goes through the whole thing with real runs and real numbers. There are two models in it:
- TinyStories GPT-2, the 19.3-million-parameter model I trained on my M4 Pro on the TinyStories 2 dataset. I took its training history, checkpoints and samples straight from the project folder, then fine-tuned it with SFT and DPO.
- A 2.1-million-parameter model I trained for 7 minutes on the bundled Tiny Shakespeare text, to see what a tiny run looks like from the first step to the last, and what overfitting looks like when it happens.
If you want the theory behind each stage explained for software engineers, read How to build an LLM from scratch next to this one. Here we stay close to the app and to what it measured.
What is Language Model Builder?
Language Model Builder is an educational app created by Felix Rieseberg.
It has two parts. The first is an interactive introduction to language models. It takes about 90 minutes and covers next-token prediction, tokenization, embeddings, attention, transformers, training data, gradient descent, and fine-tuning.
The second is a native workbench where you put those ideas to work. You build a tokenizer, pick a dataset, start a training run, look at samples along the way, and talk to the finished model.
On the default path you create a small model from scratch and train its weights yourself, instead of downloading a finished chatbot and renaming it.
The whole run follows one chain. Every section of this guide is one link of it:
What do you need?
You need an Apple Silicon Mac running macOS 15 or later. The app uses MLX, Apple’s machine learning framework for Apple Silicon, so Windows, Linux, and Intel Macs are out for now.
The app is free, with no account and no subscription. Download the current build from the official website or from the GitHub releases. The runs in this guide used version 1.2.3.
Plan for disk space. The app is 40 MB, but my TinyStories project folder holds 3.3 GB: 2.2 GB of downloaded text, a 1.1 GB token cache, and about 150 MB of checkpoints.
It also runs inside a macOS virtual machine. I ran the Tiny Shakespeare model and the fine-tuning in a Sequoia VM on the same M4 Pro, where the app reports the GPU as a “Paravirtual device” and calibrates its estimates for it. It’s slower than the host, but it works.
Plan the experiment before you press Start
Training takes long enough that you want to know what you’re measuring before you begin.
Write one hypothesis, a few fixed prompts, and a short run manifest. Here’s the manifest for my TinyStories run, filled in from the project’s own files:
Run ID:        tinystories-gpt2
Mac:           M4 Pro, app 1.2.3
Tokenizer:     GPT-2 byte-level BPE, 50,261 tokens
Dataset:       TinyStories 2 (2.2 GB train, 19 MB validation)
Training data: 564,033,192 tokens
Model shape:   512 context, 256 wide, 8 blocks, 4 heads
Parameters:    19,289,344
Batch:         32 sequences of 512 tokens
Learning rate: 5e-4 peak, 200 warmup steps, cosine decay
Prompts:       "Once upon a time", "Tell me a story about a brave little boat."
Every value in it matters later. The tokenizer decides what a loss number means, the batch and context decide how many tokens one step is, and the prompts are what you compare checkpoints with.
Keep observations separate from explanations in your notes. “Validation loss rose after step 600” is an observation. “The model started memorizing” is an explanation that needs a test.
How to build an LLM from scratch has a full model-lab.md template if you want one.
Start with the interactive textbook
My advice is to resist the temptation to start training right away. Go through the introduction first. The lessons build the mental model you need to make sense of the training screens later.
It starts from one idea: a language model predicts what comes next. Then it walks through the pieces that make this possible.
Tokens and token IDs
A model receives text as a list of numbers called tokens, not as words.
A tokenizer splits text into pieces and maps each piece to an integer ID. The model sees the IDs, looks up a learned vector for each one, and predicts the ID that comes next.
Language Model Builder offers two tokenizers:
- Fast 10K BPE (recommended): a 10,000-token byte-level BPE vocabulary trained on your own dataset.
- GPT-2 BPE: the classic 50,257-token GPT-2 vocabulary plus four reserved chat tokens, 50,261 in total.
Both reserve special tokens for chat: <|system|>, <|user|>, <|assistant|> and <|end|>. Ordinary text can never produce them, which is what lets fine-tuning mark who is speaking.
The app saves each tokenizer as two plain files, vocab.json and merges.txt, so you can look at them. The Fast 10K BPE trained on Tiny Shakespeare has 5 special tokens, 256 single bytes, and 9,739 learned merges. Its first merges are what you’d expect from English text:
Ġ t
h e
Ġ a
o u
Ġ s
Ġ is how byte-level BPE writes a leading space, so the very first merge glues a space to a t. Some of its longest tokens are Northumberland and NORTHUMBERLAND: the name shows up 79 times in the file, 53 of them as the speaker label in capitals.
How the two tokenizers split real text
Tokenizers are easy to measure, so I measured them. I wrote a small byte-level BPE encoder in Python that reads the app’s vocab.json and merges.txt. It counts 312,081 tokens for the whole Tiny Shakespeare file, the same number the app’s token cache holds, so it splits text exactly like the app does.
Here’s how many tokens each one needs per 1,000 characters (fewer is better):
| Text | Fast 10K BPE (trained on Shakespeare) | GPT-2 BPE |
|---|---|---|
| Last 20,000 characters of Tiny Shakespeare | 294 | 326 |
| First 20,000 characters of TinyStories validation | 301 | 256 |
| 20,000 characters of my build-llm-from-scratch post | 353 | 244 |
src/figures/flat.mjs from this site (JavaScript) |
647 | 409 |
A small vocabulary trained on your data wins on that data and loses everywhere else. On Shakespeare it needs 10% fewer tokens than GPT-2. On my blog post it needs 45% more, and on code 58% more.
Single words show why:
| Input | Fast 10K BPE (Shakespeare) | GPT-2 BPE |
|---|---|---|
ROMEO: |
ROMEO : |
ROM EO : |
Northumberland |
Northumberland |
North umber land |
tokenizer |
to ken iz er |
token izer |
Language Model Builder |
L an gu age ĠM od el ĠB uild er |
Language ĠModel ĠBuilder |
Once upon a time, a small fox |
8 tokens | the same 8 tokens |
This matters for context length. A 256-token context holds about 870 characters of Shakespeare with the Fast 10K tokenizer, and much less of anything it never saw.
The tokenizer playground
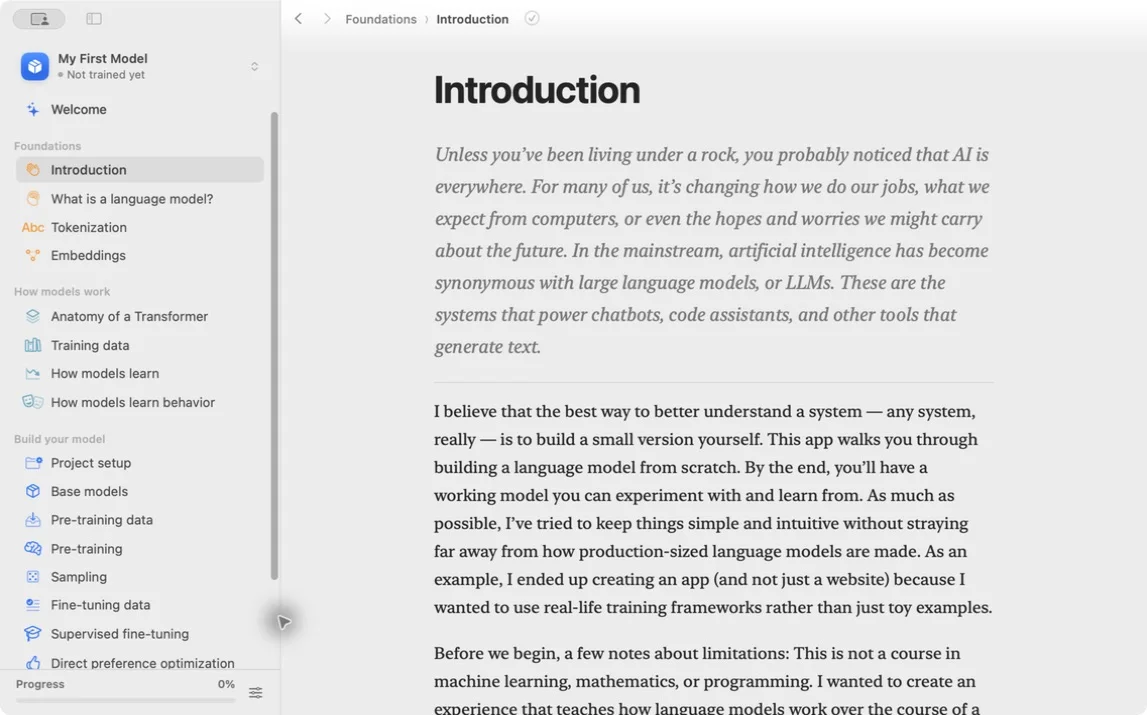
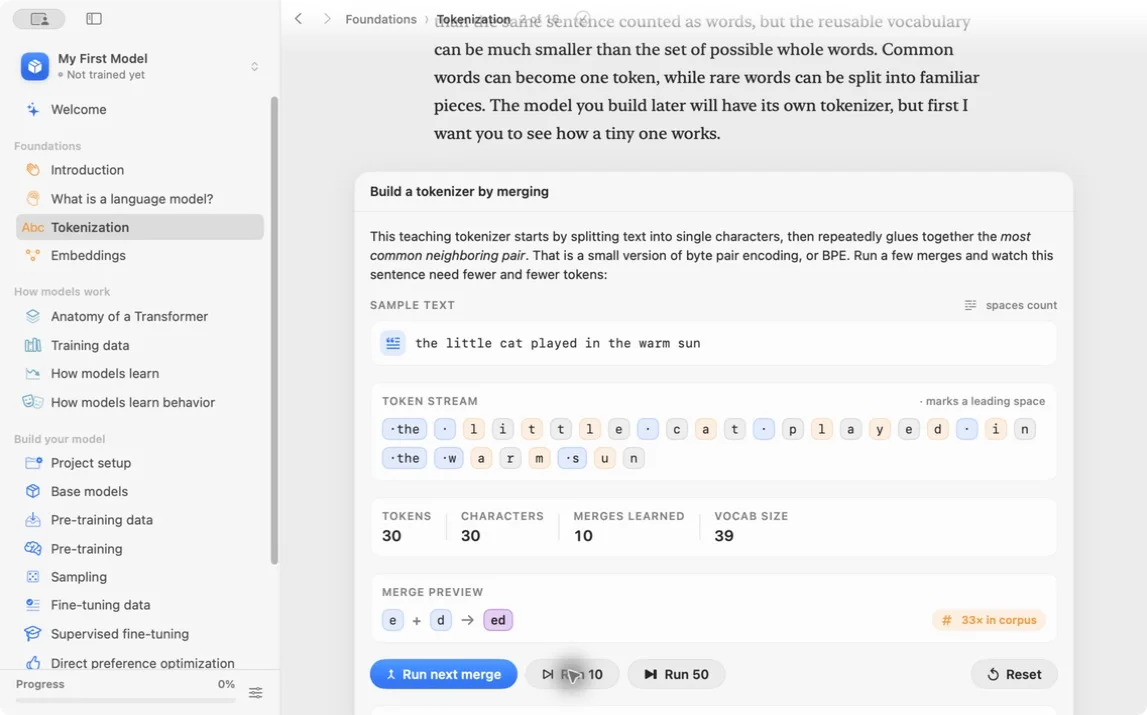
The textbook has a BPE playground. It starts from single characters and merges the most frequent neighboring pair, one merge at a time.
Run five merges by hand and watch the token count drop after each one. The algorithm follows counts, not grammar, which is exactly why Northumberland became one token in a vocabulary that splits tokenizer into four.
Embeddings
An embedding represents each token as a position in a large numerical space. Tokens used in similar ways can develop similar representations. Cosine similarity compares two of those positions by the angle between them. The cosine similarity calculator does that from two JSON arrays.
The embedding playground flattens those vectors into two dimensions so you can look at them. Related words end up close together without anyone labeling them.
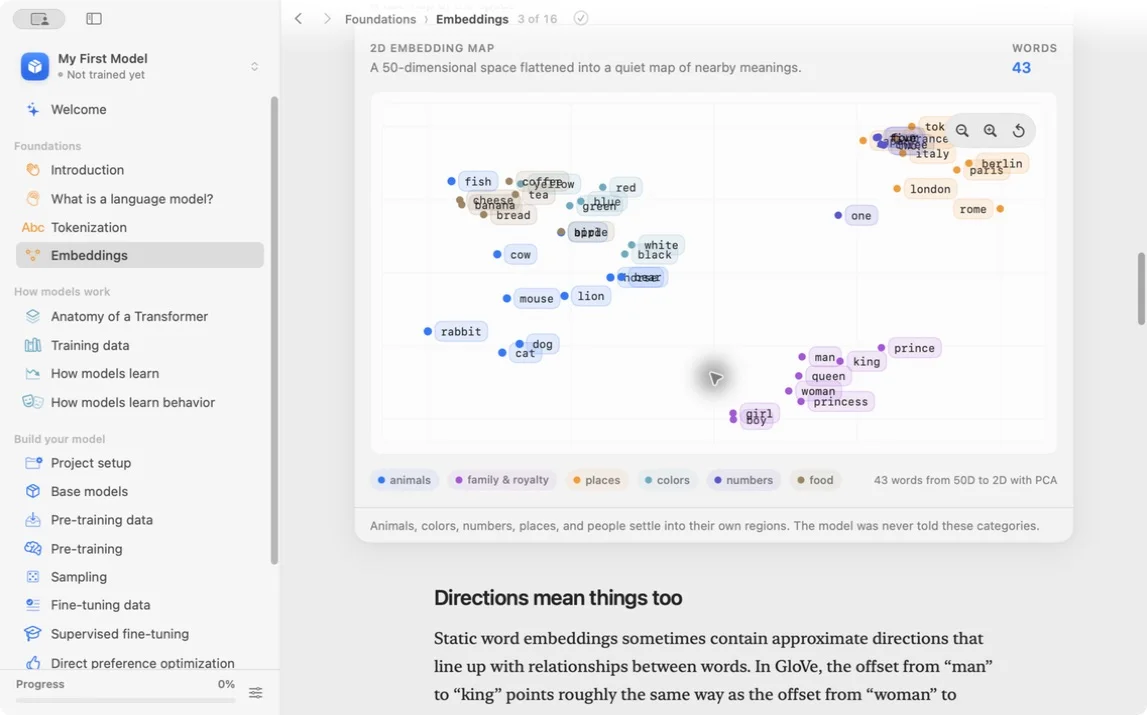
Be careful with what you read into the map. The real vectors have 256 numbers each in the Starter model, and squashing them into two dimensions distorts distances. Two names can also sit together because they appeared in the same story template, not because they mean similar things.
Embeddings are also where a big chunk of a small model’s parameters live, as we’ll see in the blueprint section.
Trace a transformer prediction
Anatomy of a Transformer walks one prompt through the model: token IDs, embeddings, masked self-attention, the feed-forward blocks, and finally one score for every token in the vocabulary. Softmax turns those scores into probabilities, and sampling picks one.
How to build an LLM from scratch has an interactive figure of that path, so I won’t repeat it here.
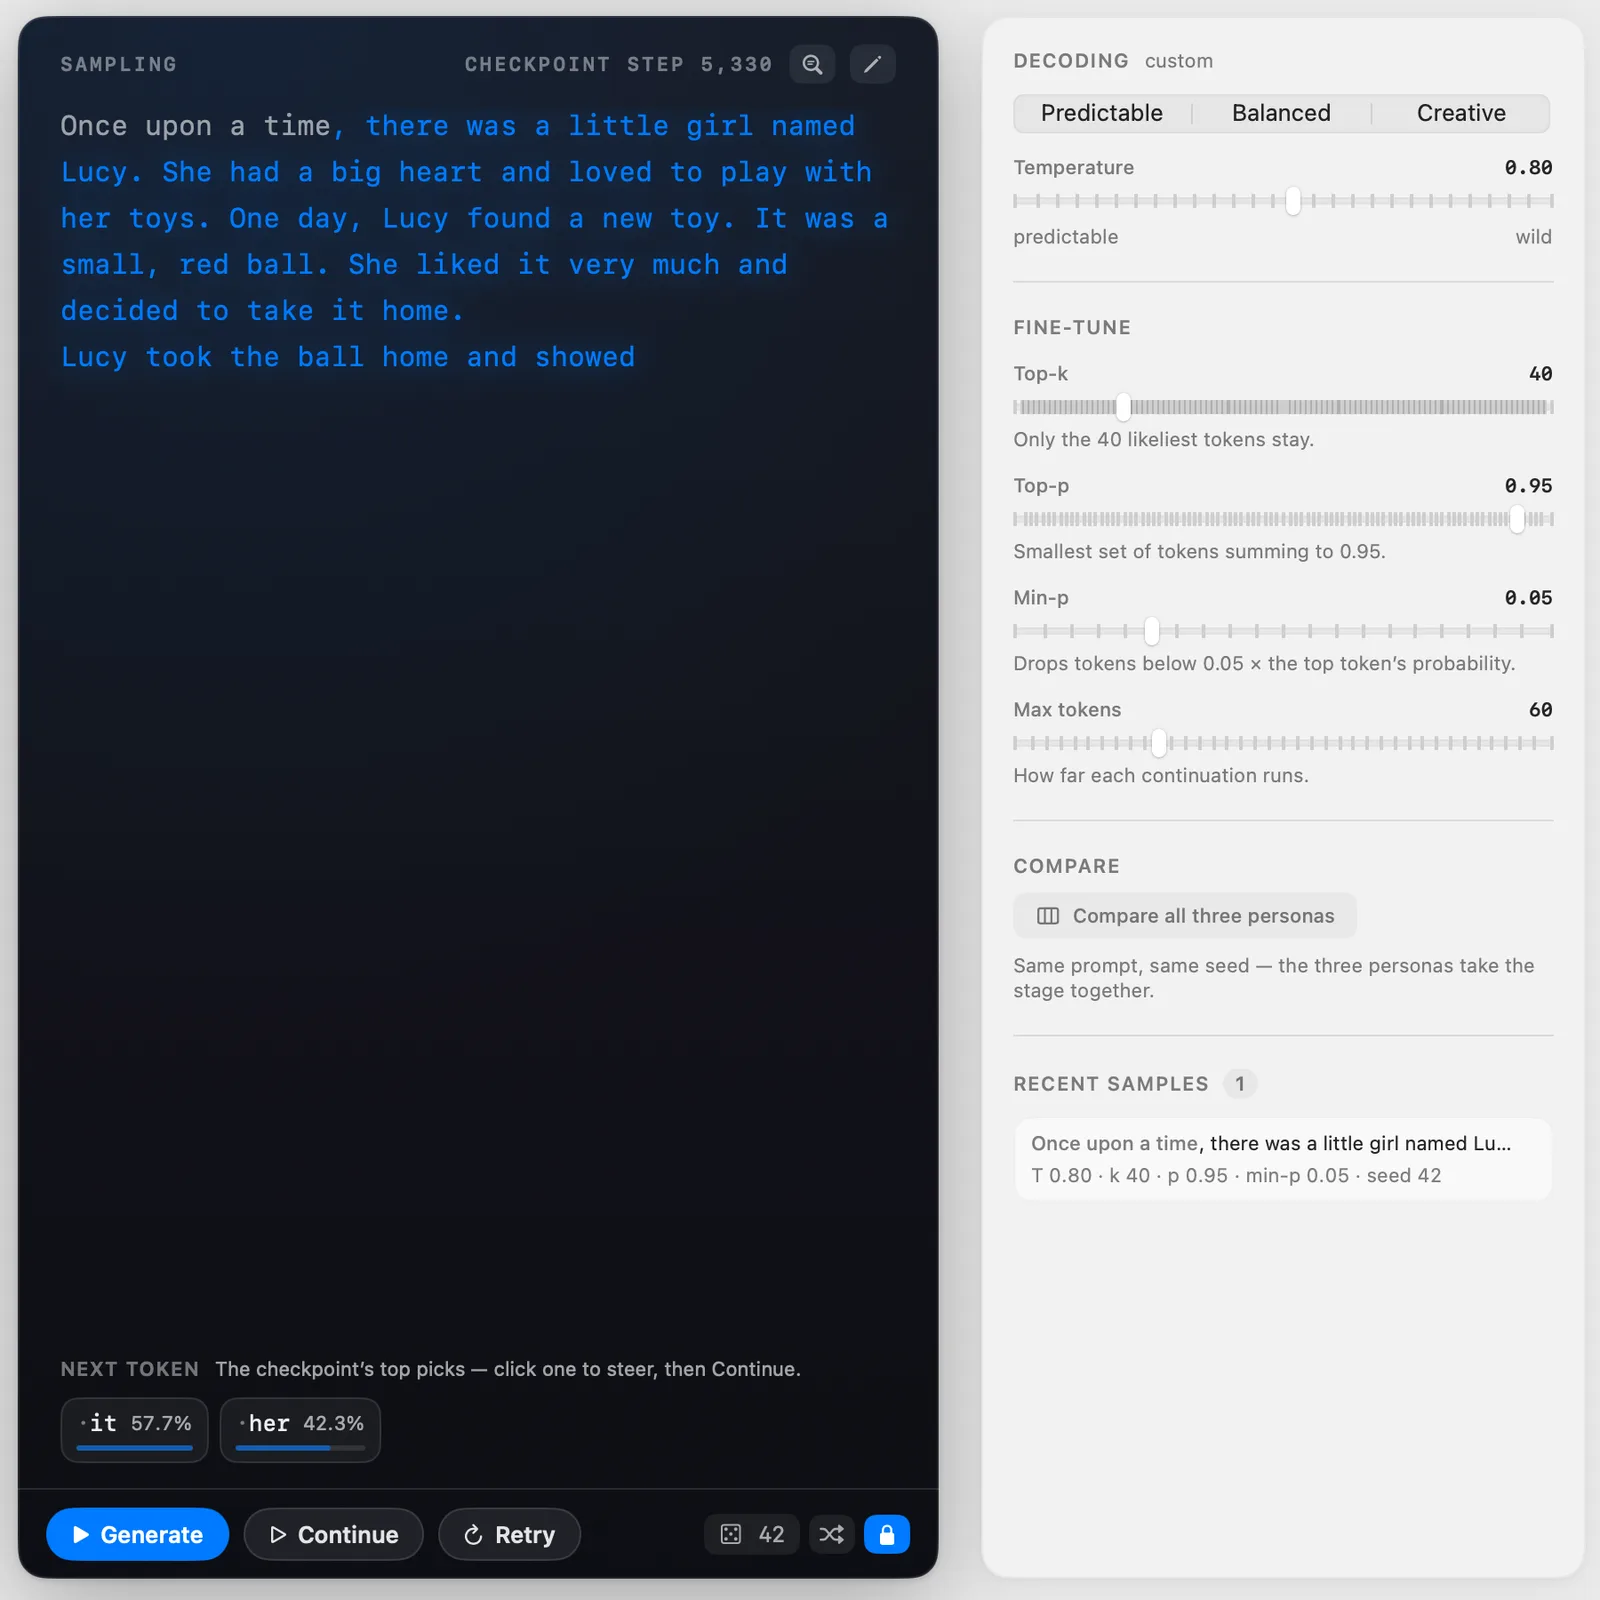
You can see the last step of it in the Sampling screen. After my TinyStories checkpoint wrote “She liked it very much and decided to take it home. Lucy took the ball home and showed”, the app listed the candidates for the next token:
 it    57.7%
 her   42.3%
Only two candidates survived the sampling filters at that position. The model does not store a sentence and play it back. It produces one distribution, picks a token, appends it, and runs again.
Choose a model blueprint
Open Project setup. The blueprint sets the tokenizer, context length, width, number of transformer blocks and attention heads, and shows the parameter count, the size of the weights on disk, and a calibrated training-time estimate.
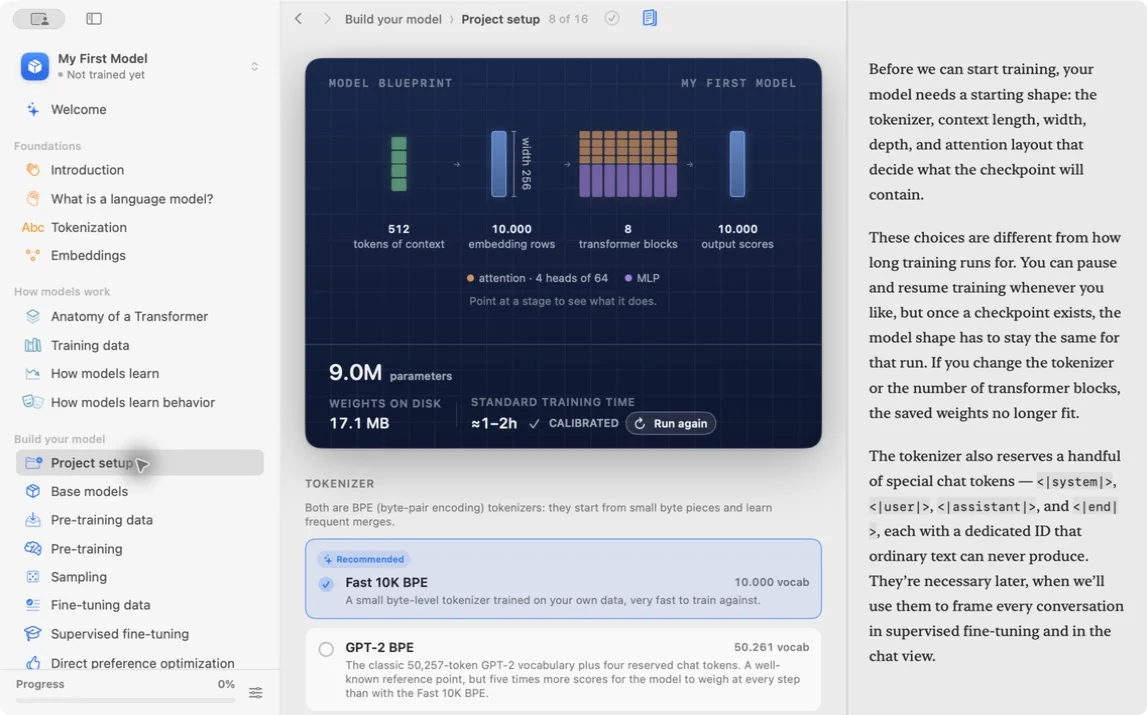
There are three presets, plus anything you build with the sliders. I recorded each one with the Fast 10K tokenizer, and the Starter shape with GPT-2 too. The estimates are the ones the app calibrated in the VM for its standard 20,000-step run:
| Blueprint | Context | Width | Blocks | Heads | Parameters | Weights on disk | Work per step | Estimate in the VM |
|---|---|---|---|---|---|---|---|---|
| Tiny custom (sliders at minimum) | 256 | 128 | 4 | 4 × 32 | 2.1M | 4.1 MB | 0.1× | 1–30 min |
| Starter | 512 | 256 | 8 | 4 × 64 | 9.0M | 17.1 MB | 1.0× | 1–4 h |
| Starter with GPT-2 BPE | 512 | 256 | 8 | 4 × 64 | 19.3M | 36.8 MB | not shown | 3–7 h |
| Patient | 768 | 384 | 12 | 8 × 48 | 25.1M | 47.8 MB | 4.2× | 7–14 h |
| Ambitious | 1024 | 512 | 16 | 8 × 64 | 56.5M | 107.8 MB | 13× | 21–42 h |
On my M4 Pro itself, the app estimated one to two hours for the Starter run.
Start with the recommendation. The point of the first run is a clean baseline you can finish, not the biggest model your Mac can hold.
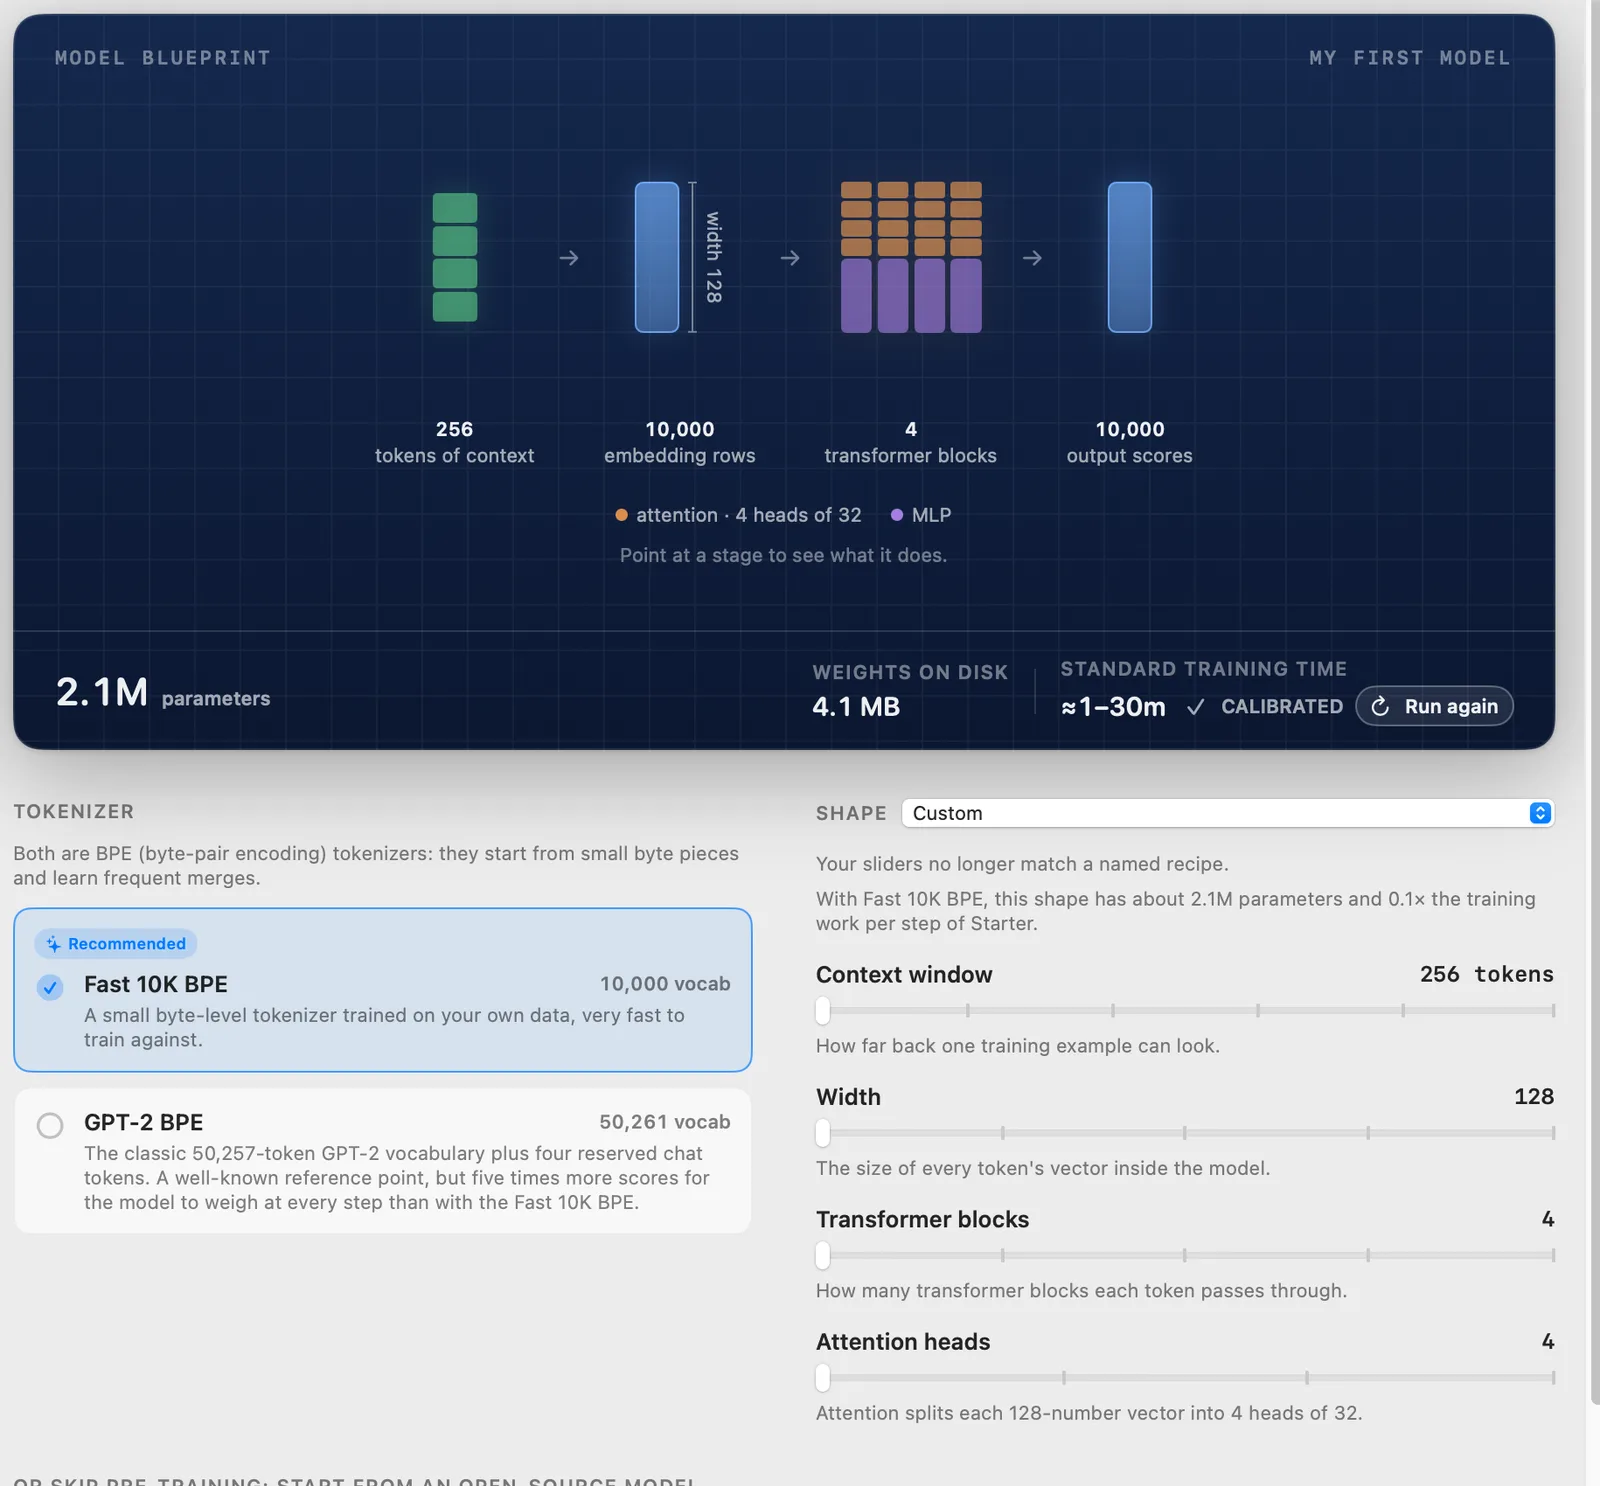
The shape is a contract. Once a checkpoint exists, the app won’t let it load into a different shape, so changing the tokenizer or the number of blocks means a new run.
Parameters, memory and estimates
Parameters are the numbers training changes. A rough count for a decoder transformer is:
parameters ≈ vocabulary × width + blocks × 12 × width²The first term is the token embedding table, which the app also reuses as the output layer. The second is attention plus the feed-forward network in each block. It lands close to the app’s exact counts:
| Model | Embeddings (vocab × width) | Blocks (12 × width² each) | Estimate | App’s count |
|---|---|---|---|---|
| Tiny custom | 10,000 × 128 = 1.28M | 4 × 196,608 = 0.79M | 2.07M | 2,131,968 |
| Starter, GPT-2 BPE | 50,261 × 256 = 12.87M | 8 × 786,432 = 6.29M | 19.16M | 19,289,344 |
Look at the second row. Two thirds of my TinyStories model is the vocabulary table. Switching from Fast 10K to GPT-2 BPE took the Starter shape from 9.0M to 19.3M parameters, and none of those extra parameters made it deeper or wider.
Disk size follows from the parameter count. The trainer keeps parameters in bfloat16, two bytes each, and the checkpoint files match that exactly:
| File in the TinyStories project | Size | Why |
|---|---|---|
checkpoints/model.safetensors |
38,592,727 bytes | 19,289,344 parameters × 2 bytes |
checkpoints/optimizer.safetensors |
77,191,834 bytes | AdamW keeps two running averages per parameter |
checkpoints/best-val/model.safetensors |
38,592,733 bytes | a copy of the weights at the best validation loss |
checkpoints/token-cache/train.npy |
1,128,066,512 bytes | 564M training tokens as 2-byte integers |
Training memory is bigger than the weight file. It also holds gradients, the optimizer state, and the activations of every layer for a batch of 32 sequences. If you want the general math, how much VRAM an LLM needs covers it.
Time is the number to sanity-check yourself. One step is one batch: 32 sequences × 512 tokens = 16,384 tokens. My run held a median of 30,924 tokens per second on the M4 Pro, so a step took about 0.53 seconds, and 20,000 steps of pure training would take this model about three hours. Validation, sample generation and checkpoint writes come on top.
Choose the dataset
Open Pre-training data. The catalog shows each dataset’s size, source, license and a preview of the text the model will read.
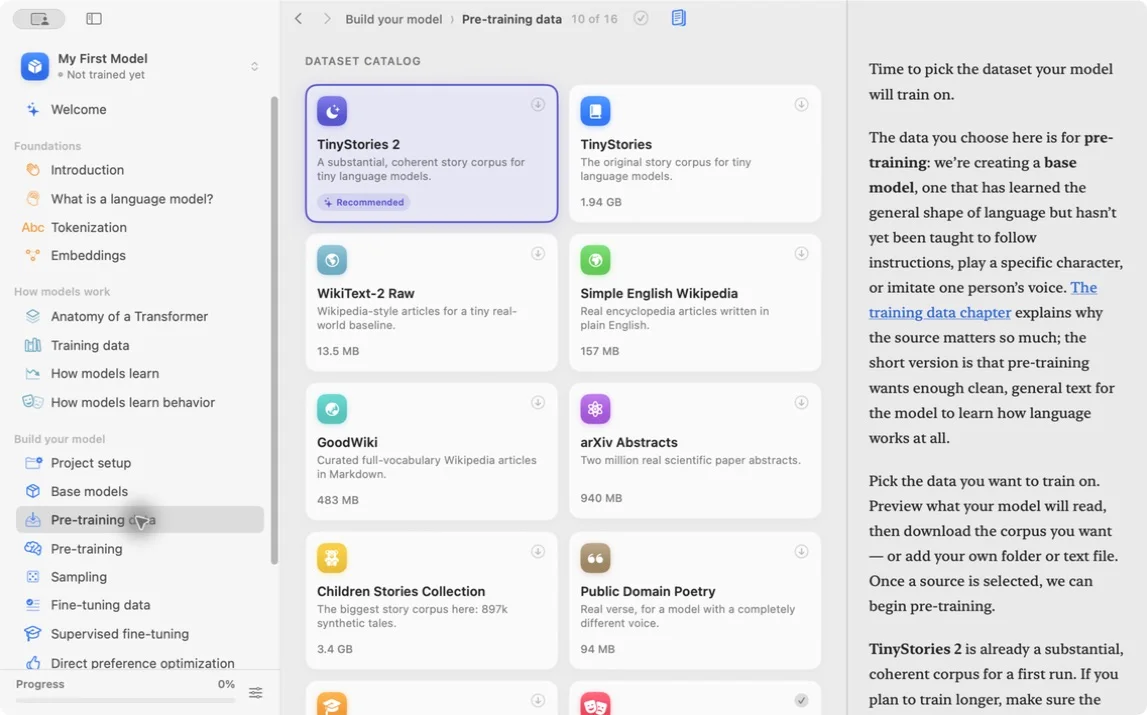
The two datasets in this guide sit at opposite ends:
| TinyStories 2 | Tiny Shakespeare | |
|---|---|---|
| Size | 2.2 GB, downloaded from Hugging Face | 1.1 MB, bundled with the app |
| License | CDLA Sharing 1.0 | MIT (from karpathy/char-rnn) |
| Tokens | 564,033,192 (GPT-2 BPE) | 312,081 (Fast 10K BPE) |
| Characters per token | 3.95 | 3.57 |
| Validation | a separate file, TinyStories-valid.txt |
10% split off the same file |
| One pass with batch 32 × 512 | about 34,400 steps | about 17 steps |
That last row decides everything. On TinyStories, my 5,330 steps saw 87 million tokens, about 15% of one pass. On Tiny Shakespeare, the tiny model’s 5,000 steps at a 256-token context went through the training split 146 times.
The app describes Tiny Shakespeare as a smoke test, and it’s right. It’s the fastest way to see the machinery work, and the fastest way to see a model overfit.
Be careful with data you did not create. A local training run does not remove copyright, privacy, or licensing concerns. If you add your own text, read a few dozen examples first and search for broken encoding like é before you spend hours on it.
Run pre-training
During pre-training, the model learns to predict the next token. Each step takes a batch, compares the model’s predictions with the actual next tokens, and nudges the weights to make them more likely.
The app describes its training recipe as close to the TinyStories runs, with a trainer in the spirit of Karpathy’s nanoGPT: AdamW, a learning rate that warms up over 200 steps to 5e-4 and then follows a cosine curve down to 5e-5, and gradient clipping at 1.0.
Open Pre-training, check that the summary matches your manifest, choose a step target, and press Start pre-training.
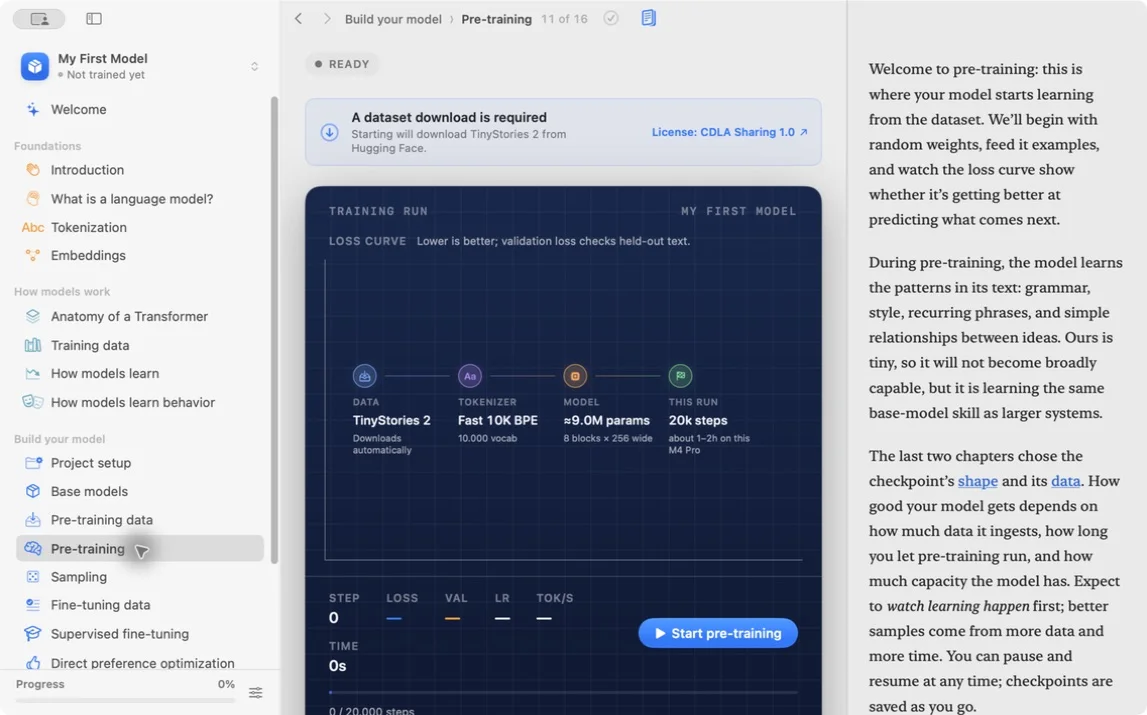
A tiny run, start to finish
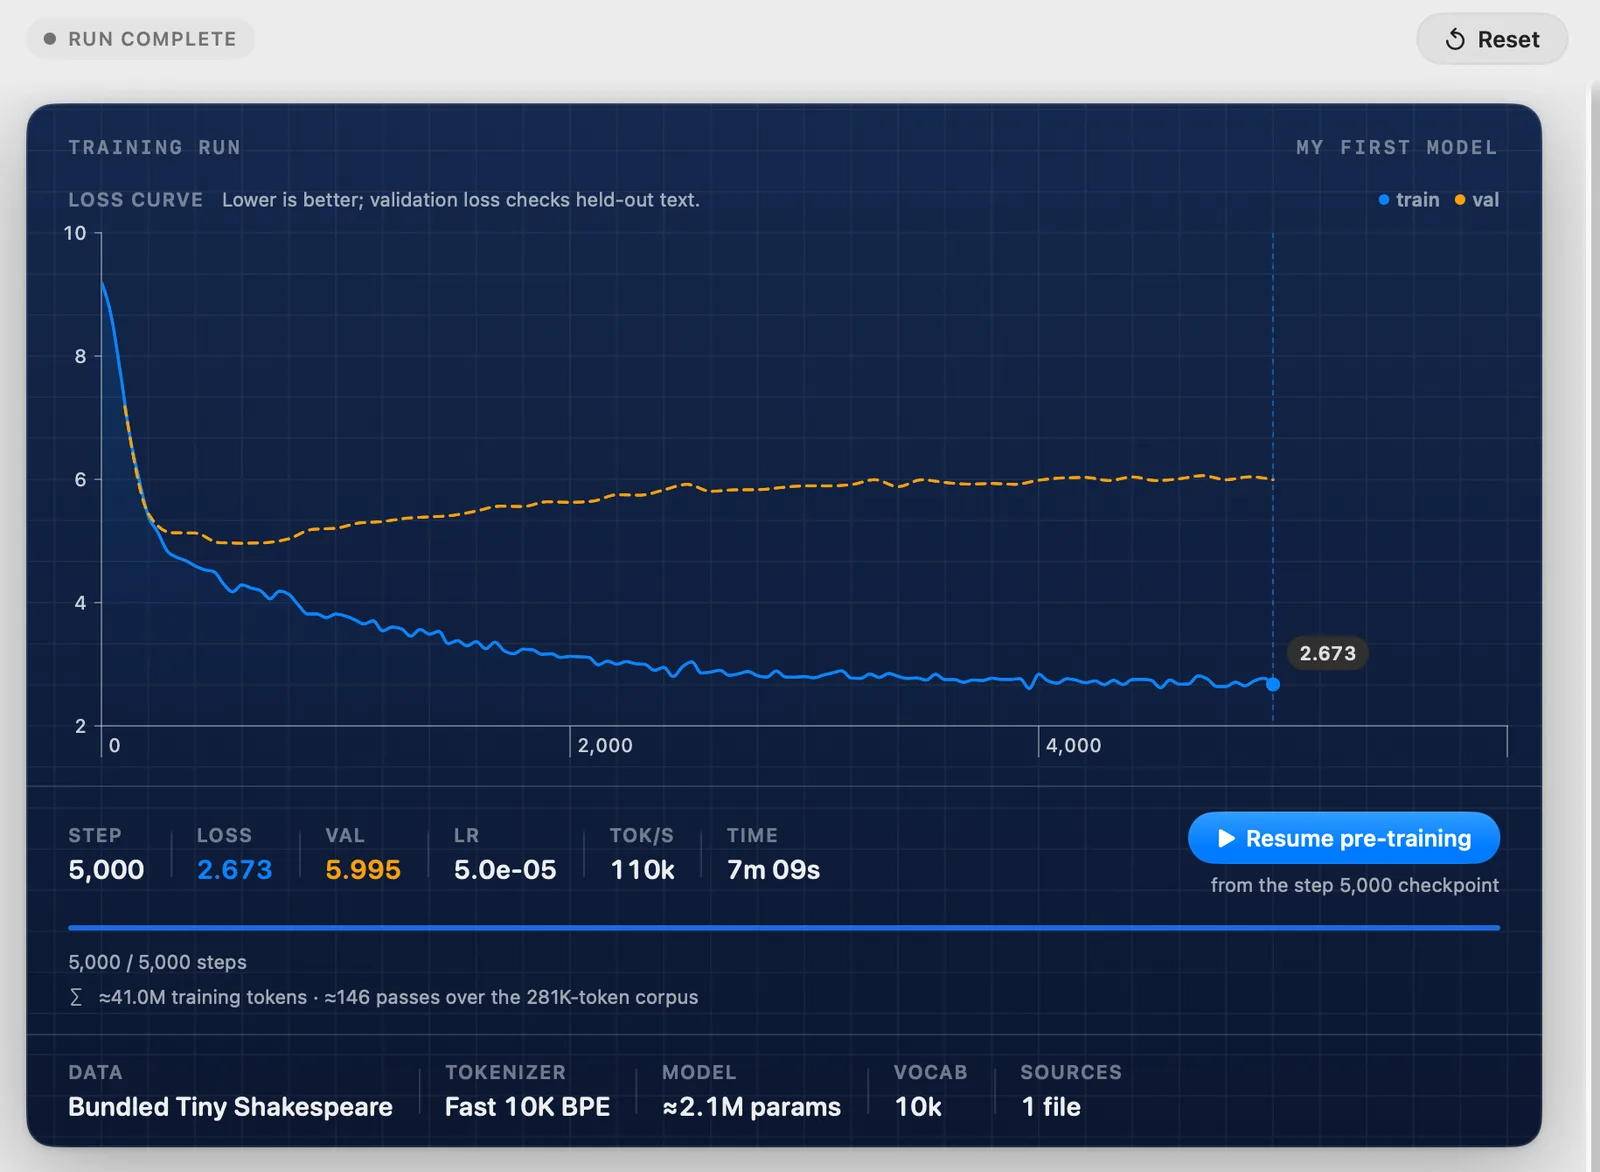
For the tiny model I set the step target to 5,000. Before the start, the app showed:
5.0k steps · about 1–15m on this Paravirtual device
≈41.0M training tokens · ≈146 passes over the 281K-token corpus
Here’s what happened:
| Value | |
|---|---|
| Parameters | 2,131,968 |
| App’s estimate before starting | 1–15 minutes |
| Real training time | 7 min 9 s |
| Throughput | about 110,000 tokens/s |
| Training loss, step 1 → 5,000 | 9.19 → 2.67 |
| Best validation loss | 4.96 at step 600 |
| Final validation loss | 6.00 |
The estimate was right. The SFT estimate later in this guide was not, so read the time as a range until the run settles.
The samples it saved along the way show the progression. Step 100 is a bag of Shakespeare words:
foretell crept giveWARWICWho mystery RICHARDClown thus world bearing Citizen curstEAS with night rich finIUS course beBy step 300 it has learned the shape of a play, with speaker names and line breaks:
ROMEO:
Either him, that my top him's point,
For a child as I may perfect me.

JULIET:
Even, lady.
At step 5,000 the lines look more confident, and they still make no sense:
GLOUCESTER:
I be a Richard; how wiseless substitute,
Asface'd light school you thus been more.
Why, Wor for this hand for time of arms,
A real run, paused and resumed
My TinyStories run is the one worth reading. It trained to step 4,225, I paused it, resumed it from that checkpoint, and stopped it at step 5,330.
The resume barely shows in the data. Training loss was 1.59 at step 4,000 and 1.72 at step 4,230, inside the normal noise between batches (it was 1.74 at step 4,400). Validation went from 2.037 at step 4,200 to 2.051 at step 4,300, and the step counter and the learning-rate schedule continued from where they were.
Pausing works because a checkpoint saves more than the weights: the optimizer state, the step, and the random state of the batch sampler (batch_rng_state in meta.json).
Read training and validation loss
Training loss measures how well the model predicts the batches it learns from. Validation loss measures the same thing on held-out text it never trains on.
For one token, the loss is the negative log of the probability the model gave the right answer:
probability 0.50 → loss 0.69
probability 0.14 → loss 1.96
probability 0.01 → loss 4.61
At step 1 my TinyStories model had a loss of 10.86. That’s almost exactly ln(50,261) = 10.83, the loss of a model that gives every token in the vocabulary the same probability, which is what random weights do. Its best validation loss of 1.957 means it gives the correct next token an average (geometric mean) probability of about 14%, out of 50,261 choices.
Click through the run to see the loss and the saved sample move together:
Here are the same checkpoints as a table:
| Step | Train loss | Val loss | Sample the app saved |
|---|---|---|---|
| 1 | 10.86 | ||
| 100 | 5.80 | 5.95 | LilyAnth weay clean 167 tomorrow come manHello grav park |
| 500 | 2.56 | 2.85 | Lily looked at her and said, "I can know, Ben, I will help you." |
| 1,000 | 2.16 | 2.48 | The rich man was so proud of his new friendship, and they all went home to cozy |
| 2,000 | 1.79 | 2.22 | He was so excited to eat the cheese. He took a big bite and it smelled so yummy! |
| 5,000 | 1.62 | 1.96 | Once upon a time, there was a big, red ball. The ball loved to bounce all day long. |
Most of the improvement happens early. The loss dropped by 8 between step 1 and step 500, and by less than 1 between 500 and 5,000. The samples tell the same story from the other side: step 500 already has quotes and names, while steps 500 to 5,000 are about the story making sense.
Two curves, two diagnoses
The two runs look very different, and the difference is the most useful thing in this guide:
| TinyStories GPT-2 (19.3M) | Tiny Shakespeare (2.1M) | |
|---|---|---|
| Data seen | 15% of one pass | 146 passes |
| Lowest validation loss | 1.957 at step 5,000 | 4.962 at step 600 |
| Last validation loss | 2.005 at step 5,300 | 5.995 at step 5,000 |
| Gap at the end (val − train) | about 0.4 | about 3.3 |
| Diagnosis | still learning | overfitting since step 600 |
On Tiny Shakespeare the training loss kept falling for 4,400 steps after the validation loss hit its low and turned around. That’s overfitting: the model got better at the 281K tokens it kept seeing and worse at text it hadn’t. The useful checkpoint is the one from step 600, and the app keeps it for you in checkpoints/best-val.
Overfitting doesn’t have to mean copying. Not one six-word sequence in the samples saved at steps 300, 600, 1,000, 3,000 and 5,000 appears verbatim in the training file. The model got more confident about Shakespeare’s patterns without reciting him.
On TinyStories the gap of about 0.4 is hard to blame on memorization, since 15% of one pass means the model saw very few stories twice. Validation there comes from a different file, TinyStories-valid.txt, and the training text is TinyStoriesV2-GPT4-train.txt, so part of the gap is simply that the two files were written differently. Validation was still trending down, with the best value at step 5,000. More steps would have helped.
Look at the trend, not single points. TinyStories validation went from 2.091 at step 2,900 to 2.137 at step 3,000 and back down to 2.078 at step 3,100. One bump is noise. Ten rising points in a row, like on Shakespeare, is a trend.
Don’t compare loss values across tokenizers. A loss of 1.96 over a 50,261-token vocabulary and a loss of 4.96 over a 10,000-token vocabulary measure different things.
Two blueprints on the same data
Then I trained the Starter blueprint on the same Tiny Shakespeare file, same Fast 10K tokenizer, same VM, for 2,000 steps. The app estimated 1–30 minutes:
| Tiny custom | Starter | |
|---|---|---|
| Parameters | 2,131,968 | 8,982,528 |
| Context | 256 | 512 |
| Tokens per step | 8,192 | 16,384 |
| Median throughput | 108,920 tokens/s | 34,386 tokens/s |
| Time for 2,000 steps | about 2 min 30 s | 16 min 3 s |
| Best validation loss | 4.962 at step 600 | 4.892 at step 300 |
| Train / val loss at step 500 | 4.44 / 4.97 | 2.89 / 5.31 |
| Train / val loss at step 2,000 | 3.13 / 5.63 | 0.95 / 6.24 |
The tiny run was set to 5,000 steps and the Starter run to 2,000, so their learning rates had decayed by different amounts at step 2,000. Still, the pattern is clear: the bigger model reached a slightly better best checkpoint in half the steps, then overfit much harder. By step 2,000 its training loss was 0.95, which means it gave the right next token about 39% probability on text it had seen 117 times, while validation got worse than the tiny model’s ever did.
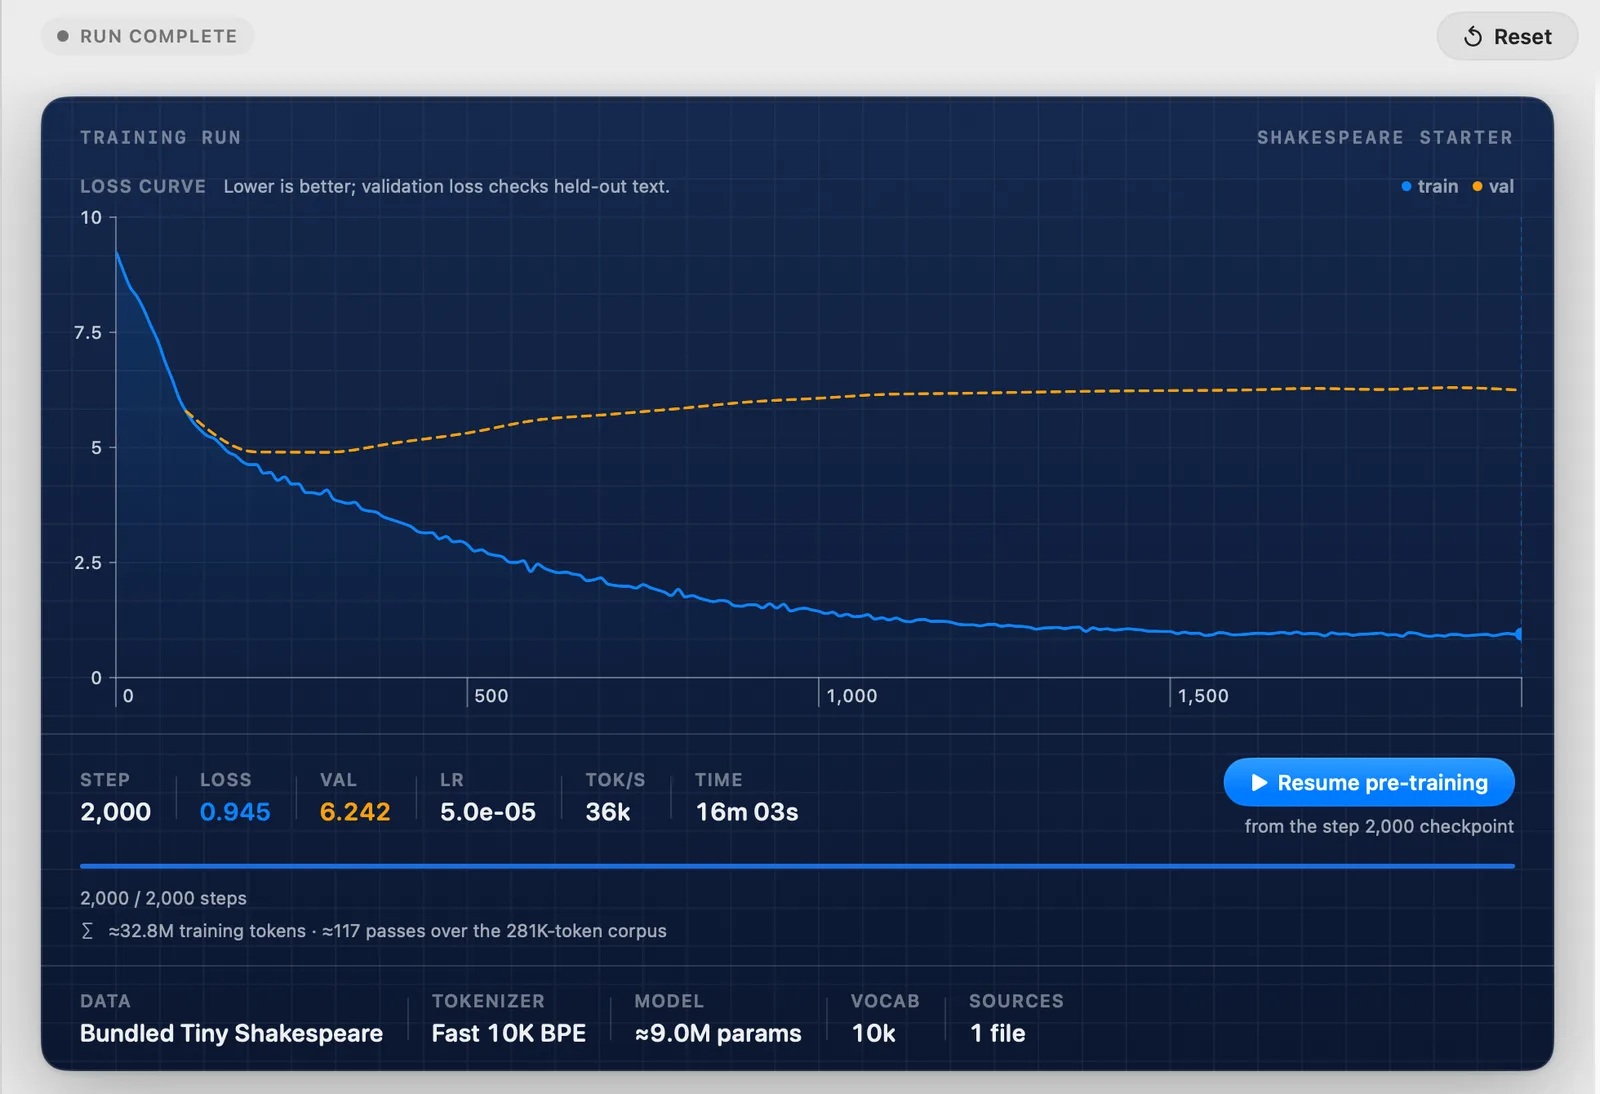
That’s the case for matching capacity to data. More parameters on 281K tokens mostly buy a faster path to overfitting them. Even so, none of the Starter samples saved between steps 300 and 2,000 repeats six words of the training text verbatim.
Checkpoints and sampling
A checkpoint is the saved state of the model at one step. The app keeps the latest one and the best-validation one in the project folder:
checkpoints/
  meta.json               step, shape, tokenizer, best_val_loss, best_val_step
  model.safetensors       latest weights
  optimizer.safetensors   AdamW state, needed to resume
  best-val/               weights at the lowest validation loss
  token-cache/            the dataset, already tokenized
My TinyStories meta.json says "best_val_step":5000 and "step":5330, so the best checkpoint is not the latest one.
Open Sampling to generate text from a checkpoint. The checkpoint decides the probabilities. The sampling settings decide how the app picks from them, and changing them never changes the weights:
- Temperature sharpens or flattens the distribution.
- Top-k keeps the
kmost likely tokens. - Top-p keeps the smallest set of tokens whose probabilities add up to
p. - Min-p drops tokens below a fraction of the top token’s probability.
- Seed makes a sample reproducible.
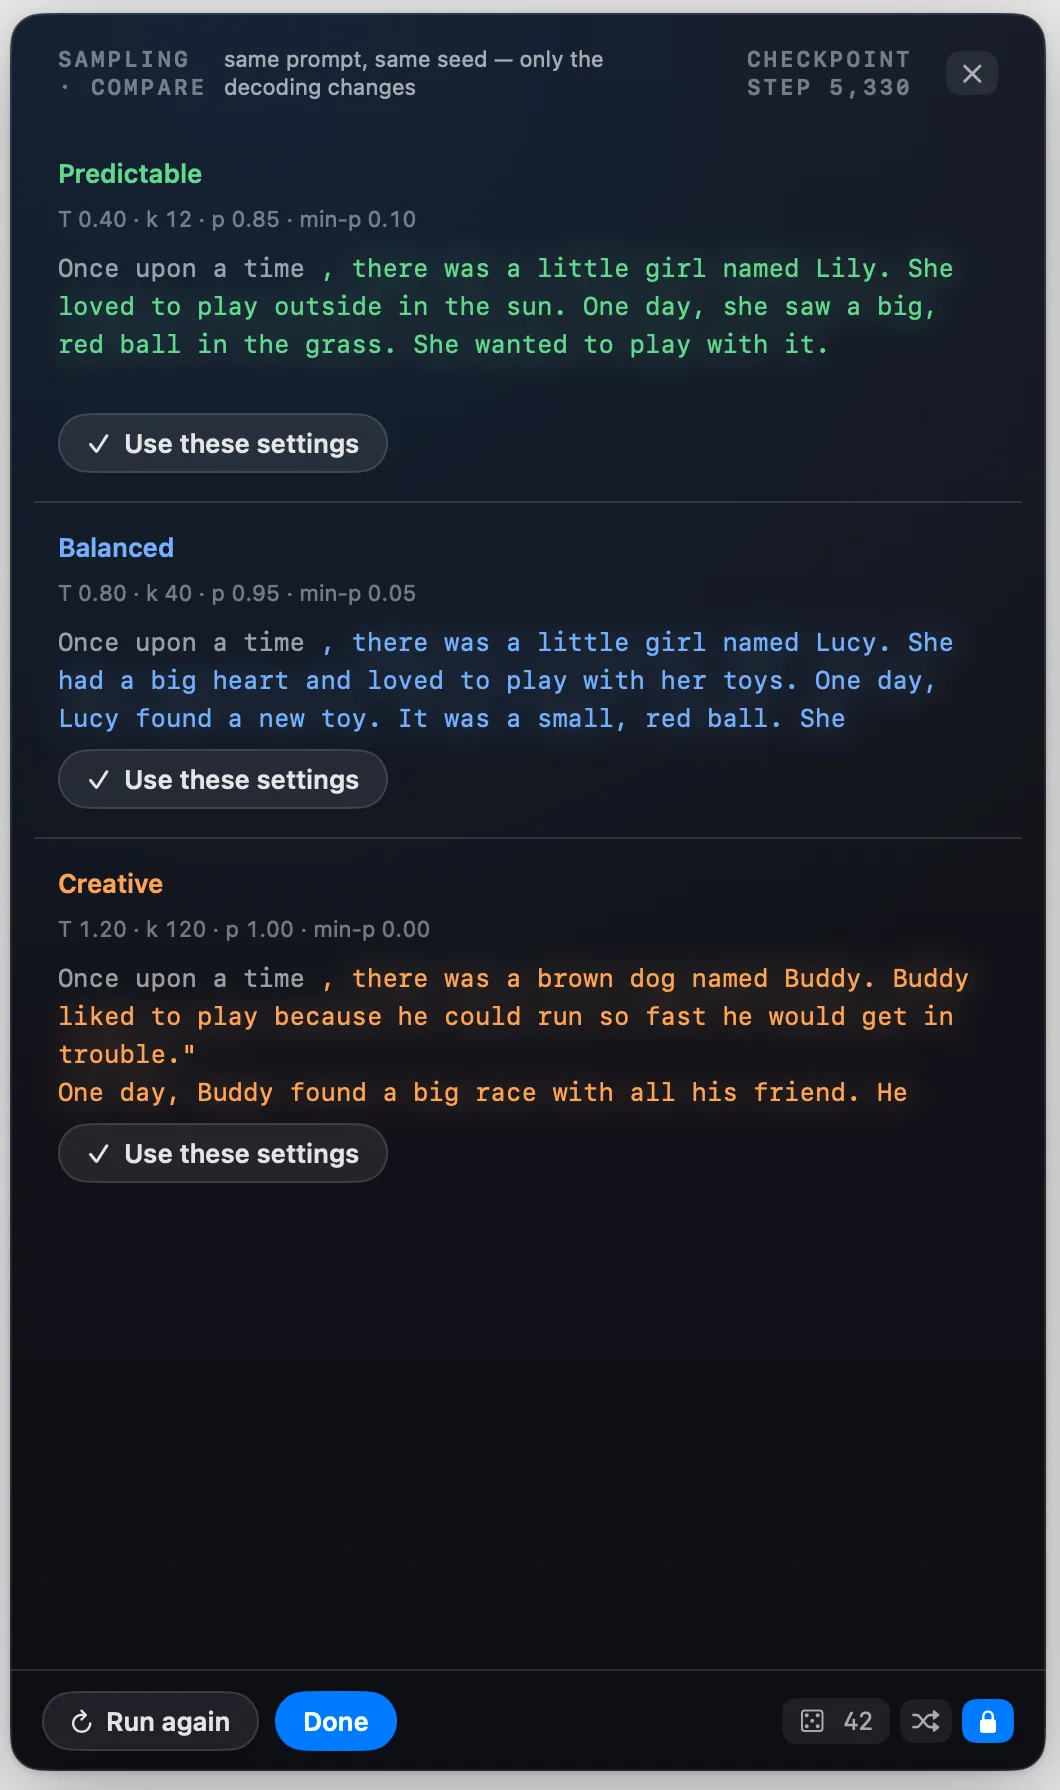
Compare all three personas runs the same prompt with the same seed under three presets. With seed 42 on step 5,330, “Once upon a time” became:
| Preset | Settings | Continuation |
|---|---|---|
| Predictable | T 0.40 · k 12 · p 0.85 · min-p 0.10 | there was a little girl named Lily. She loved to play outside in the sun. One day, she saw a big, red ball in the grass. She wanted to play with it. |
| Balanced | T 0.80 · k 40 · p 0.95 · min-p 0.05 | there was a little girl named Lucy. She had a big heart and loved to play with her toys. One day, Lucy found a new toy. It was a small, red ball. She |
| Creative | T 1.20 · k 120 · p 1.00 · min-p 0.00 | there was a brown dog named Buddy. Buddy liked to play because he could run so fast he would get in trouble.” One day, Buddy found a big race with all his friend. He |
Same weights, three stories. The Creative one gets a dog and an adventure, and also a stray quote mark and “all his friend”. When you compare checkpoints, fix one preset and one seed, or you’ll be measuring the sampler.
Diagnose poor results
Start from the symptom, then look for the measurement that explains it. These are the cases I hit or saw in these runs:
| Symptom | What to check | What it was here |
|---|---|---|
| Validation loss rises while training loss falls | how many passes over the data | 146 passes over Tiny Shakespeare. Use the step 600 checkpoint, or more data |
| Loss around 10.8 that won’t move | the loss of a uniform guess, ln(vocab) |
that’s step 1. If it stays there, check the data and learning rate |
Words glued together (RICHARDClown, manHello) |
how far training got | normal at step 100, rare by step 500 on TinyStories |
| Fluent text that ignores the question | whether the checkpoint was fine-tuned | the base model answering a chat prompt, see SFT below |
| Training time far longer than the estimate | throughput in the first minutes | SFT estimated 1 h 14 min at step 30, see below |
Change one thing at a time, and give each new run its own name. A failed run is the comparison that explains why the next one exists.
Supervised fine-tuning
Pre-training teaches a model to continue text. It doesn’t teach it to answer a question like an assistant would.
You can see that in the chat view. I asked the TinyStories base checkpoint “Tell me a story about a brave little boat.” and it replied:
ly was happy and excited. She had never heard a car in the forest before.
The boat had a lot of fun!
It picked up mid-word, because to a base model the conversation is just more text to continue.
Supervised fine-tuning, or SFT, trains the model on example conversations. Open Fine-tuning data and pick a dataset. The app recommends Everyday Conversations 2k, 2,379 short, friendly multi-turn chats from Hugging Face under Apache 2.0, split into 2,260 for training and 119 held out. Each row is a messages array with user and assistant turns. This is the example row the app previews:
{
  "messages": [
    { "role": "user", "content": "Hi! What's a good breakfast?" },
    { "role": "assistant", "content": "Something simple like eggs and toast is a great start." }
  ]
}
Only the assistant turns are learning targets. The user turns are context, and the loss is computed on the replies. You can bring your own .jsonl file in the same shape, and the direct-download build can even turn your iMessage group chats into training data.
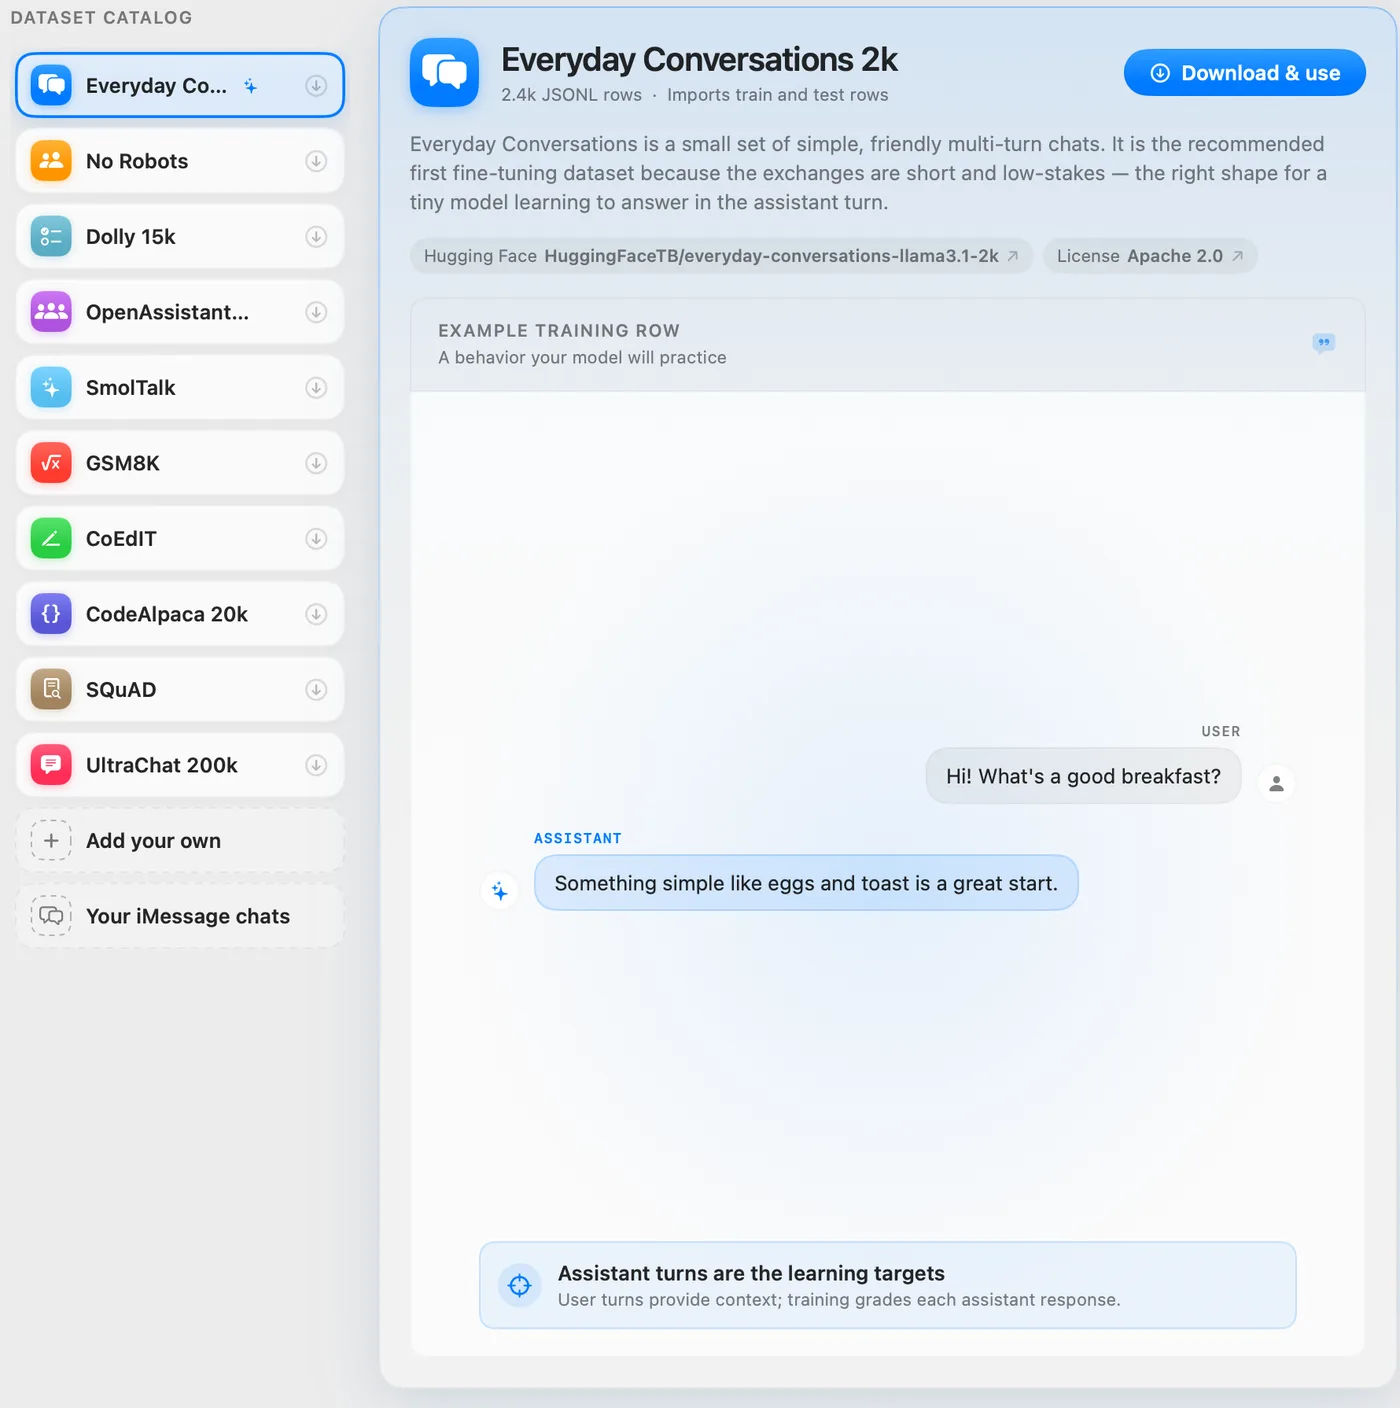
Open Supervised fine-tuning and start the run. It begins from your latest pre-training checkpoint and saves a separate SFT checkpoint, so the base model stays available.
Here’s my run on the TinyStories model, in the VM:
| Value | |
|---|---|
| Base checkpoint | step 5,330 |
| Steps | 800, batch of 10 conversations |
| Estimate shown at step 30 | about 1 h 14 min |
| Real time | 8 min 35 s |
| Training loss | 7.52 at step 1, around 3.8–4.2 at the end |
| Validation loss | 4.567 at step 100 → 3.977 at step 800 |
The early estimate was nine times too long. The “at this pace” number at step 30 was based on the slow first steps. By step 200 it said 7 minutes left, and the run finished 6 minutes later.
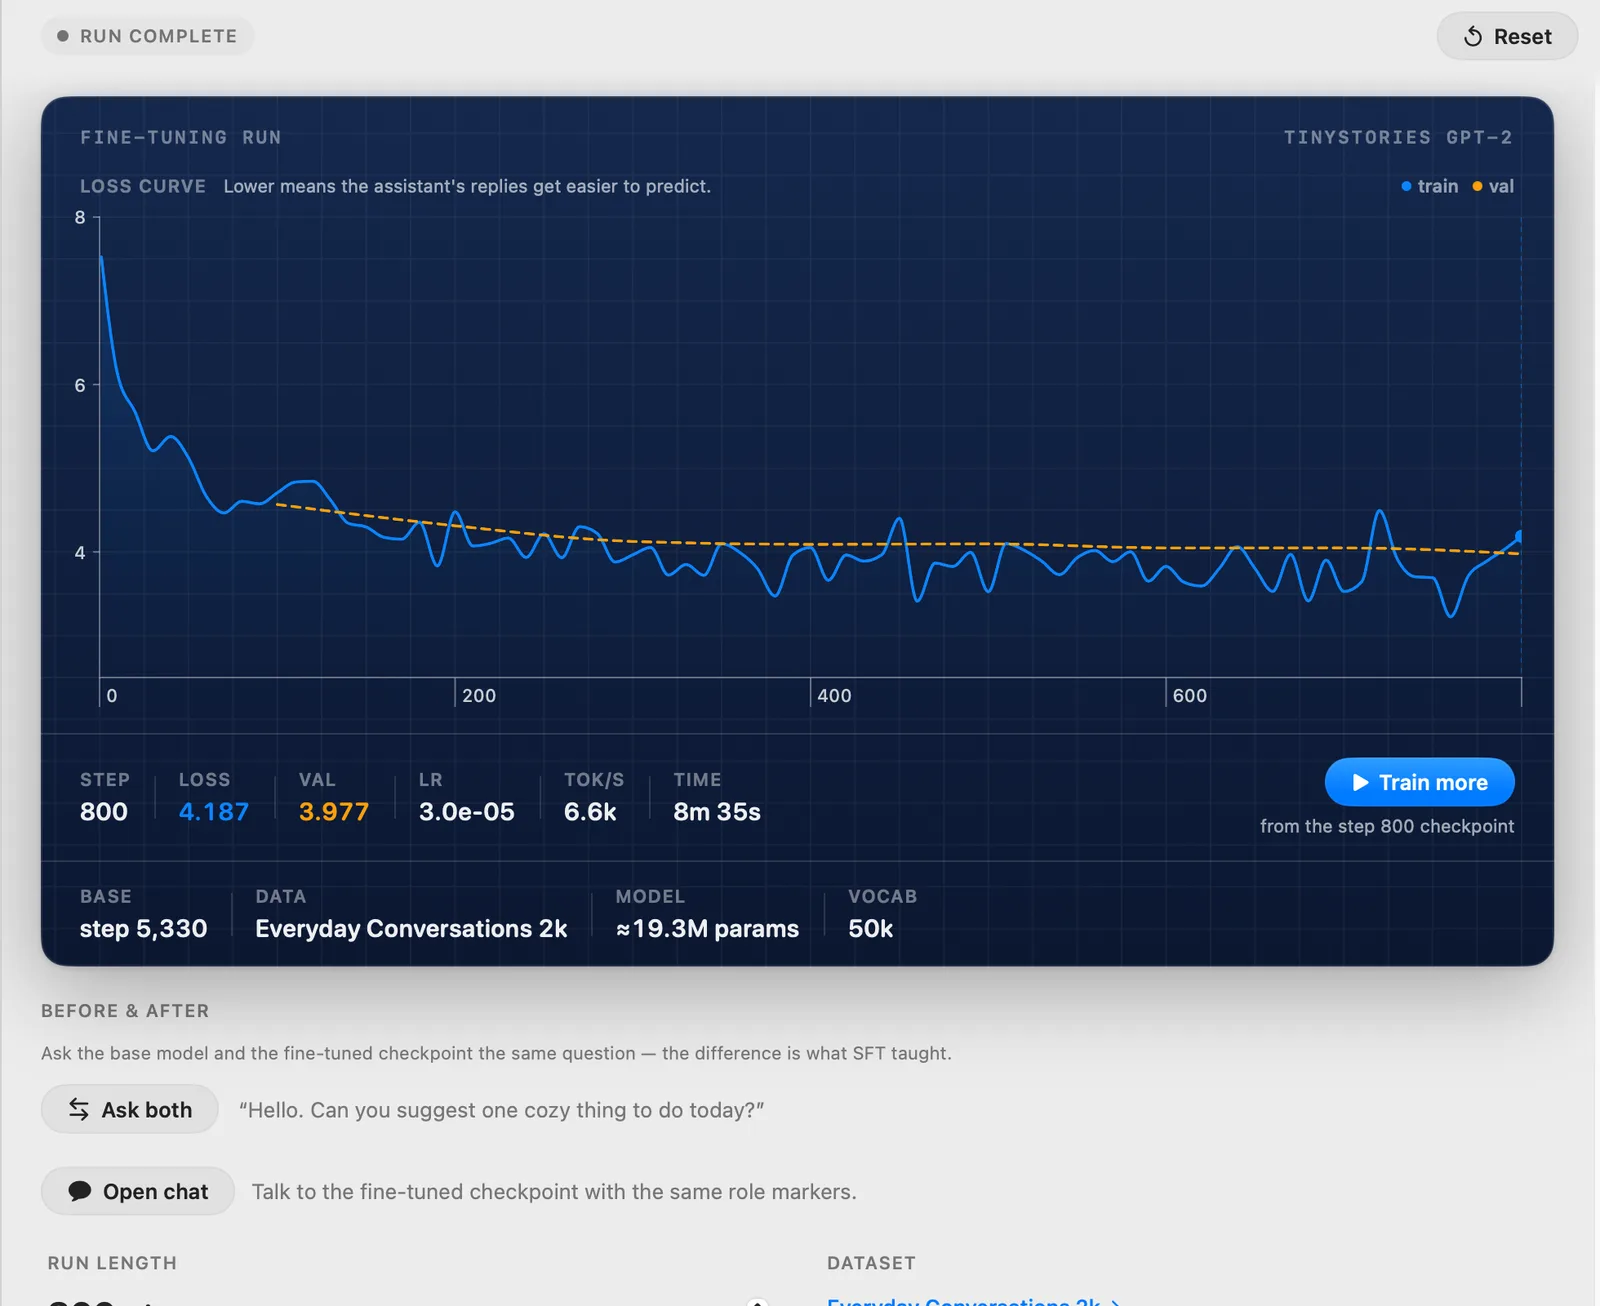
The loss stays high, around 4, because these conversations are about breakfast, rocks and dog breeds, and the model only ever read children’s stories. SFT teaches the format, and 800 steps of short chats won’t teach a story model what a metamorphic rock is.
The sample timeline shows that clearly. At step 300, asked “What is a circle?”, the model replied:
A square is a circle with six buildon, which is the same.Before & after asks both checkpoints the same question:
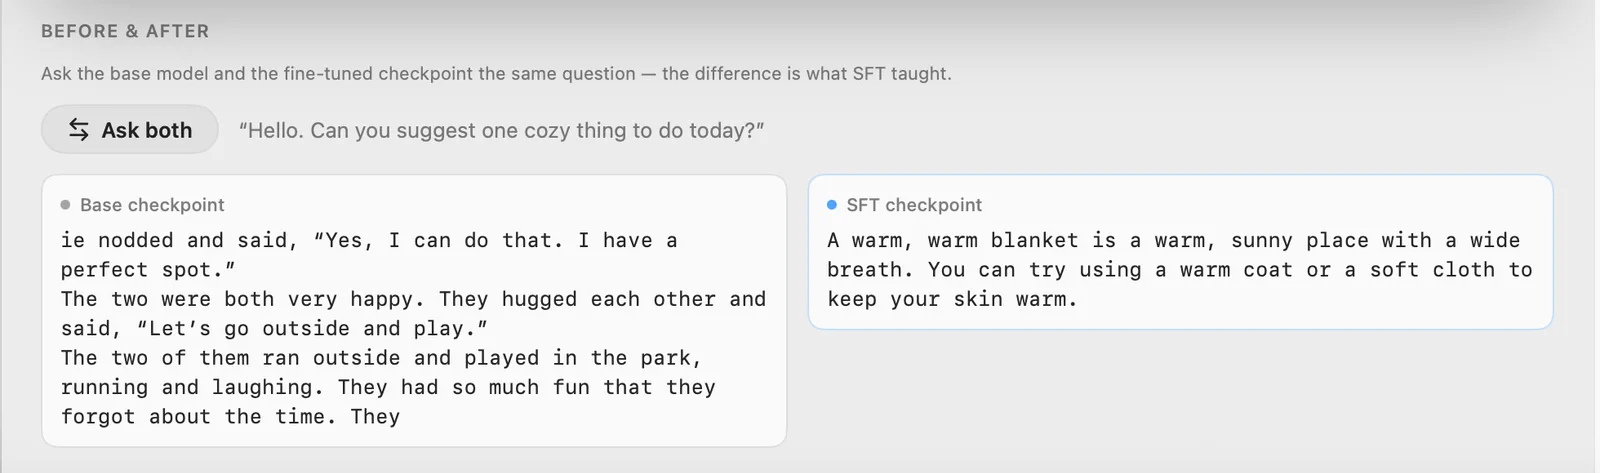
The base model kept writing a story. The SFT model answered the question, about warm blankets and coats, in two. That’s the change SFT makes: the model now treats <|assistant|> as its turn to answer and <|end|> as the place to stop.
Preference data and DPO
Direct preference optimization, or DPO, teaches the model from comparisons. You give it a preferred answer and a rejected answer, and training pushes the model toward the preferred one, relative to a frozen copy of the SFT model.
Open Direct preference optimization. The preference ballot asks your SFT checkpoint the same question twice and shows both answers. You click the one you’d rather receive.
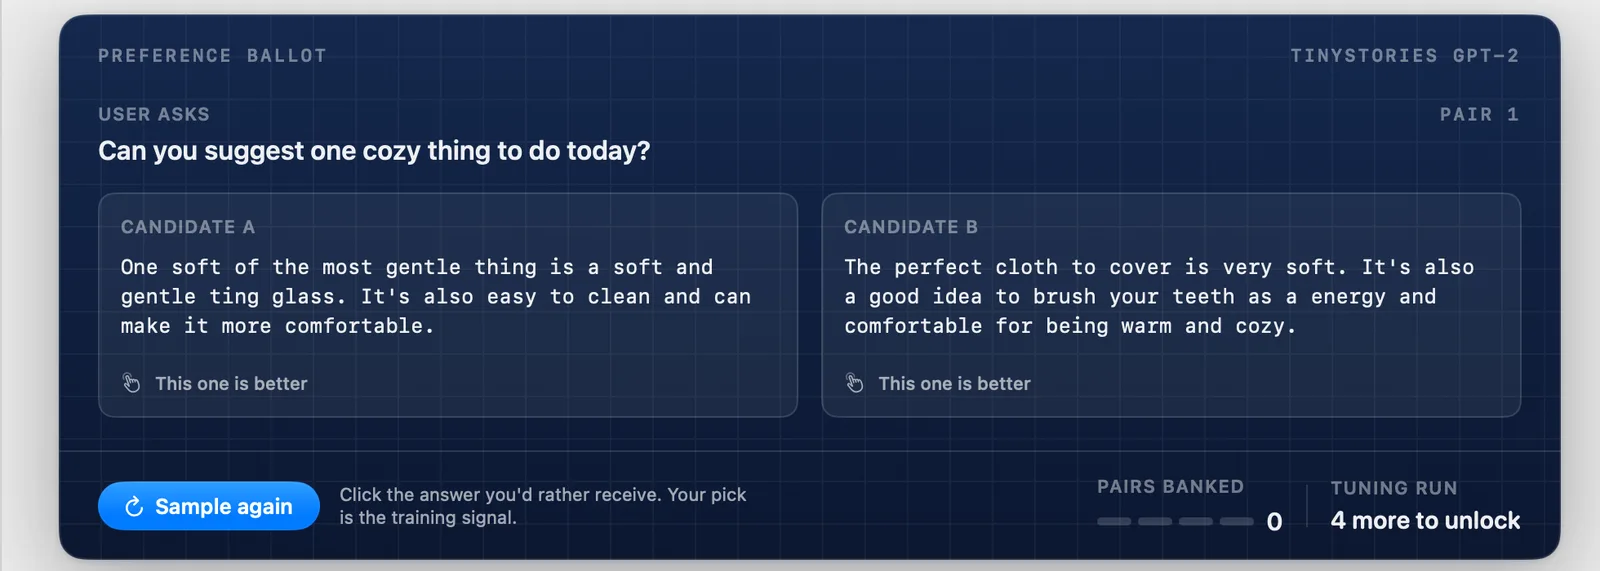
Four pairs unlock training. I used one rule for all of them: pick the answer that stays closest to the question. The app saved them to preference-pairs.jsonl in the project folder:
| Prompt | Chosen | Rejected |
|---|---|---|
| Can you suggest one cozy thing to do today? | The perfect cloth to cover is very soft. It’s also a good idea to brush your teeth as a energy and comfortable for being warm and cozy. | One soft of the most gentle thing is a soft and gentle ting glass. It’s also easy to clean and can make it more comfortable. |
| What is a good breakfast? | A rice is a good salad with bread, bread, and eggs. You can also try some over air. | A pasta is a great choice. It helps make a healthy and healthy meal and grow. |
| How do I make a new friend? | You can create a unique friend or family on a modern home to your own and family. | You can use a new idea in a comfortable place or a clear track, or make sure you have a quiet and quiet, safe and safe. |
| What should I do on a rainy day? | You can try hot winter, cool, or cool ice cream. Have fun playing in the summer, or feel free to go outside and explore the ice. | To stay warm and hot in a cold place, cool water, and cool back into the sunlight. You’ll also try making a cool weather to protect your body and its life. |
Both answers in every pair are weak. That’s what a 19-million-parameter model produces, and you’re choosing the less wrong one.
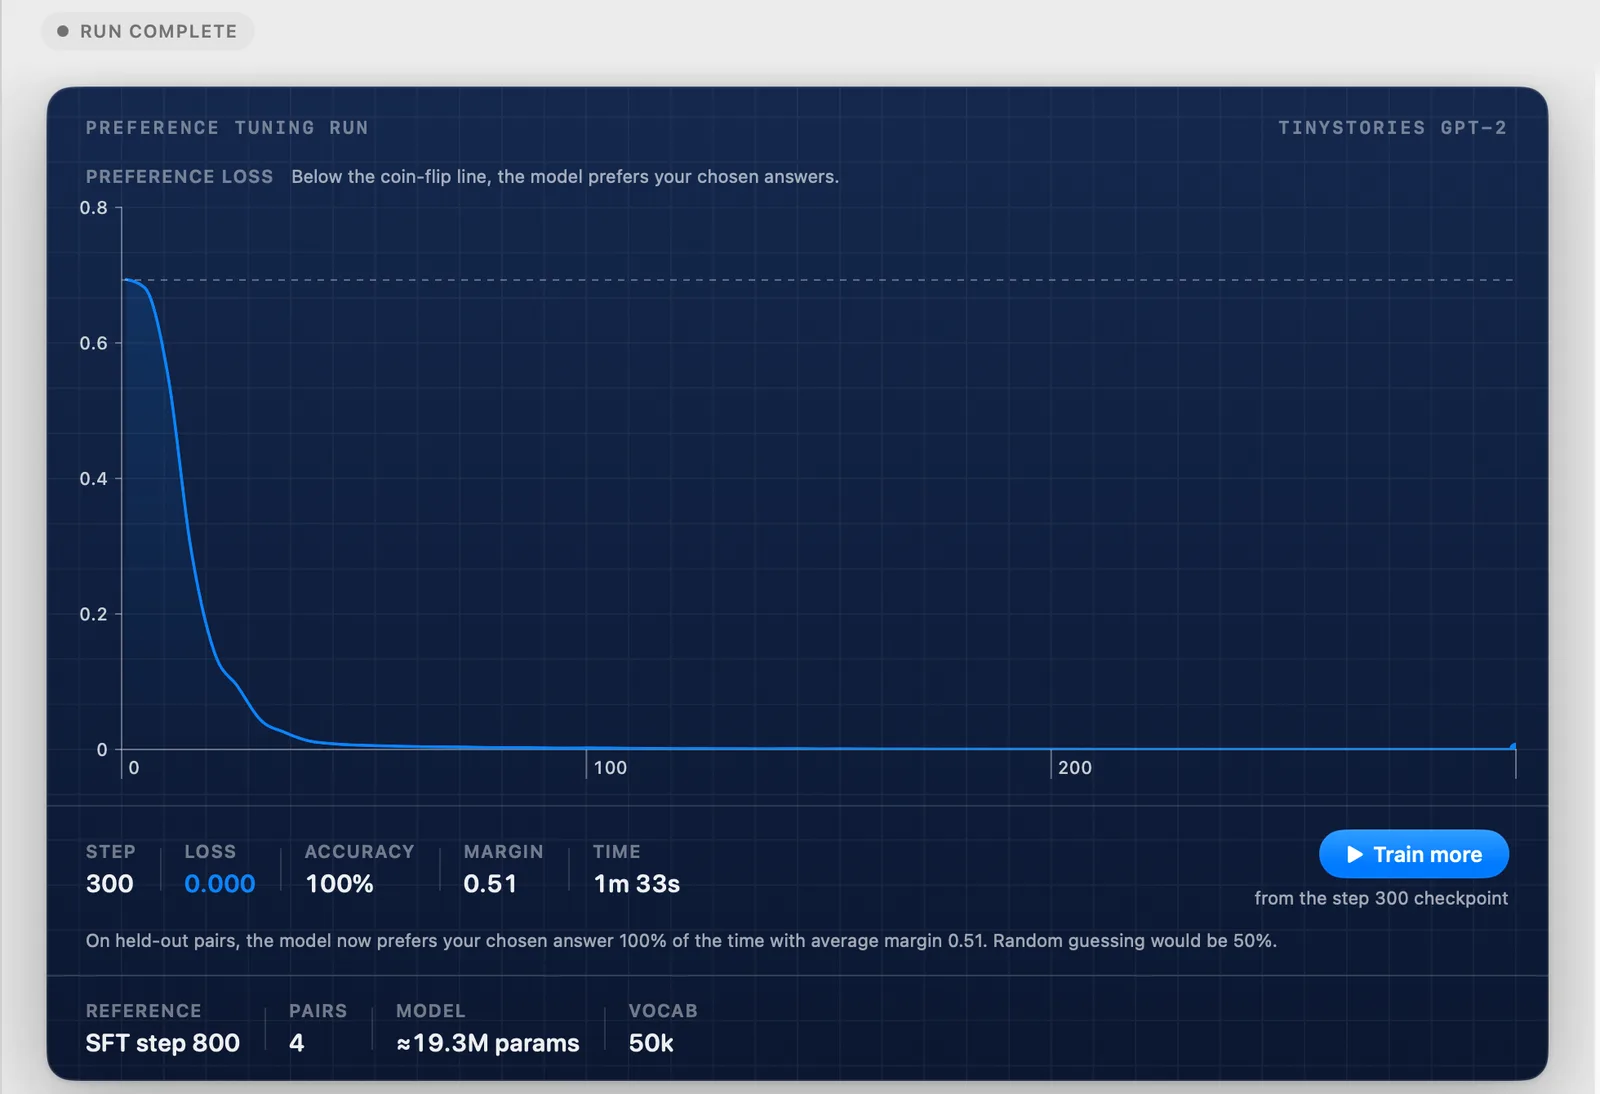
Then I ran 300 DPO steps:
| Value | |
|---|---|
| Reference model | SFT step 800 |
| Pairs | 4 |
| Real time | 1 min 33 s |
| Preference loss, step 1 | 0.694 |
| Preference loss, step 300 | 0.0003 |
| Held-out loss | 0.601 at step 50 → 0.469 at step 300 |
| Margin | 0.19 → 0.51 |
| Accuracy on held-out pairs | 100% |
The loss starts at 0.693, which is ln(2). At step 1 the trained model and its frozen reference are identical, so the model is at a coin flip between your two answers. Below that line, it prefers the answers you chose.
The training loss hit almost zero by step 50. With four pairs, the model doesn’t learn a preference so much as memorize which of four answers to rank first. The held-out numbers moved much less, and with so few pairs the 100% accuracy can’t tell you much.
The saved samples show the limit. At step 300, for the breakfast prompt, the DPO model wrote “A pasta is a good job to eat. It’s easy to eat and is a great choice.” Pasta was in the answer I rejected.
Taste test asks the SFT and DPO checkpoints the same question:
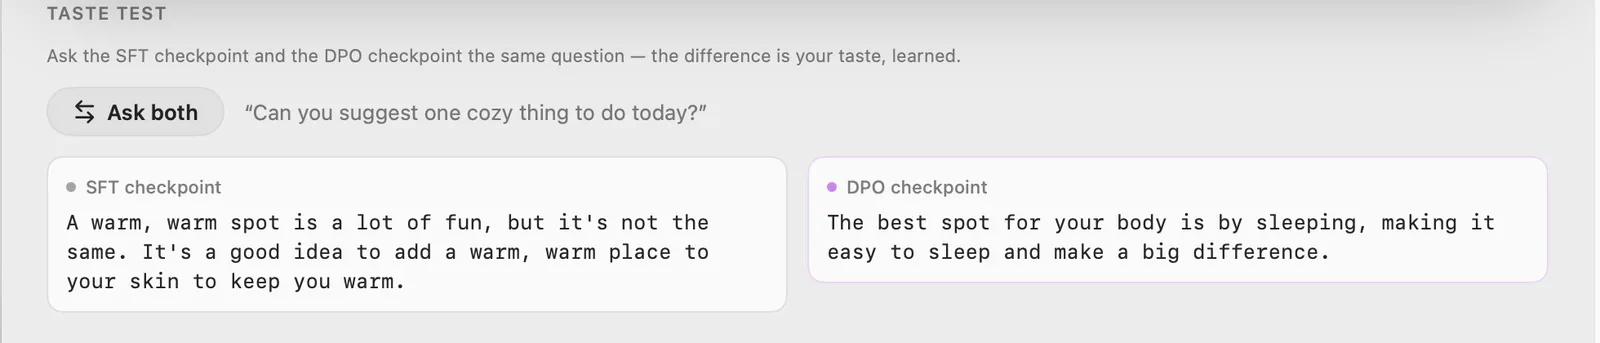
Click through the whole sequence for one prompt:
For a first experiment, SFT is enough. DPO is worth running once to see the machinery, and the app’s own textbook says the same: for a model this size, better pre-training or SFT data is a better use of the next hour than more preference pairs.
Chat with your model
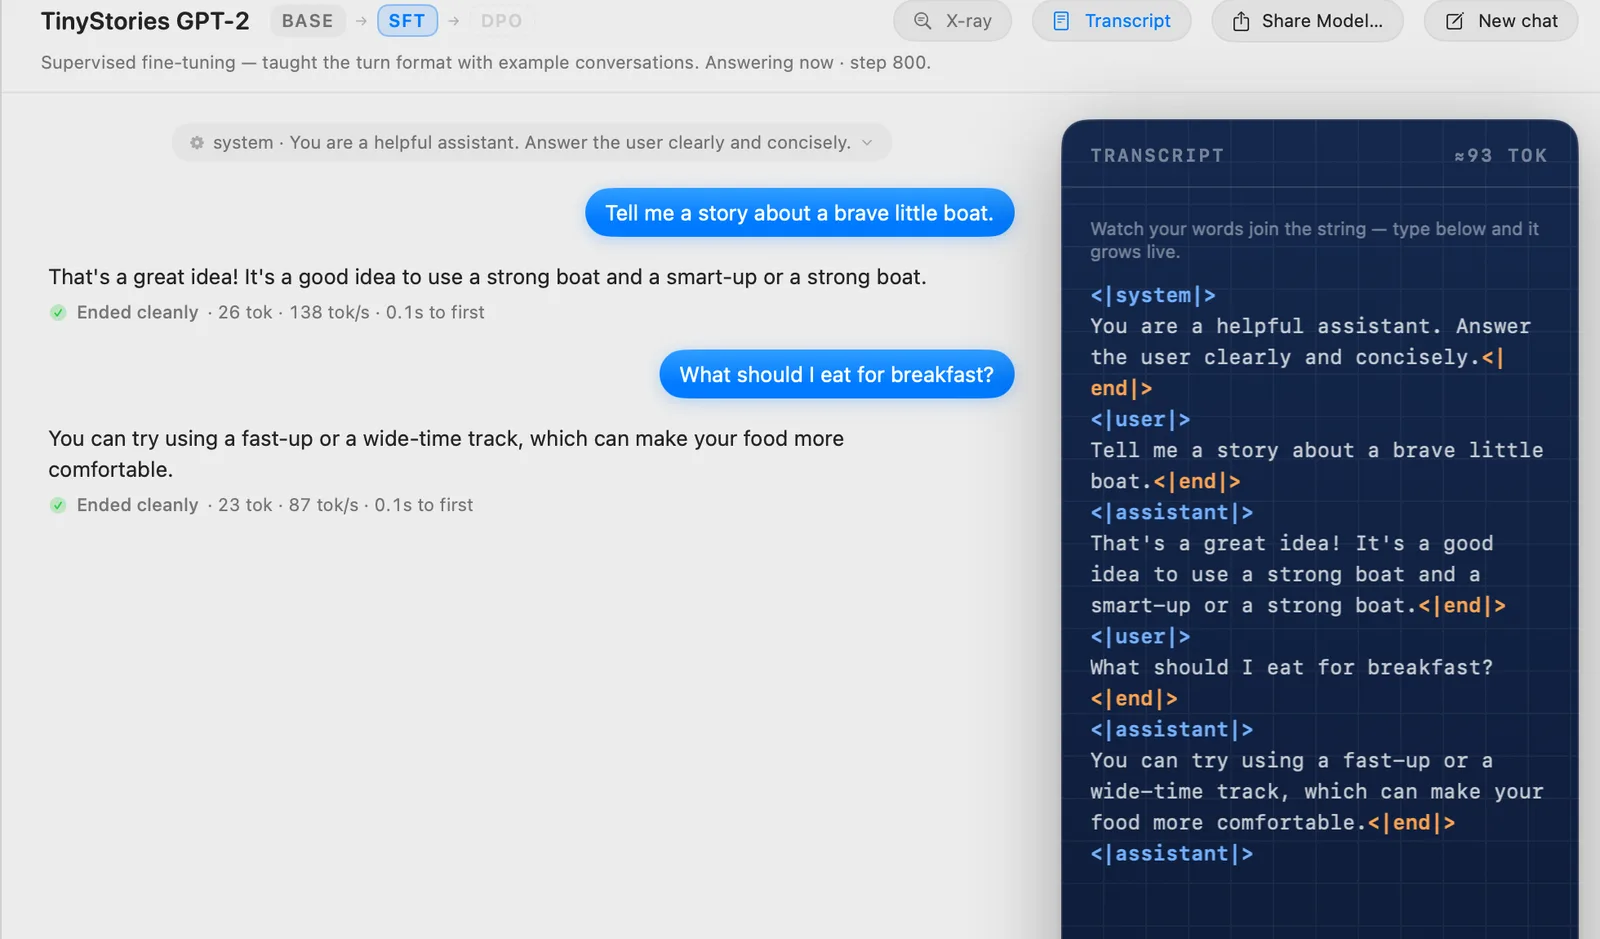
Open Chat with your model and pick a stage with the BASE → SFT → DPO switch. Switching starts a fresh chat, so every conversation belongs to one checkpoint.
The Transcript panel shows the exact text the model reads. Your message and its replies are flattened into one string with the reserved tokens, and the whole thing goes back in on every turn:
<|system|>
You are a helpful assistant. Answer the user clearly and concisely.<|end|>
<|user|>
What should I eat for breakfast?<|end|>
<|assistant|>
You can try using a fast-up or a wide-time track, which can make your food more comfortable.<|end|>
The context meter at the bottom shows how much of the 512-token window is used. My two-turn conversation with the SFT model used 93.
X-ray turns each reply into tokens, tinted by how likely each one was. Click a token to see what else the model could have said there. For the SFT model’s breakfast answer, the first token was:
You    67.1%
It      8.1%
In      6.4%
To      6.4%
If      6.0%
That    6.0%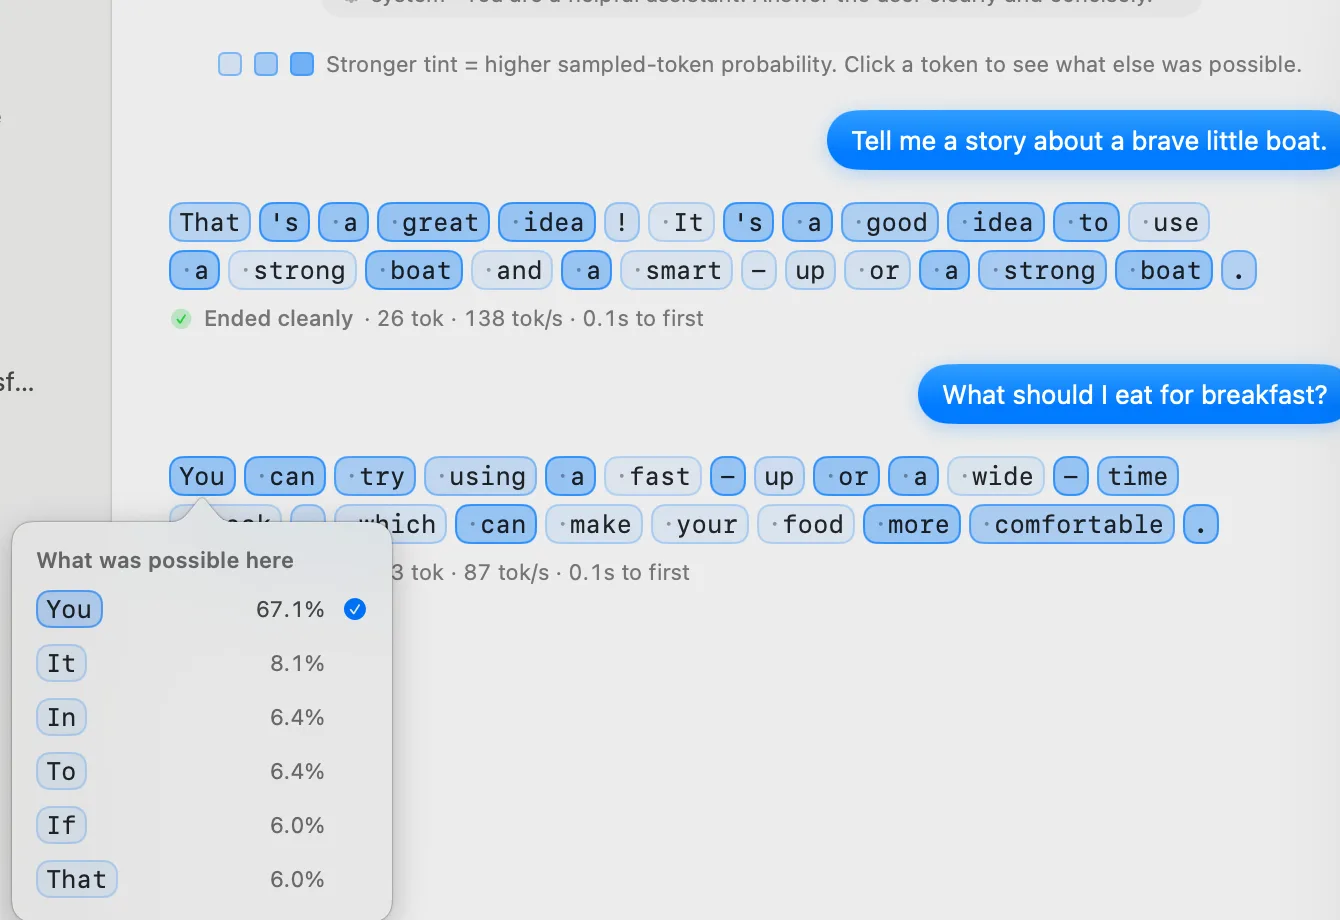
The training data explains part of it. Its 2,260 conversations have 8,625 assistant turns, and their most common first words are Hello! (2,248 times, because nearly every conversation opens with a greeting), Yes, (1,348), The (477) and You (395), and 334 replies start with “You can”. After 800 steps, a breakfast question makes “You” the clear favorite.
Compare checkpoints
Compare stages one transition at a time: base to SFT, then SFT to DPO. Use the same prompts, the same system instruction and the same sampler (here the chat default, temperature 0.8 and top-k 40).
I sent the same two-turn conversation to each stage:
| Prompt | Base (step 5,330) | SFT (800 steps) | DPO (300 steps) |
|---|---|---|---|
| Tell me a story about a brave little boat. | ly was happy and excited. She had never heard a car in the forest before. The boat had a lot of fun! (26 tokens) | That’s a great idea! It’s a good idea to use a strong boat and a smart-up or a strong boat. (26 tokens) | You can find a doctor for your boat to help you with that. (14 tokens) |
| What should I eat for breakfast? | : “I’m hungry,” she said, “I don’t want to eat a lot of food.” The boat was happy that she had listened to her hard work and decided to try some. So she put on her favorite dress and went outside to play. She had a great time, and she was very careful with her bathtub. (74 tokens) | You can try using a fast-up or a wide-time track, which can make your food more comfortable. (23 tokens) | You can try making a sandwich with red fruit, banana, or cheese. (15 tokens) |
Scored with a small rubric:
| Check | Base | SFT | DPO |
|---|---|---|---|
| Answers in the assistant role | 0 of 2 | 2 of 2 | 2 of 2 |
| Ends cleanly with `< | end | >` | 2 of 2 |
| Gives a usable answer to the question | 0 of 2 | 0 of 2 | 1 of 2 |
| Writes story-like text when asked for a story | 1 of 1 (a fragment) | 0 of 1 | 0 of 1 |
| Average reply length | 50 tokens | 25 tokens | 15 tokens |
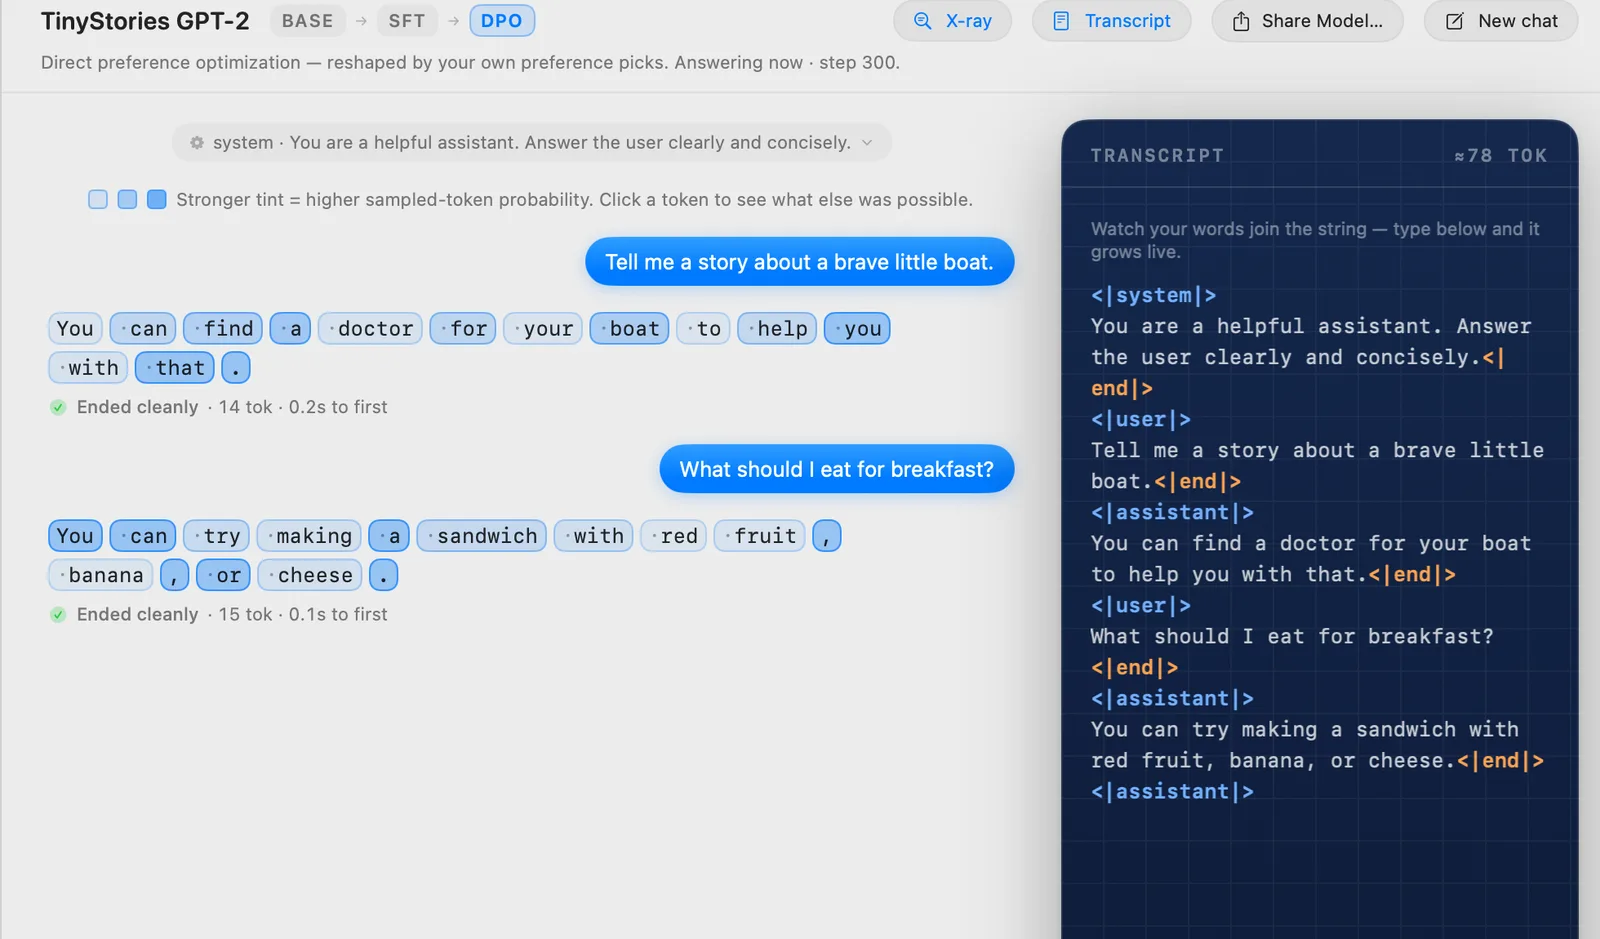
What I’d conclude from this, and what I wouldn’t:
- SFT changed the format completely. That’s visible in every reply.
- SFT cost the storytelling. The base model was the only one that wrote anything like a story, even if it ignored the boat. The SFT data has no stories in it.
- DPO made the replies shorter, and the breakfast answer is the best of the three. With one sample per cell and four preference pairs, I can’t tell how much of that is DPO and how much is the dice.
To make the comparison stronger, run each prompt with three fixed seeds in Sampling, and report counts like “2 of 3 stayed on topic” instead of the best example.
Write the lab report
The report is what turns the run into something you can learn from a month later. Here’s mine, cut down to the numbers in this guide:
# Lab report: TinyStories GPT-2

## Setup
App 1.2.3 on an M4 Pro. GPT-2 BPE (50,261 tokens). 512 context, 256 wide,
8 blocks, 4 heads: 19,289,344 parameters. TinyStories 2: 564M training tokens.

## Pre-training
5,330 steps of 32 × 512 tokens (87M tokens, 15% of one pass), paused at 4,225
and resumed. Train loss 10.86 → 1.62 at step 5,000. Best val loss 1.957 at step 5,000.
Validation was still falling: the run was stopped early, not finished.

## SFT
Everyday Conversations 2k, 800 steps, 8 min 35 s in a VM.
Val loss 4.567 → 3.977. Replies moved into the assistant turn and got shorter.
Storytelling was lost.

## DPO
4 pairs, 300 steps. Training loss 0.694 → 0.0003 (memorized).
Held-out loss 0.601 → 0.469. Replies got shorter. Effect on content not
separable from sampling noise with one sample per prompt.

## Limits
One sample per prompt and stage. Validation file differs from the training file.

## Next experiment
Same blueprint and tokenizer, 20,000 steps instead of 5,330.
Expected: val loss below 1.9 and fewer grammar errors at step 20,000.
The next experiment changes one variable, so any difference in the result comes from that change.
What kind of model can you build?
Small ones. Language Model Builder trains educational models. Its website says the default settings can produce coherent, grammatical text in about a day.
The higher-end example it gives is a MacBook Pro with an M5 Max training a GPT-2-small-class model, around 100 to 150 million parameters, on a few billion tokens in about a week.
That is tiny next to current frontier models, and that’s fine. The goal is to find out what training a model involves, and small models are the right size for that. Their mistakes are easier to inspect, and experiments finish on hardware you already own.
You can also import a base model
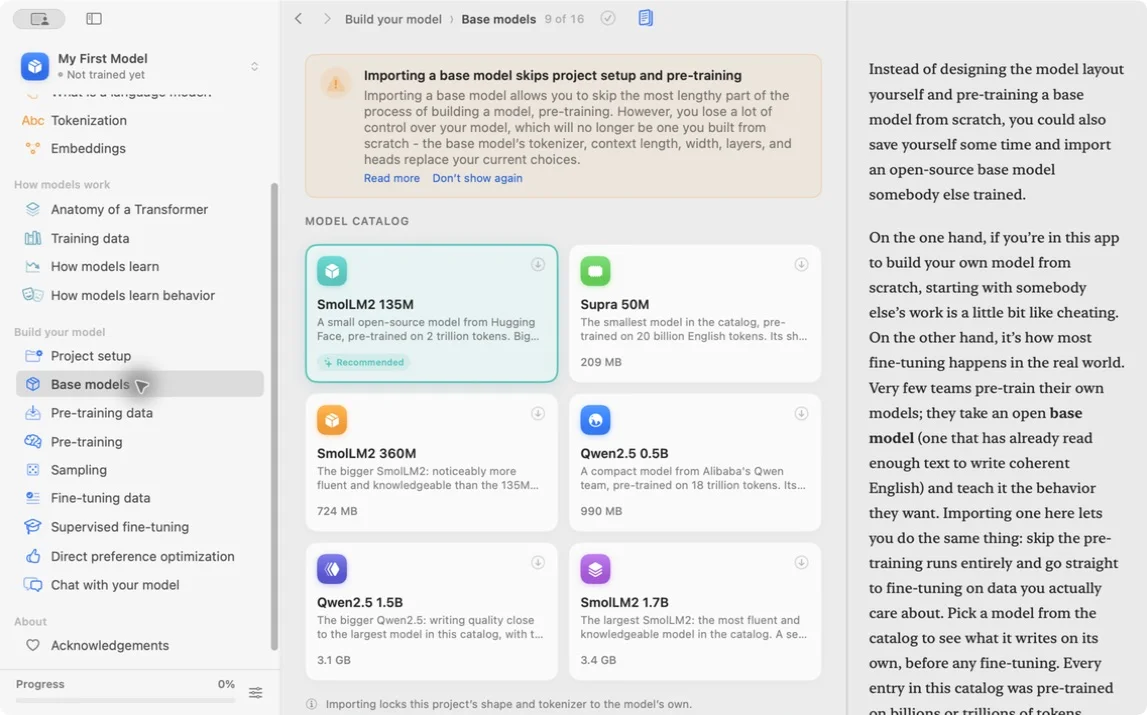
There is a shortcut. You can import an open base model and skip project setup and pre-training.
The catalog includes SmolLM2, Supra, and Qwen2.5 models. The smallest ones are easier to fine-tune, while the larger ones need much more unified memory.
Importing locks the project’s architecture and tokenizer to the selected model. You can still run SFT, DPO, sampling, and chat.
This is how most real fine-tuning projects start. Still, if you want to understand the whole process, build the small model first.
Does everything stay local?
Your projects, imported data, weights, prompts, preferences, and training results stay on your Mac. There is no account and no cloud training service.
A few network connections do happen. Dataset downloads go to their hosting service, such as Hugging Face. The direct-download version of the app checks for updates. Crash reports are sent only with your permission, and you can read them before they go out.
The privacy policy spells all of this out.
Who is this for?
Language Model Builder is for people who use language models every day without really knowing what happens inside, and who learn better by changing something and watching what happens. It also suits anyone who wants to experiment without assembling a Python toolchain or paying an API bill, and anyone who teaches AI concepts to other people.
It won’t train a production frontier model, and it only runs on recent Apple Silicon Macs. The app removes the setup work so you can watch each training stage and change its settings.
Download Language Model Builder, go through the introduction, and train the tiny blueprint on Tiny Shakespeare first. It takes about 7 minutes, and you’ll see both learning and overfitting before your coffee is cold. Then do the real run on TinyStories.
Want me to talk about your product? You can sponsor this site.
Related posts about ai: