What is MCP, the Model Context Protocol
By Flavio
Updated
Tagged: AI
Learn what MCP is, how hosts, clients and servers talk, and how to connect, inspect and trust a real server, with the actual JSON-RPC messages, Inspector screenshots and measured costs.
MCP is a standard way for AI applications to connect to external tools and data.
The full name is Model Context Protocol.
It lets an application such as Claude Code, Cursor or Codex discover what a program can do, call its tools and read the results, using one shared protocol. MCP doesn’t make the model smarter. It gives the application around the model a standard way to reach other systems.
This guide covers the user side: what the protocol is, what goes over the wire, and how to connect a server, look inside it and decide whether to trust it. We’ll run the official filesystem server against a practice folder, send it messages by hand, open it in the MCP Inspector, add it to Claude Code and remove it again. Building your own server is a different job, covered in how to build an MCP server.
The problem MCP solves
Suppose you want a coding agent to search your GitHub issues, query a Postgres database, read the docs of the framework you use and check your deployment logs.
The model can’t do any of that by itself. It needs code that connects to each service.
Before MCP, every AI application needed its own integration for every service. A GitHub integration written for one client didn’t work in another.
MCP gives both sides a shared contract. A server describes its tools in a standard format, and any compatible client can discover and call them. The Astro docs server I use almost every day is one URL, and the same entry works in Claude Code and Cursor. Nobody at Astro wrote an integration per editor. That’s the kind of explicit interface I want when agents work with existing software.
Hosts, clients and servers
An MCP setup has three roles.
The host is the AI application you use: Claude Code, Claude Desktop, Cursor, Codex. It runs the conversation, talks to the model, decides which tools the model sees and asks you for permission.
The client is the connection inside the host. The host creates one client per server, and each client speaks the protocol to exactly one server.
The server is the program that exposes a system. It can be a local process on your Mac or a remote service on someone else’s machine. It translates MCP requests into real operations against files, APIs or databases.
This is my Claude Code setup, from claude mcp list in this site’s repository:
claude mcp listChecking MCP server health…
claude.ai Claude Docs: https://api.anthropic.com/v1/pages/mcp - ✔ Connected
claude.ai Google Drive: https://drivemcp.googleapis.com/mcp/v1 - ✔ Connected
claude.ai Google Calendar: https://calendarmcp.googleapis.com/mcp/v1 - ✔ Connected
claude.ai Gmail: https://gmailmcp.googleapis.com/mcp/v1 - ✔ Connected
claude.ai Notion: https://mcp.notion.com/mcp - ! Needs authentication
plugin:context7:context7: https://mcp.context7.com/mcp?client=claude-code-plugin (HTTP) - ⊘ Disabled for this project (re-enable via /mcp)
railway: railway mcp - ✔ Connected
borumi: /Applications/Borumi.app/Contents/MacOS/borumi mcp - ✔ Connected
Astro docs: https://mcp.docs.astro.build/mcp (HTTP) - ⊘ Disabled for this project (re-enable via /mcp)
Polar: https://mcp.polar.sh/mcp/polar-mcp (HTTP) - ✔ ConnectedEach line is one client. Two are local commands (railway mcp and the Borumi app’s borumi mcp), the rest are URLs. Some come from my own config, some from a plugin, some from my claude.ai account.
The separation helps when something breaks. If the Railway server crashes, Claude Code and the model keep working, and only Railway’s tools disappear. When Notion says “Needs authentication”, the other nine connections are fine.
Credentials follow the same boundary. The Polar server gets a Polar login and nothing else. The model never sees the token, and neither does the Railway server.
What a server exposes: tools, resources and prompts
A server offers three kinds of things.
A tool is an operation the model can call with arguments: read a file, search the docs, create a deployment. This is what most servers are about.
A resource is data the client can read, identified by a URI like file:///Users/flavio/notes.md. The host decides when to read it and what to put in the conversation.
A prompt is a reusable message template the host shows you, usually as a slash command, with arguments to fill in.
Tools act, resources provide context, and prompts package a workflow you start yourself.
Here is a real tool definition, read_text_file from the official filesystem server, exactly as the server sends it:
{
  "name": "read_text_file",
  "title": "Read Text File",
  "description": "Read the complete contents of a file from the file system as text. Handles various text encodings and provides detailed error messages if the file cannot be read. Use this tool when you need to examine the contents of a single file. Use the 'head' parameter to read only the first N lines of a file, or the 'tail' parameter to read only the last N lines of a file. Operates on the file as text regardless of extension. Only works within allowed directories.",
  "inputSchema": {
    "type": "object",
    "$schema": "https://json-schema.org/draft/2020-12/schema",
    "properties": {
      "path": {
        "type": "string"
      },
      "tail": {
        "description": "If provided, returns only the last N lines of the file",
        "type": "integer",
        "minimum": 0,
        "maximum": 9007199254740991
      },
      "head": {
        "description": "If provided, returns only the first N lines of the file",
        "type": "integer",
        "minimum": 0,
        "maximum": 9007199254740991
      }
    },
    "required": [
      "path"
    ]
  },
  "annotations": {
    "readOnlyHint": true,
    "idempotentHint": true,
    "destructiveHint": false,
    "openWorldHint": false
  },
  "outputSchema": {
    "$schema": "https://json-schema.org/draft/2020-12/schema",
    "type": "object",
    "properties": {
      "content": {
        "type": "string"
      }
    },
    "required": [
      "content"
    ],
    "additionalProperties": false
  }
}
The model reads the description to decide when the tool is useful, and the inputSchema to know which arguments to send. The annotations are hints for the host: readOnlyHint: true says this tool doesn’t change anything. Hosts use them to decide how loudly to ask before a call.
They’re hints written by the server, and the specification says to treat them as untrusted unless you trust the server. A malicious server can mark a delete tool as read-only.
The protocol also defines features the client offers back to the server. The one that matters in the current version is elicitation: the server asks the host to show you a form, for example to confirm a purchase. I used it in MCP Tasks and Elicitations in Claude Code, and my own domain-buying server depends on it.
The protocol on the wire
MCP messages are JSON-RPC 2.0. A request has an id, a method and params. A response has the same id and either a result or an error.
The current specification is version 2026-07-28. It made the protocol stateless: there’s no handshake anymore, and every request carries its own protocol version and client capabilities in a _meta field. A client can call server/discover first to learn which versions the server supports, but it doesn’t have to. I wrote about what changed and why in Stateless MCP.
Earlier versions, up to 2025-11-25, opened every connection with an initialize request. Servers that support both are called dual-era, and many servers and clients still speak only the old one, as we’ll see.
Talking to a server by hand
The best way to understand the protocol is to skip the AI and talk to a server yourself.
We need a server we can trust. @modelcontextprotocol/server-filesystem is maintained by the MCP project in the official servers repository, and version 2.2.0 speaks both protocol eras.
I made a practice folder with copies of two of my posts, cron.md and tmux.md. The server only gets that folder, and --read-only removes every tool that writes.
A local MCP server reads JSON-RPC messages from stdin and writes responses to stdout, one per line. So the client is a small Node.js script that spawns the server, writes a request, and sends the next one when a response arrives:
import { spawn } from 'node:child_process'

const folder = '/tmp/mcp-practice'
const server = spawn('npx', ['-y', '@modelcontextprotocol/[email protected]', '--read-only', folder])

const _meta = {
  'io.modelcontextprotocol/protocolVersion': '2026-07-28',
  'io.modelcontextprotocol/clientInfo': { name: 'mcp-session', version: '1.0.0' },
  'io.modelcontextprotocol/clientCapabilities': {}
}

const requests = [
  { method: 'server/discover', params: { _meta } },
  { method: 'tools/list', params: { _meta } },
  { method: 'tools/call', params: { _meta, name: 'read_text_file', arguments: { path: `${folder}/cron.md`, head: 4 } } },
  { method: 'tools/call', params: { _meta, name: 'read_text_file', arguments: { path: '/Users/flaviocopes/.ssh/config' } } }
]

let id = 0
const next = () => {
  const request = requests[id]
  if (!request) return server.kill()
  const message = JSON.stringify({ jsonrpc: '2.0', id: ++id, ...request })
  console.log(`--> ${message}`)
  server.stdin.write(message + '\n')
}

let buffer = ''
server.stdout.on('data', (chunk) => {
  buffer += chunk
  let newline
  while ((newline = buffer.indexOf('\n')) >= 0) {
    console.log(`<-- ${buffer.slice(0, newline)}`)
    buffer = buffer.slice(newline + 1)
    next()
  }
})

server.stderr.on('data', (chunk) => process.stderr.write(`[stderr] ${chunk}`))
next()
Notice the last two requests. One reads the first four lines of cron.md. The other tries to read my SSH config, outside the folder.
The server prints its startup messages on stderr:
[stderr] Secure MCP Filesystem Server running on stdio
[stderr] Read-only mode: only tools that cannot change the filesystem are served
Effective allowed directories (from the command line):
  /tmp/mcp-practice
  /private/tmp/mcp-practice
On macOS /tmp is a symlink to /private/tmp, and the server allows both spellings of the same folder.
Here’s what went over stdout. I cut the tools/list response, which is 10,297 bytes on one line:
--> {"jsonrpc":"2.0","id":1,"method":"server/discover","params":{"_meta":{"io.modelcontextprotocol/protocolVersion":"2026-07-28","io.modelcontextprotocol/clientInfo":{"name":"mcp-session","version":"1.0.0"},"io.modelcontextprotocol/clientCapabilities":{}}}}
<-- {"result":{"supportedVersions":["2026-07-28"],"capabilities":{"tools":{"listChanged":true},"resources":{"listChanged":true}},"resultType":"complete","ttlMs":0,"cacheScope":"private","_meta":{"io.modelcontextprotocol/serverInfo":{"name":"secure-filesystem-server","version":"2.2.0"}}},"jsonrpc":"2.0","id":1}
--> {"jsonrpc":"2.0","id":2,"method":"tools/list","params":{"_meta":{"io.modelcontextprotocol/protocolVersion":"2026-07-28","io.modelcontextprotocol/clientInfo":{"name":"mcp-session","version":"1.0.0"},"io.modelcontextprotocol/clientCapabilities":{}}}}
<-- {"result":{"tools":[{"name":"read_file","title":"Read File (Deprecated)","description":"Read the complete contents of a file as text. DEPRECATED: Use read_text_file instead.", ...
--> {"jsonrpc":"2.0","id":3,"method":"tools/call","params":{"_meta":{"io.modelcontextprotocol/protocolVersion":"2026-07-28","io.modelcontextprotocol/clientInfo":{"name":"mcp-session","version":"1.0.0"},"io.modelcontextprotocol/clientCapabilities":{}},"name":"read_text_file","arguments":{"path":"/tmp/mcp-practice/cron.md","head":4}}}
<-- {"result":{"content":[{"type":"text","text":"---\ntitle: \"How to schedule cron jobs on Linux and macOS\"\ndescription: \"Learn cron on Linux and macOS: crontab syntax, schedules, the cron environment, logs, overlapping runs, time zones, launchd and systemd timers.\"\ndate: 2026-10-05T12:00:00+02:00"}],"structuredContent":{"content":"---\ntitle: \"How to schedule cron jobs on Linux and macOS\"\ndescription: \"Learn cron on Linux and macOS: crontab syntax, schedules, the cron environment, logs, overlapping runs, time zones, launchd and systemd timers.\"\ndate: 2026-10-05T12:00:00+02:00"},"resultType":"complete","_meta":{"io.modelcontextprotocol/serverInfo":{"name":"secure-filesystem-server","version":"2.2.0"}}},"jsonrpc":"2.0","id":3}
--> {"jsonrpc":"2.0","id":4,"method":"tools/call","params":{"_meta":{"io.modelcontextprotocol/protocolVersion":"2026-07-28","io.modelcontextprotocol/clientInfo":{"name":"mcp-session","version":"1.0.0"},"io.modelcontextprotocol/clientCapabilities":{}},"name":"read_text_file","arguments":{"path":"/Users/flaviocopes/.ssh/config"}}}
<-- {"result":{"content":[{"type":"text","text":"Access denied - path outside allowed directories: /Users/flaviocopes/.ssh/config not in /tmp/mcp-practice, /private/tmp/mcp-practice"}],"isError":true,"resultType":"complete","_meta":{"io.modelcontextprotocol/serverInfo":{"name":"secure-filesystem-server","version":"2.2.0"}}},"jsonrpc":"2.0","id":4}
That’s the whole protocol for a typical session: find out what the server is, list what it can do, call a tool.
A few details are worth reading closely.
server/discover returns the versions the server supports, its capabilities and its name. listChanged: true means the tool list can change while you’re connected, and the server will tell you when it does.
The tool result has two copies of the same data. content is an array of text, images or other blocks for the model to read. structuredContent is JSON that matches the tool’s outputSchema, for code that wants to parse it.
The denied read came back as a normal result with isError: true, not as a JSON-RPC error. The call reached the tool, the tool refused, and the model gets to read why.
The whole session is fast. From spawning the process to the first response took between 121 and 128 ms over five runs with the package installed locally. Through npx -y it took 518 ms on a cold cache and 317 to 341 ms on a warm one. Once running, each tools/call came back in 1 to 3 ms.
What the errors look like
Every way a call can go wrong looks different on the wire, and the difference tells you which layer failed. I sent the server a few bad requests on purpose:
| Request | What came back | Kind |
|---|---|---|
read_text_file with {"file": "cron.md"} | Input validation error: ... path: Invalid input: expected string, received undefined | tool result, isError: true |
read_text_file on missing.md | ENOENT: no such file or directory, open '/private/tmp/mcp-practice/missing.md' | tool result, isError: true |
read_text_file on sneaky.md, a symlink to a file outside the folder | Access denied - symlink target outside allowed directories | tool result, isError: true |
delete_file | {"code":-32602,"message":"Tool delete_file not found"} | JSON-RPC error |
tools/list with no _meta | {"code":-32602,"message":"Request is missing the required _meta envelope for protocol revision 2026-07-28 ..."} | JSON-RPC error |
tools/list with version 2027-01-01 | {"code":-32022,"message":"Unsupported protocol version: 2027-01-01","data":{"supported":["2026-07-28"],...}} | JSON-RPC error |
Tool errors go back to the model, which can fix its arguments and try again. Protocol errors mean the client did something wrong, and they usually end up in the host’s log, not in the conversation.
The symlink test is the one I care about most. A server that checked only the path string would have followed sneaky.md out of the folder. This one resolves the real path first.
Three versions to keep apart
When something stops working after an update, it helps to know which of three version numbers changed:
- the protocol revision the two sides speak,
2026-07-28here - the SDK the server is built with,
@modelcontextprotocol/server2.4.0 inside this package - the server’s own version,
secure-filesystem-server2.2.0, which is whatserverInforeports
Upgrading the server package can add a tool without changing the protocol. Upgrading the SDK can switch protocol eras without changing any tool. The only reliable way to notice a new tool is to save the tools/list output and compare it after each upgrade.
Inspect a server with the MCP Inspector
Writing a client script is educational, but the MCP Inspector does the same job with a UI. It’s the official debugging tool, and it’s what I’d use every time before giving a new server to an agent.
You can start it with npx. I installed it next to the filesystem server in my practice workspace, so both run from node_modules. Everything after -- is the server command:
npm install @modelcontextprotocol/[email protected] @modelcontextprotocol/[email protected]
npx mcp-inspector --web --protocol-era modern -- /private/tmp/mcp-demo/node_modules/.bin/mcp-server-filesystem --read-only /private/tmp/mcp-practice
Starting MCP inspector...
MCP Inspector Web is up and running at:
http://127.0.0.1:6274?MCP_INSPECTOR_API_TOKEN=<token>It starts a local web UI. The token in the URL protects the local proxy that launches processes on your behalf, so don’t share that link.
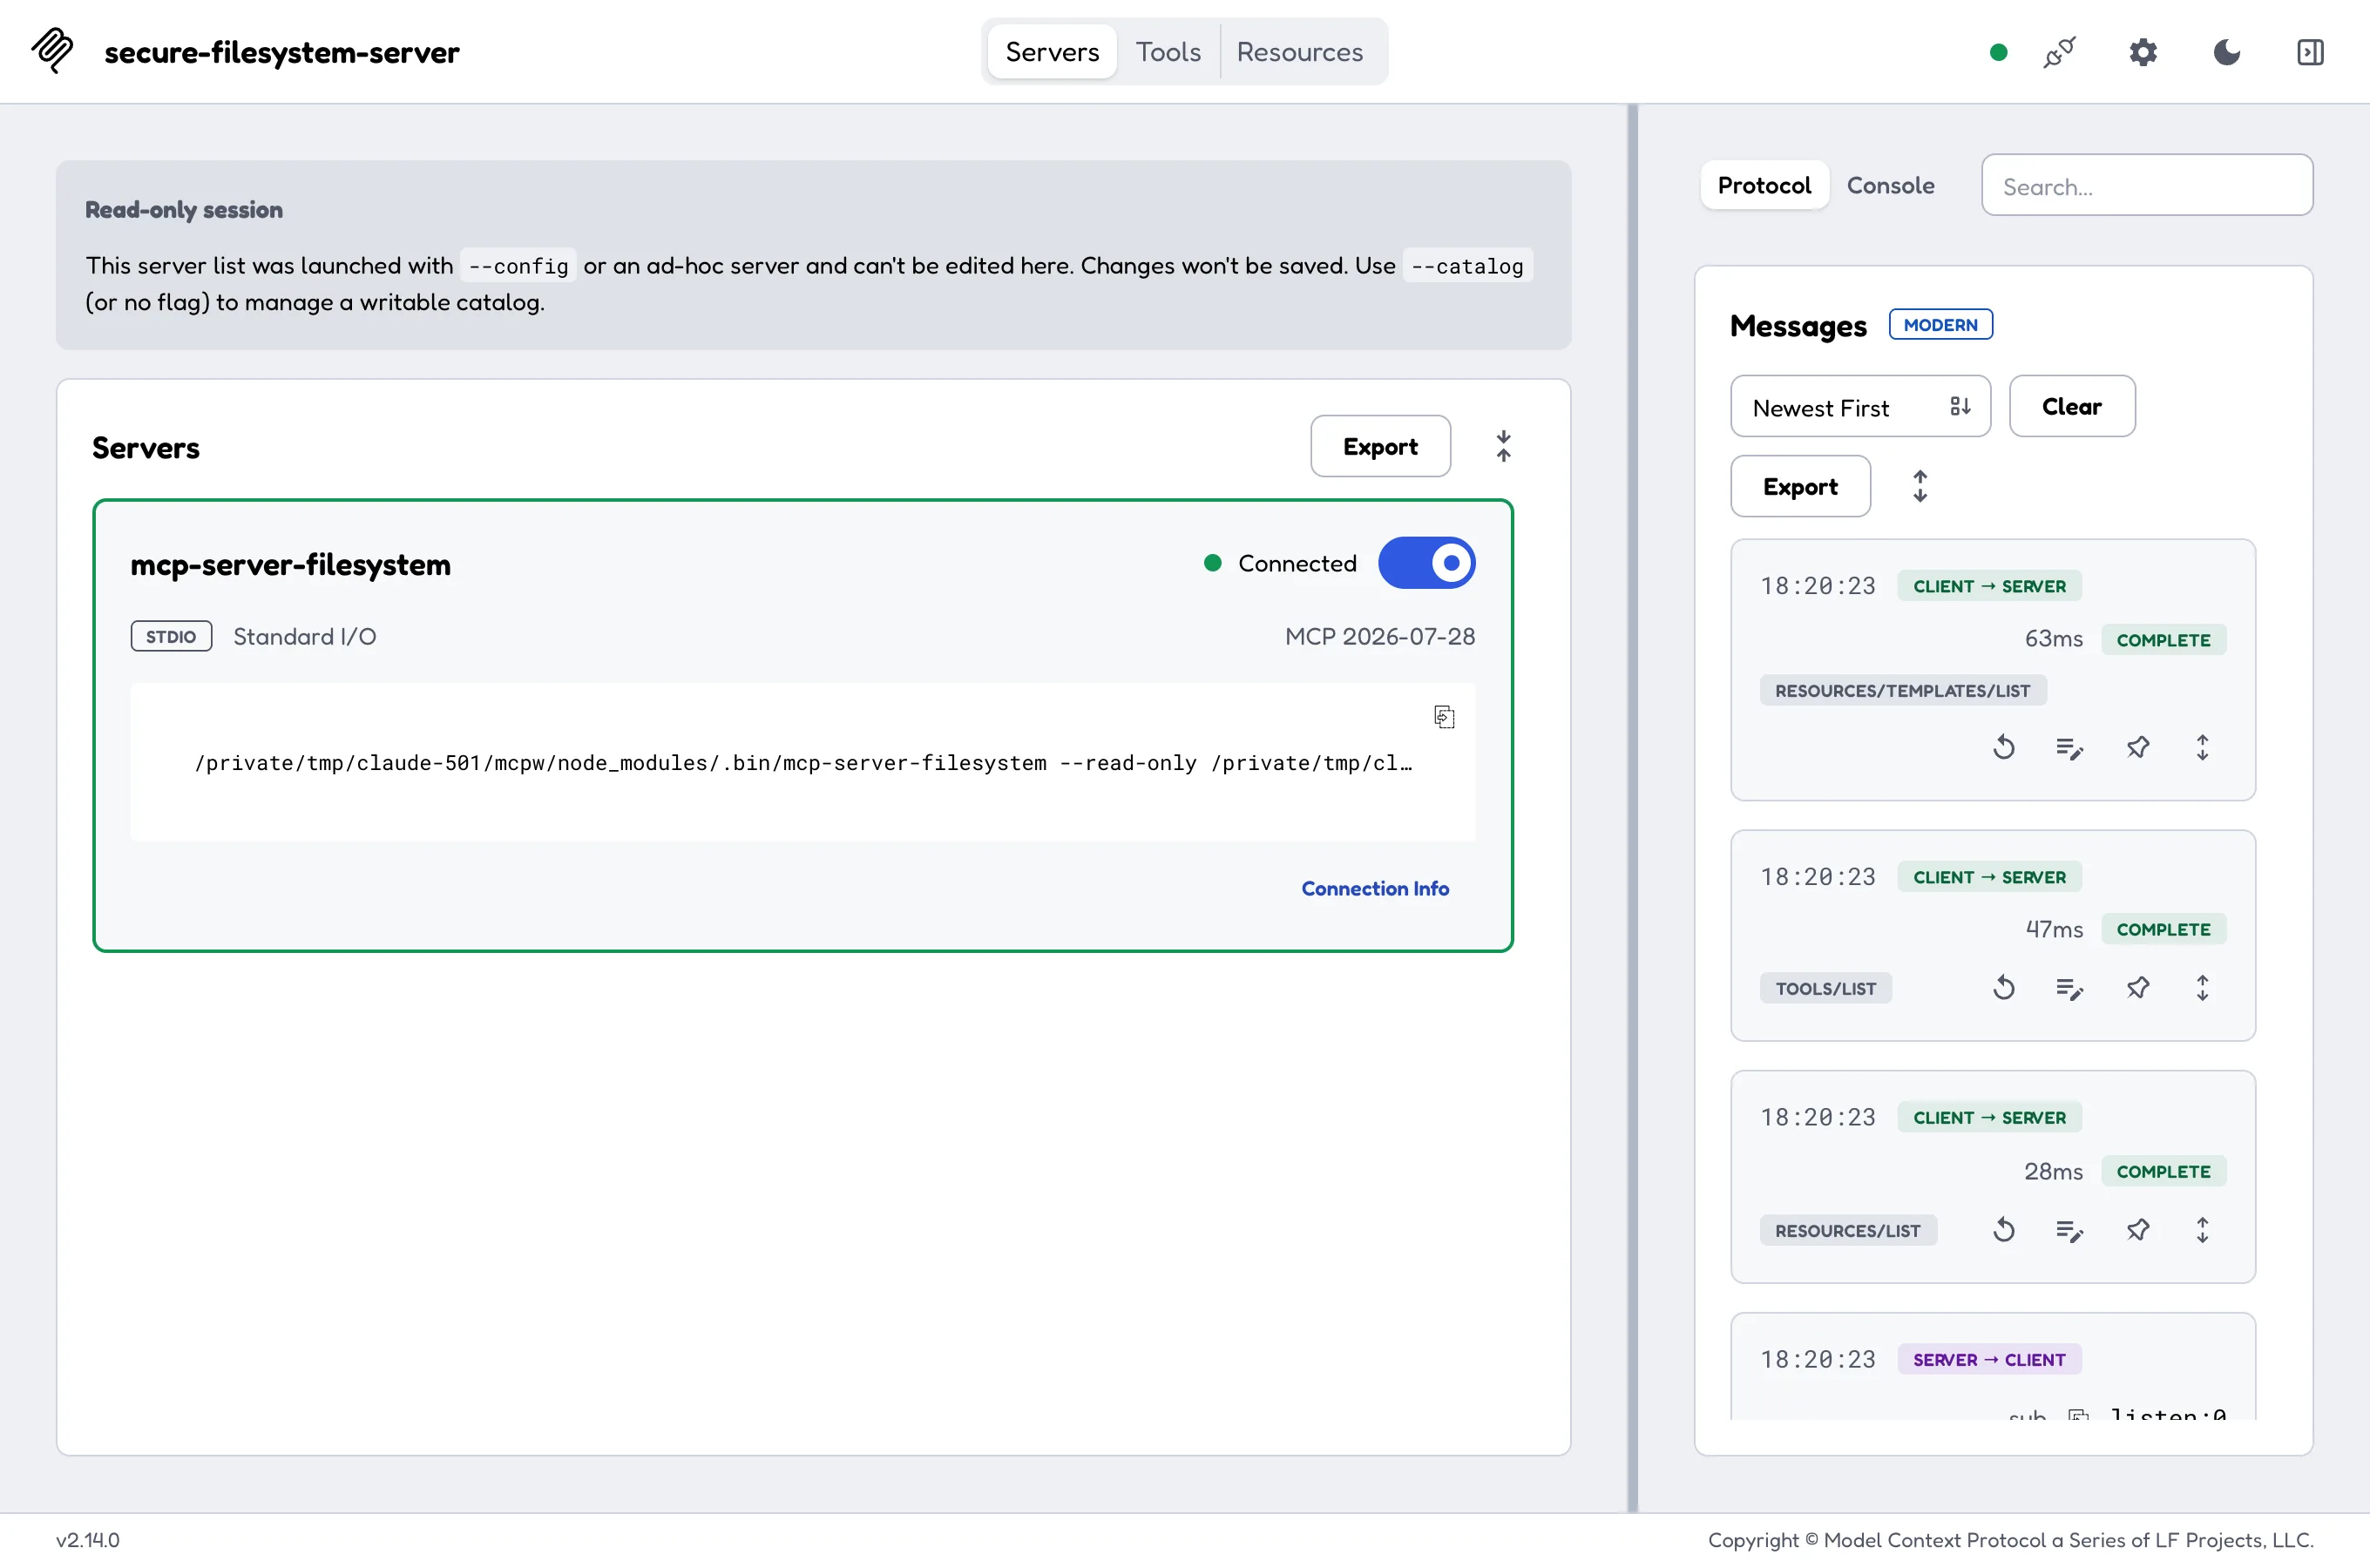
Flip the switch on the server card and it connects. The card shows the transport and the protocol version it negotiated, MCP 2026-07-28, and the panel on the right logs every message:
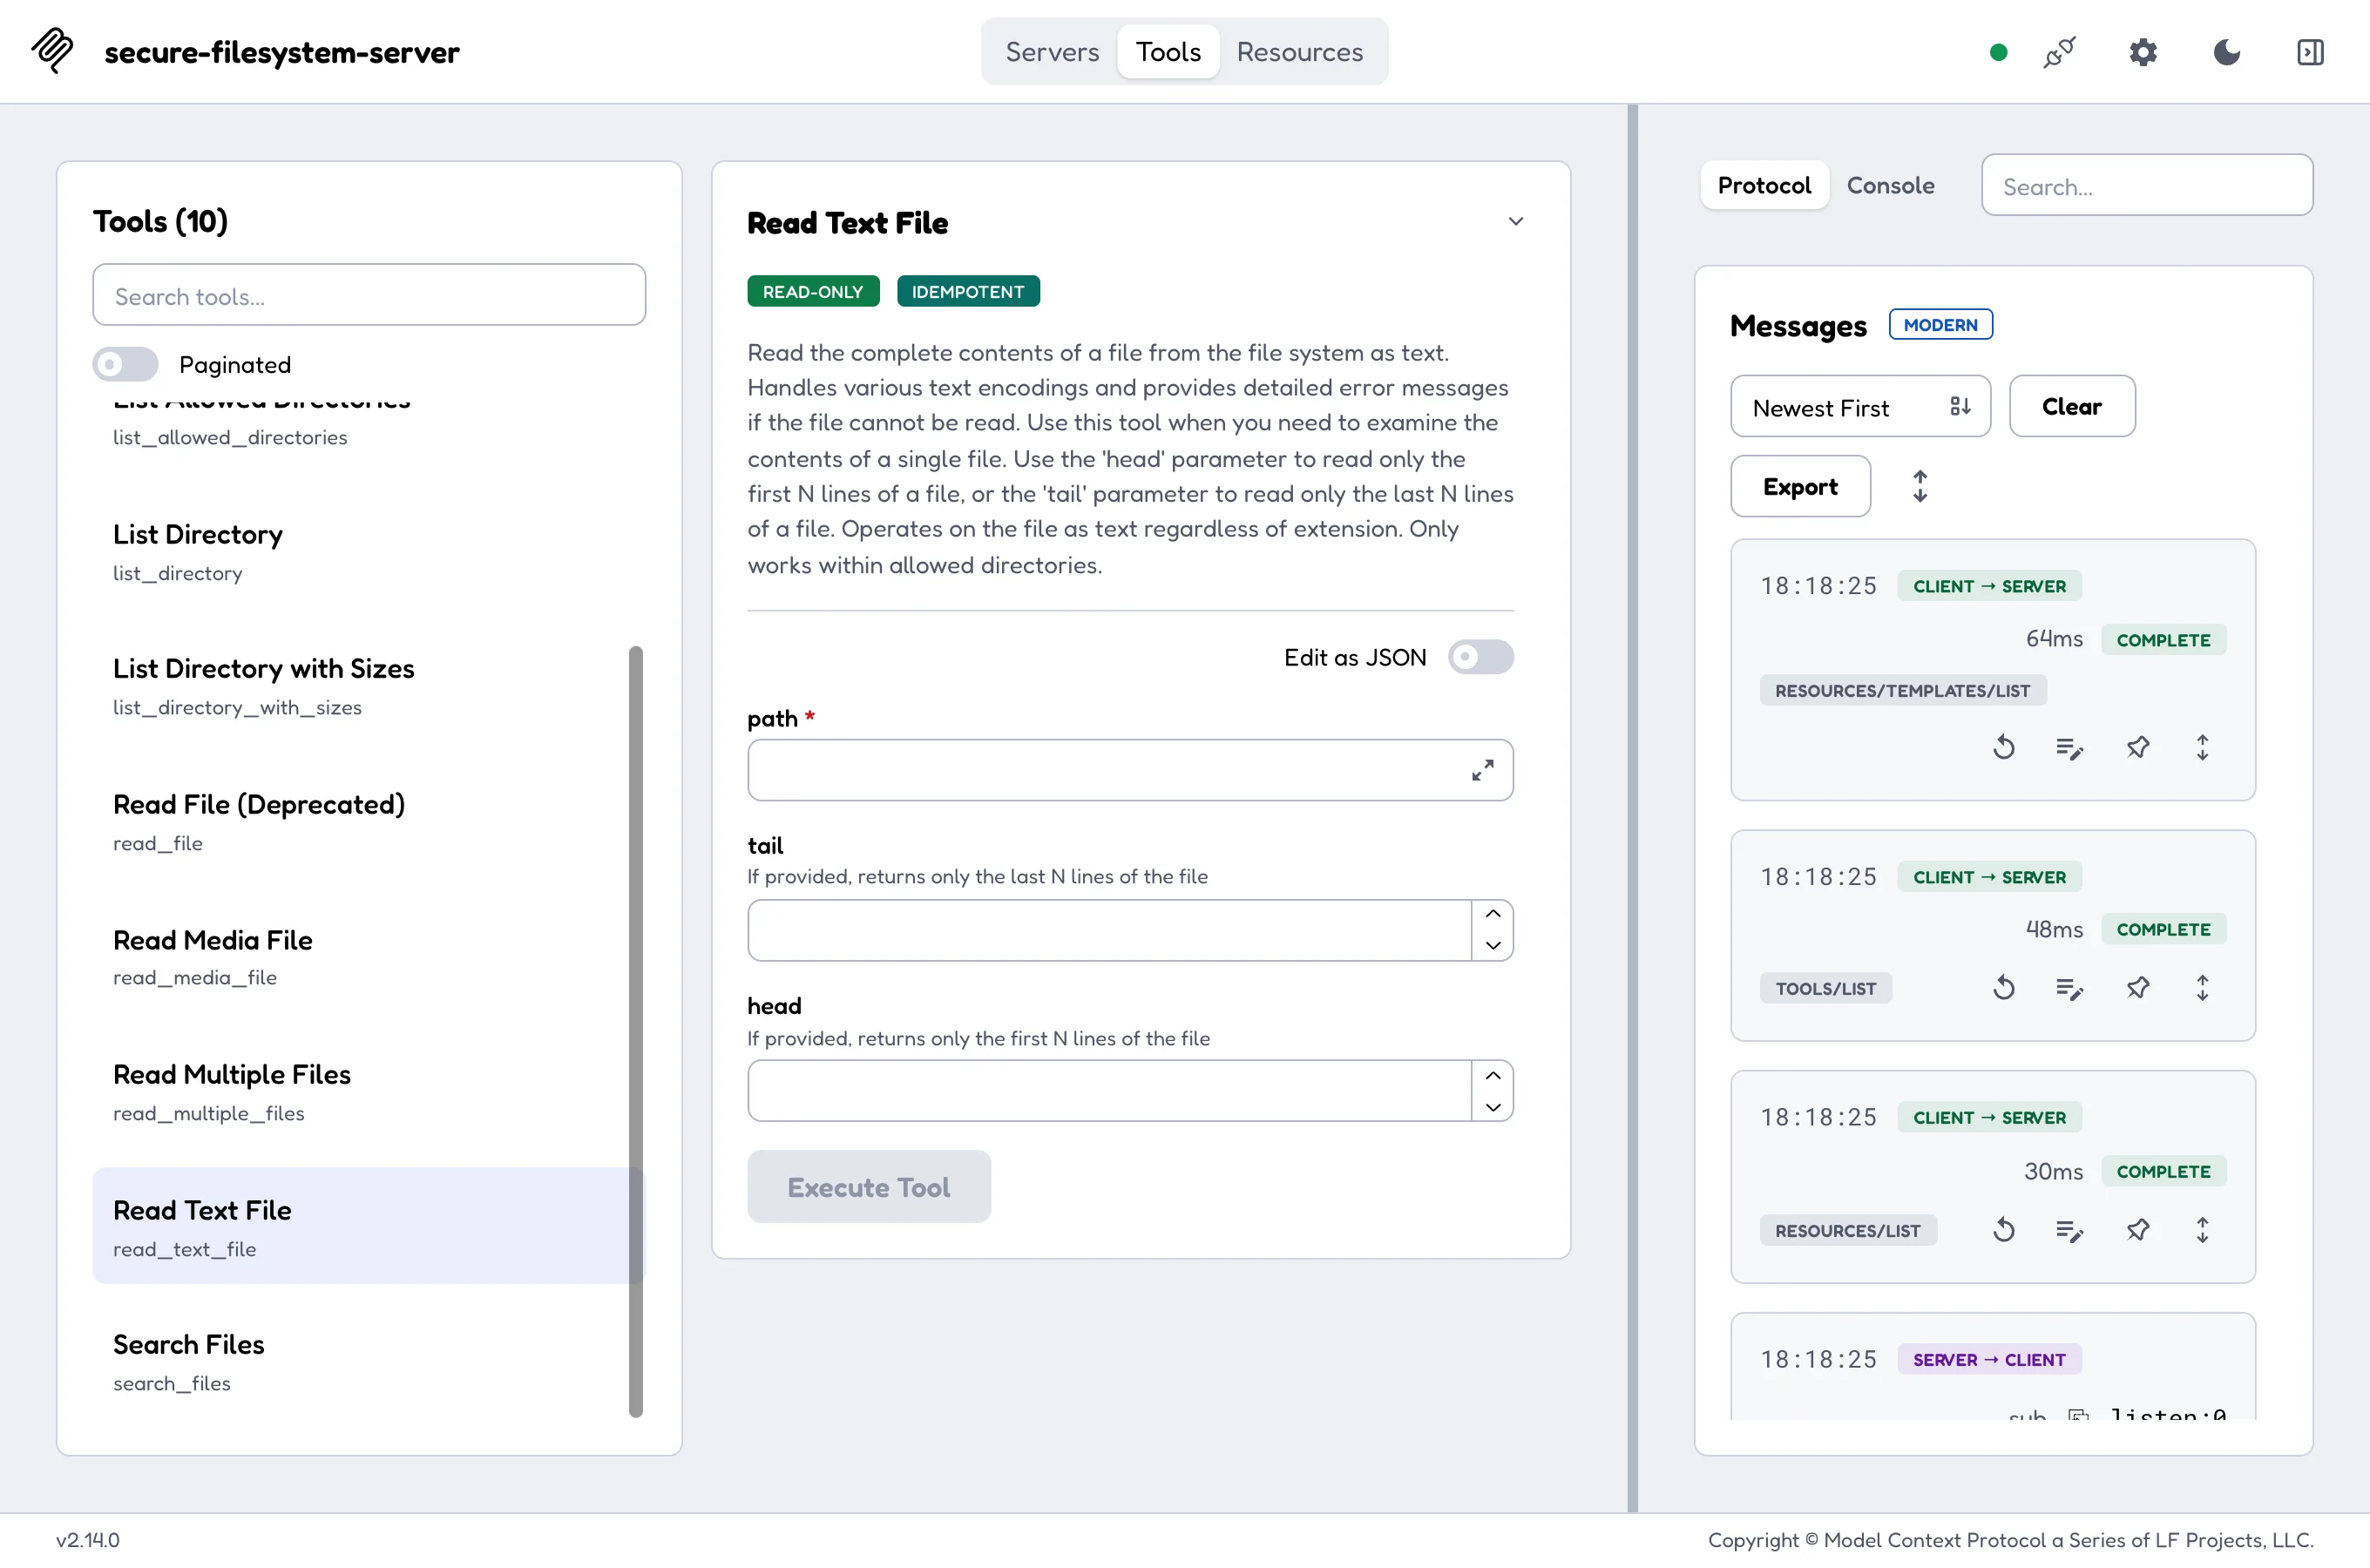
The Tools tab lists the 10 tools of the read-only server. Selecting one shows its description, its annotations as badges, and a form generated from its inputSchema:
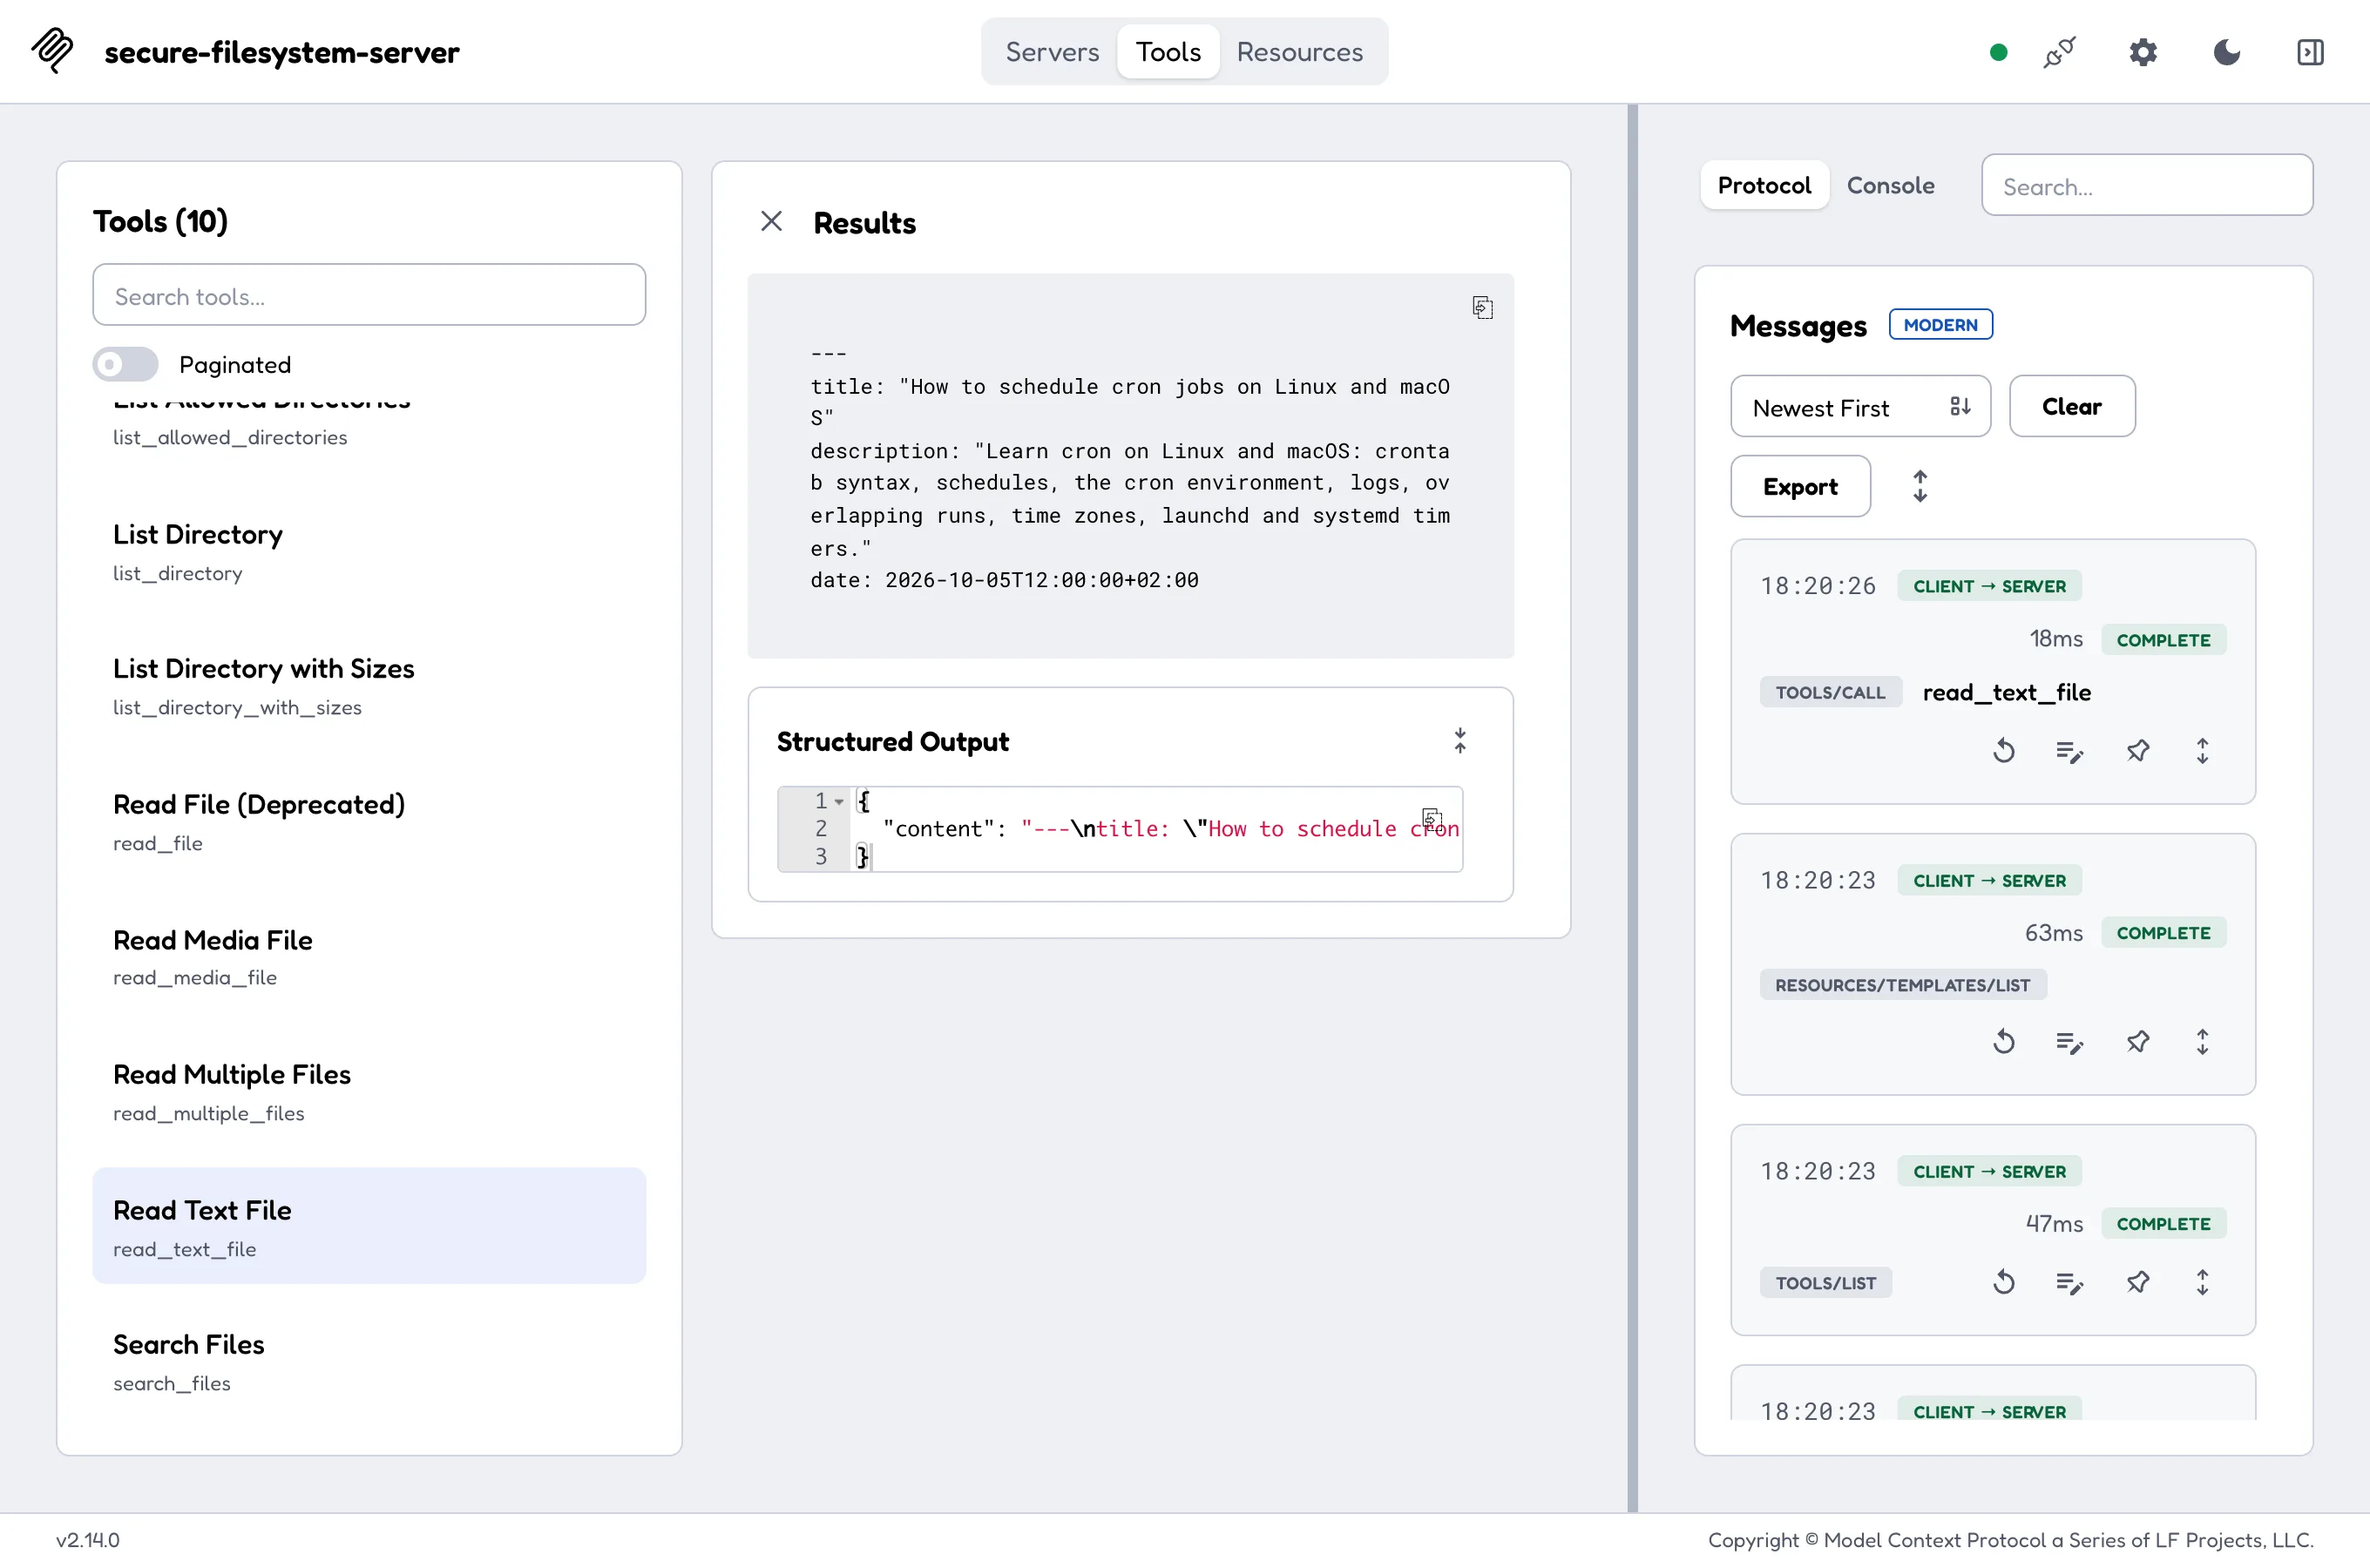
Fill in the path, set head to 4, and click Execute Tool. The result shows both the text content and the structured output, and the log gains a tools/call entry that took 35 ms:
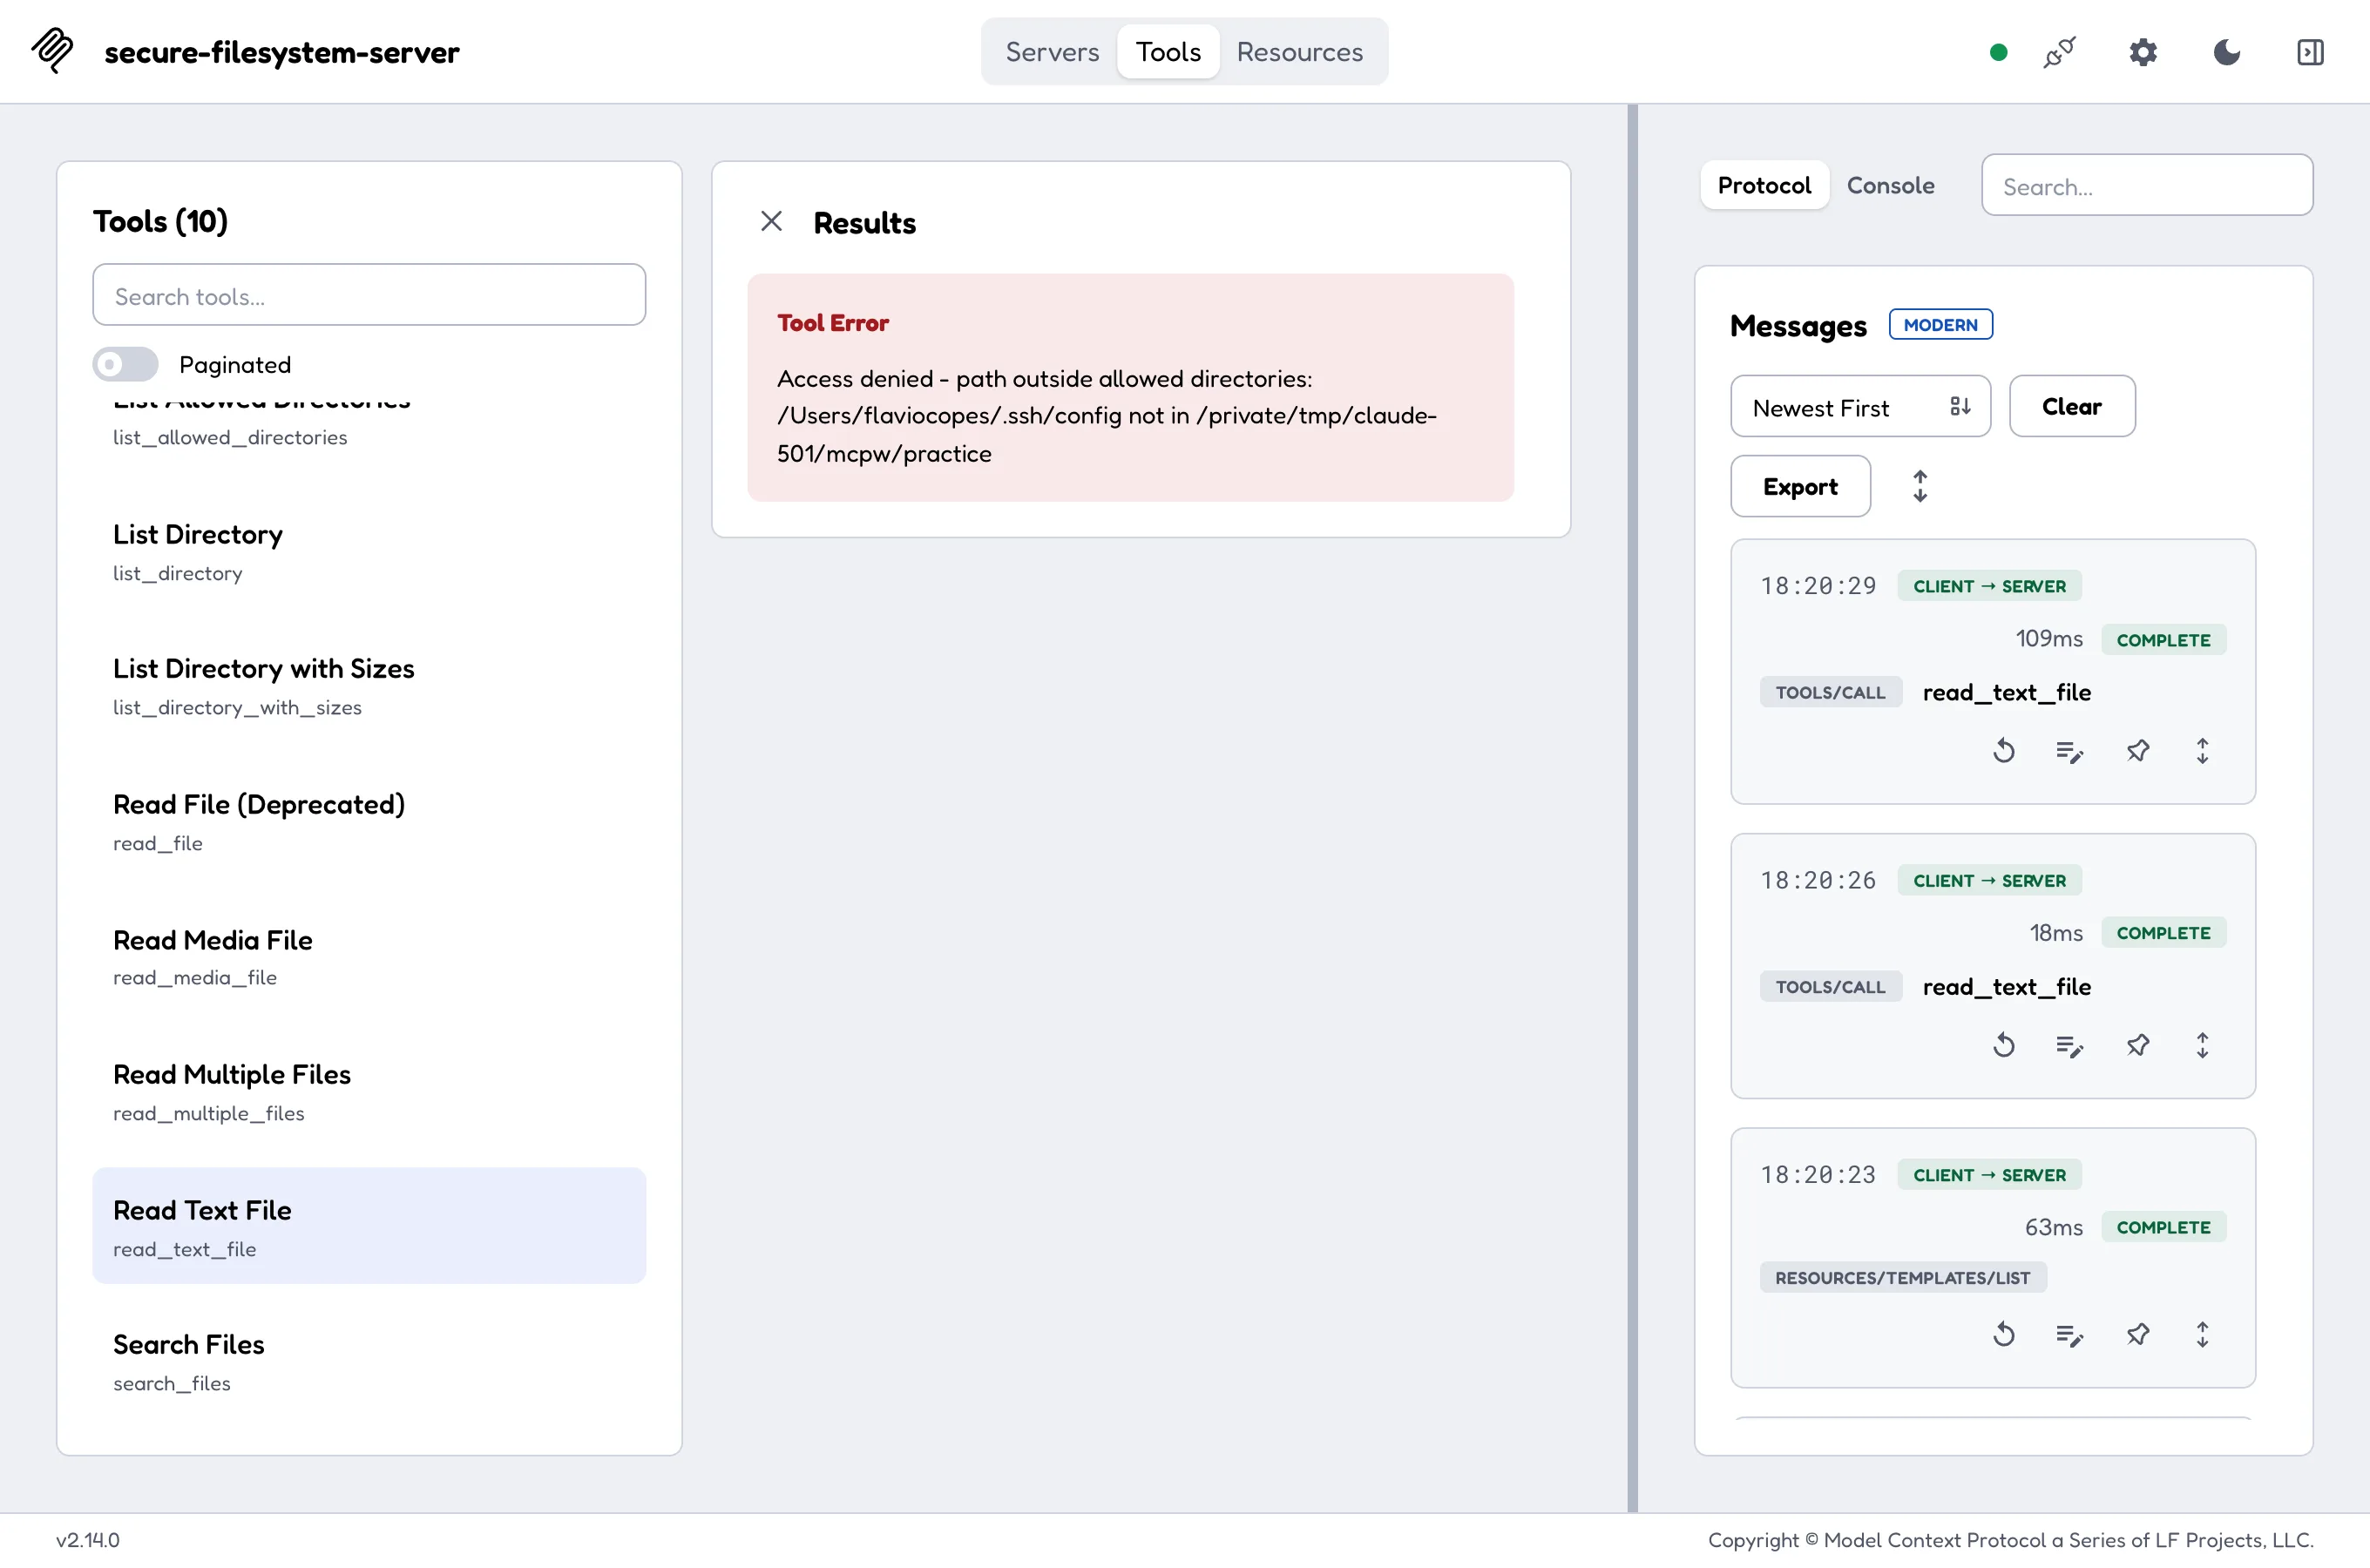
The same tool with /Users/flaviocopes/.ssh/config shows the refusal as a Tool Error, which is exactly the isError: true result from the raw session:
Expanding a message in the log shows the request the Inspector sent, including its _meta with "name": "mcp-inspector" and the capabilities it offers, like elicitation. When a host behaves strangely with a server, I compare what the Inspector sends with what the host sends.
Local and remote servers: stdio and Streamable HTTP
The protocol defines two standard transports. The messages are the same on both.
With stdio, the host starts the server as a child process and they exchange newline-delimited JSON over stdin and stdout. That’s what we just did. Nothing listens on a port, and the server runs with your user account’s permissions.
With Streamable HTTP, the server runs somewhere else. Each message is an HTTP POST to one endpoint, and the response comes back as JSON or as a short Server-Sent Events stream. On HTTP the current version also copies the method and the protocol version into headers like Mcp-Method and MCP-Protocol-Version, so a gateway can route requests without reading the body.
We can talk to a remote server with curl. The Astro docs server is public and needs no login. A 2026-07-28 request first:
curl -s -X POST https://mcp.docs.astro.build/mcp \
  -H 'content-type: application/json' \
  -H 'accept: application/json, text/event-stream' \
  -H 'MCP-Protocol-Version: 2026-07-28' \
  -H 'Mcp-Method: server/discover' \
  -d '{"jsonrpc":"2.0","id":1,"method":"server/discover","params":{"_meta":{"io.modelcontextprotocol/protocolVersion":"2026-07-28","io.modelcontextprotocol/clientCapabilities":{}}}}'
HTTP/2 400
{"jsonrpc":"2.0","error":{"code":-32000,"message":"Bad Request: Unsupported protocol version (supported versions: 2025-06-18, 2025-03-26, 2024-11-05, 2024-10-07)"},"id":null}This server only speaks the older versions. A dual-era client sees the 400, finds no modern error in the body, and falls back to the initialize handshake:
curl -s -X POST https://mcp.docs.astro.build/mcp \
  -H 'content-type: application/json' \
  -H 'accept: application/json, text/event-stream' \
  -d '{"jsonrpc":"2.0","id":1,"method":"initialize","params":{"protocolVersion":"2025-06-18","capabilities":{},"clientInfo":{"name":"probe","version":"1.0.0"}}}'
event: message
data: {"result":{"protocolVersion":"2025-06-18","capabilities":{"logging":{},"tools":{"listChanged":true}},"serverInfo":{"name":"Astro Docs server","version":"1.0.0"}},"jsonrpc":"2.0","id":1}The answer arrived as an SSE event. It didn’t set an Mcp-Session-Id header either, so the next requests need only the MCP-Protocol-Version: 2025-06-18 header. tools/list returns its one tool:
event: message
data: {"result":{"tools":[{"name":"search_astro_docs","title":"Search Astro Docs","description":"Search the official Astro framework docs","inputSchema":{"type":"object","properties":{"query":{"type":"string","description":"Search query"}},"required":["query"],"additionalProperties":false,"$schema":"http://json-schema.org/draft-07/schema#"}}]},"jsonrpc":"2.0","id":2}
And a tools/call with {"query": "getStaticPaths"} returned 15,550 bytes of documentation, starting with the getStaticPaths() reference page.
Here’s how the two compare with these two real servers:
| stdio: filesystem 2.2.0 | Streamable HTTP: Astro docs | |
|---|---|---|
| Where it runs | a child process on my Mac | Astro’s servers, behind Cloudflare |
| Time to first response | 121 to 128 ms installed, 317 to 341 ms with warm npx, 518 ms cold | 284 ms for initialize |
tools/list | 1 to 3 ms after startup, 10,297 bytes for 10 tools | 209 to 289 ms, 1 tool |
tools/call | 1 to 3 ms | 487 to 522 ms for a docs search |
| Protocol versions | 2026-07-28 and 2025-11-25 (dual-era) | 2025-06-18 and older only |
| Response format | one JSON line on stdout | SSE event in the HTTP body |
| Credentials | env variables and your user account | headers or OAuth, here none |
| Logs | stderr, in the host’s MCP log | on the provider’s side, invisible to you |
| Who can use it | the one machine that runs it | anyone with the URL |
The latency numbers are mine, from Italy, on one evening. The shape holds: local servers cost process startup, remote servers cost a network round trip on every call.
The stdio column has a cost the table doesn’t show. A local server can do anything your user account can, so the folder argument and --read-only are the only things keeping it in the practice folder.
MCP vs APIs, function calling and skills
MCP sits next to three other ways of giving an agent abilities, and they get mixed up.
An HTTP API is how software talks to a service. An MCP server often sits in front of one: the Astro docs server wraps a search index, Polar’s server wraps the Polar API.
Function calling, or tool use, is a model feature. You send tool definitions with a request, and the model answers with a tool name and arguments instead of text. Your code runs the function. MCP builds on it: Claude Code turns each MCP tool into a tool definition for the model, and when the model calls it, the client sends tools/call to the server. Tool calling is how Claude Code, Codex, Cursor and Grok Build name that step.
A skill is a folder with a SKILL.md file of instructions, sometimes with scripts. The agent reads the instructions and does the work with the tools it already has, usually a shell. My flavioify skill, which I’m using to write this, is instructions and two Python scripts.
| MCP server | Plain API or CLI | Function calling | Skill | |
|---|---|---|---|---|
| Who runs the code | the server process | the agent, through its shell | your application | the agent, through its shell |
| How the agent finds out what’s possible | tools/list at runtime | reads docs or --help | you list tools in each request | a name and description in the system prompt |
| Context cost, measured in Claude Code | 3,635 tokens for the filesystem server’s 16 tools | nothing until the agent reads something | the same schemas, sent every request | about 160 tokens for flavioify’s listing, the body loads on use |
| Works across hosts | yes, unchanged | yes, if the agent has a shell | no, tied to your app | in hosts that support skills |
| Keeps credentials away from the model | yes, the server holds them | only if the CLI reads them from a keychain or env | yes, your code holds them | no, scripts run as the agent |
| Real example from my setup | Borumi’s 49 tools for video editing | wrangler for Cloudflare | the tool loop inside an app’s own backend | flavioify, mac-test-vm |
The honest takeaway from the MCP servers I actually use is that a good CLI often beats a server. wrangler beats three Cloudflare servers for me. A server earns its place when it gives you something a shell can’t: credentials the agent never sees, a confirmation form before a billable call, or one integration that works in every host.
How much context a server costs
Every tool definition goes into the model’s context window. That costs tokens, and a long tool list makes the model’s choice harder.
Claude Code’s /context command breaks the cost down per tool. With only the filesystem server connected, the 16 tools of the full server cost:
| Tool | Server | Tokens |
|------|--------|--------|
| mcp__practice-files__append_file | practice-files | 235 |
| mcp__practice-files__copy_file | practice-files | 228 |
| mcp__practice-files__create_directory | practice-files | 176 |
| mcp__practice-files__directory_tree | practice-files | 337 |
| mcp__practice-files__edit_file | practice-files | 423 |
| mcp__practice-files__get_file_info | practice-files | 176 |
| mcp__practice-files__list_allowed_directories | practice-files | 144 |
| mcp__practice-files__list_directory | practice-files | 176 |
| mcp__practice-files__list_directory_with_sizes | practice-files | 221 |
| mcp__practice-files__move_file | practice-files | 196 |
| mcp__practice-files__read_file | practice-files | 191 |
| mcp__practice-files__read_media_file | practice-files | 150 |
| mcp__practice-files__read_multiple_files | practice-files | 238 |
| mcp__practice-files__read_text_file | practice-files | 317 |
| mcp__practice-files__search_files | practice-files | 267 |
| mcp__practice-files__write_file | practice-files | 160 |
That’s 3,635 tokens. Now my real setup in this repository:
| Server | Tools | Tokens |
|---|---|---|
| railway | 71 | 37,264 |
| borumi | 49 | 13,394 |
| Polar | 5 | 3,264 |
| claude.ai Claude Docs | 8 | 2,132 |
| Total | 133 | 56,054 |
Railway alone costs more than 37,000 tokens, and its update-service tool is about 3,300 on its own. Polar takes a smarter approach: five tools, among them search and execute, that look up and run API operations on demand.
Claude Code doesn’t put all of that in every request. The summary line says MCP tools (deferred) | 55.4k, and only 631 tokens are loaded up front. The model sees the tool names, and when it needs one it loads the schema with a tool search. You can see it happen in a session log:
TOOL_USE ToolSearch {"query":"select:mcp__practice-files__read_text_file","max_results":1}
TOOL_USE mcp__practice-files__read_text_file {"path":"/tmp/mcp-practice/cron.md","head":5}
Not every host does this. A host that loads every schema would start each conversation 56,000 tokens in. Turning off servers you don’t use for a project is still the cheapest fix, which is why Astro docs and Context7 are disabled in this repository.
Choose a server you trust
An MCP server is a program you install and run with your account, or a service you hand a login to, so it gets the same review as any other software with that access.
Before connecting one, I want to know what it can read and change, where it sends data, and which credentials it gets.
For the filesystem server, the answers come from its README, its tools/list and the runs above:
- Package:
@modelcontextprotocol/server-filesystem2.2.0, published from github.com/modelcontextprotocol/servers - Command:
npx -y @modelcontextprotocol/[email protected] --read-only <folder> - Reads: files inside the folder I pass, after resolving symlinks
- Changes: nothing with
--read-only. Without it,write_file,edit_file,move_file,append_file,copy_fileandcreate_directory, andwrite_fileandedit_fileare marked destructive - Network: none of its tools talk to the network (
openWorldHint: falseon all 16) - Credentials: none
- Advertised: 10 tools with
--read-only, 16 without, plus resources
The interesting finding is the second line of “Changes”. The server everyone calls “the filesystem server” isn’t read-only by default. If you followed a tutorial that said “point it at your project”, the agent can rewrite your project.
Watch the install command, too. npx -y package downloads and runs whatever version is newest, every time the host starts. Pin a version you looked at, like @2.2.0 above. My Cursor config has an entry that does the opposite:
"Playwright": {
  "args": [],
  "command": "npx @playwright/mcp@latest",
  "env": {}
}
@latest means a new release runs on my Mac the next time Cursor starts, without anyone reviewing it.
Credentials deserve the same look. Another entry in that file passes a Polar sandbox token as a command-line argument to mcp-remote:
"Polar Sandbox": {
  "args": [
    "-y",
    "mcp-remote",
    "https://mcp.polar.sh/mcp/polar-sandbox",
    "--header",
    "Authorization:Bearer <redacted>"
  ],
  "command": "npx"
}
The token sits in plain text in the file, and any process on the machine can read command-line arguments with ps. It’s a sandbox token that can’t move money, but the pattern is worth fixing: put tokens in env, or let the server read them from the macOS Keychain the way my cloudflare-domains server does.
Remote servers need different questions. You can’t read the code, so you look at who runs it, what the OAuth screen asks for, and whether the service has a read-only mode. Paddle’s local server, for example, takes PADDLE_MCP_TOOLS=non-destructive, and that’s what my config uses. MCP server design covers what a server provider should do on their side.
Trust applies to the version you reviewed. When you upgrade, run tools/list again and compare.
Read a server configuration
A server configuration tells the host which process to start, or which URL to call. Read it as a process launch, not as passive data.
Claude Code keeps servers in three scopes. User servers are available in every project, local servers in one project but only for you, and project servers live in a .mcp.json file committed to the repository. User and local servers live in ~/.claude.json.
These are my user servers:
{
  "railway": {
    "args": [
      "mcp"
    ],
    "command": "railway"
  },
  "borumi": {
    "type": "stdio",
    "command": "/Applications/Borumi.app/Contents/MacOS/borumi",
    "args": [
      "mcp"
    ],
    "env": {}
  }
}
And the local servers for this site’s repository:
{
  "mcpServers": {
    "Astro docs": {
      "type": "http",
      "url": "https://mcp.docs.astro.build/mcp"
    },
    "Polar": {
      "type": "http",
      "url": "https://mcp.polar.sh/mcp/polar-mcp"
    }
  },
  "disabledMcpServers": [
    "plugin:github:github",
    "Astro docs",
    "claude-in-chrome",
    "plugin:context7:context7",
    "plugin:playwright:playwright",
    "plugin:supabase:supabase"
  ]
}
Translate each entry into one sentence. “Claude Code runs /Applications/Borumi.app/Contents/MacOS/borumi mcp as me, with no extra environment.” “Claude Code sends my Polar login to mcp.polar.sh.” If you can’t write the sentence, you don’t know what you’re installing.
A few things to check in any config:
commandandargsare separate values. Changing an argument, like the folder for the filesystem server, changes what the server can reach.- The host may not have your shell’s
PATH.railwayworks here because Claude Code runs from my terminal. A desktop app launched from the Dock might not find it, and an absolute path like Borumi’s always works. - No secret values. Use
envwith a variable the host expands, or a keychain. - An
httpentry with noheaderseither needs no auth, like Astro docs, or logs in through the host, like Polar. Claude Code keeps that login itself, so it never appears in the file, andclaude mcp listsays “Needs authentication” when it’s missing, as it does for Notion above.
Cursor and Codex use their own files, ~/.cursor/mcp.json and ~/.codex/config.toml, with nearly the same fields. The MCP config generator writes the JSON for several hosts and only asks for variable names, never for the secret values.
Add and remove a server with claude mcp add
To try a server without touching your real setup, add it in a throwaway folder with the project scope. I made an empty folder called proj:
claude mcp add --scope project practice-files -- npx -y @modelcontextprotocol/[email protected] /tmp/mcp-practiceAdded stdio MCP server practice-files with command: npx -y @modelcontextprotocol/[email protected] /tmp/mcp-practice to project config
File modified: /private/tmp/mcp-demo/proj/.mcp.jsonEverything after -- is the command. The new .mcp.json:
{
  "mcpServers": {
    "practice-files": {
      "type": "stdio",
      "command": "npx",
      "args": [
        "-y",
        "@modelcontextprotocol/[email protected]",
        "/tmp/mcp-practice"
      ],
      "env": {}
    }
  }
}
claude mcp get shows something important:
claude mcp get practice-filespractice-files:
Scope: Project config (shared via .mcp.json)
Status: ⏸ Pending approval (run `claude` to approve)
Type: stdio
Command: npx
Args: -y @modelcontextprotocol/[email protected] /tmp/mcp-practice
Environment:
To remove this server, run: claude mcp remove practice-files -s projectA project server is pending until you approve it. That’s because .mcp.json comes with the repository. If you clone someone’s project, their .mcp.json would otherwise start processes on your Mac the moment you open Claude Code there.
Removing it puts the file back:
claude mcp remove practice-files -s projectRemoved MCP server practice-files from project config
File modified: /private/tmp/mcp-demo/proj/.mcp.json{
"mcpServers": {}
}Make a controlled first call
Now the real test: give the server to an agent and ask for something whose answer we already know.
I connected the server with --mcp-config .mcp.json --strict-mcp-config, so only this server was available, and allowed only read_text_file:
claude -p "Using the practice-files MCP server, tell me the title in the frontmatter of cron.md in /tmp/mcp-practice. Read as little of the file as possible." --mcp-config .mcp.json --strict-mcp-config --allowedTools "mcp__practice-files__read_text_file" --output-format stream-json --verboseThe model picked the right tool and the right arguments. The server refused anyway:
TOOL_USE mcp__practice-files__read_text_file {"path":"/tmp/mcp-practice/cron.md","head":5}
RESULT "Access denied - path outside allowed directories: /tmp/mcp-practice/cron.md not in /private/tmp/mcp-demo/proj, /tmp/mcp-demo/proj" ERROR
The allowed directory was proj, the folder Claude Code ran in, not the practice folder in the config.
This is Roots, a feature of the older protocol. A 2025-era client can tell the server which folders the user is working in, and the filesystem server replaces its command-line folders with them. Roots only exist in the initialize handshake, so Claude Code 2.1.247 connected the old way and sent its working directory. The 2026-07-28 version deprecates Roots, and the server’s README documents the replacement behavior.
Then the agent did something else worth knowing. It ran ls with Bash, read the config, and read cron.md with its built-in Read tool:
TOOL_USE Bash {"command":"ls -la /tmp/mcp-demo/proj/ /tmp/mcp-practice/ 2>&1 | head -40","description":"List proj and practice dirs"}
TOOL_USE Read {"file_path":"/tmp/mcp-practice/cron.md","limit":5}
TEXT **Title: "How to schedule cron jobs on Linux and macOS"**
An MCP server limits what the server can do. It doesn’t limit the agent. Claude Code has its own file and shell tools, governed by its own permissions, and the model will use them when the MCP tool fails.
The fix for the server is in its README: --confine-roots lets a client narrow the folders but never replace them, and --read-only drops the write tools. I removed the server and added it again with both flags:
claude mcp add --scope project practice-files -- npx -y @modelcontextprotocol/[email protected] --read-only --confine-roots /tmp/mcp-practiceThis time I also blocked the built-in file tools with --disallowedTools "Bash,Read,Grep,Glob". The session listed 10 tools from the server, and the call worked on the first try in 8 seconds:
TOOL_USE mcp__practice-files__read_text_file {"path":"/tmp/mcp-practice/cron.md","head":5}
RESULT "{\"content\":\"---\\ntitle: \\\"How to schedule cron jobs on Linux and macOS\\\"\\ndescription: \\\"Learn cron on Linux and macOS: crontab syntax, schedules, the cron environment, logs, overlapping runs, time zones, launchd and systemd timers.\\\"\\ndate: 2026-10-05T12:00:00+02:00\\ntag: cli\"}"
TEXT **"How to schedule cron jobs on Linux and macOS"** — read via the practice-files MCP server with `head: 5`, so only the first 5 lines of the file.
Then the negative test, asking it to append a line to tmux.md through the server:
TOOL_USE ToolSearch {"query":"+practice-files write edit append create file","max_results":10}
TEXT I can't — the practice-files MCP server exposes only read-only tools (read, list, search, file info), with no write, edit, or append capability.
tmux.md was unchanged afterwards, byte for byte.
That’s the test I’d run on any new server, in this order:
- One call with a result you already know.
- A call with a wrong argument, to see the validation error.
- A call for something that doesn’t exist, to tell “not found” from a crash.
- A call across the boundary you care about: another folder, another account, a write.
- A check that nothing changed on disk or in the account.
A positive test without the negative ones tells you the server works, not that it’s contained. The first run above passed step 1 by going around the server entirely.
Troubleshoot a connection
When a server doesn’t show up or its tools vanish, find the layer that failed instead of reinstalling things.
- Can the host parse its config? A JSON syntax error can drop every server in the file.
claude mcp listandclaude mcp get <name>show what Claude Code read. - Can it start the command? Run the exact
commandandargsin a terminal. A wrong package name or path fails right away. - Does the process stay up? A server without a folder argument, or with a missing env variable, often exits during startup. Its last words are on stderr. Start Claude Code with
claude --debugto see them. - Do the protocol versions match? A modern-only client and a legacy-only server can’t talk. The Astro docs server answers a 2026-07-28 request with
400and lists the versions it supports. - Does discovery return what you expect? If the tool list is wrong, you may be running a different version than you reviewed.
- Does one minimal call work? Use the Inspector to rule out the host and the model.
For stdio servers there’s one classic bug: stdout is the protocol. A server that prints a startup banner or a console.log on stdout corrupts the stream, and the host drops the connection. The filesystem server prints everything on stderr for this reason.
The other classic is PATH. A command that works in your terminal may depend on a Node version manager or an alias that a desktop host never loads. Try the absolute path, like /opt/homebrew/bin/node, to confirm it, then decide how to keep it maintainable.
And whatever fails, don’t fix a path error by giving the server a bigger folder. Fix the path.
When MCP is the right tool
MCP is worth it when you want one integration to work in several AI applications, or when a provider wants to ship one server instead of a connector per client.
For a small app with one model and a couple of internal functions, plain function calling is simpler. For a service that already has a good CLI, the agent can use the CLI. When the agent is already on a website and needs that page’s actions, look at WebMCP, which exposes tools inside the browser tab.
In my own setup, the servers that earn their place are docs servers for fast-moving frameworks, and the one I wrote to buy domains with a confirmation form, which I describe in the MCP servers I actually use. For a hosted server you log into, researching keywords through OpenSEO MCP walks through a bounded, paid call from start to finish.
A gateway like Executor goes further: you register a service once, give each account its own named connection, and every agent talks to one catalog.
When you’re ready to expose your own tools, follow how to build an MCP server. To package one for ChatGPT and Codex, see how to create and publish a ChatGPT plugin.
The MCP specification is the reference for everything in this post, and the Inspector repository has the rest of its options.
Want me to talk about your product? You can sponsor this site.
Related posts about ai: