Build a private AI feature with a local model, Ollama and Node.js
By Flavio
Tagged: AI
Build a Node.js feature on a local Ollama model: what's in the model file, schema output, validation, timeouts, a fallback, evals, tests and real speed.
This blog has more than 2,200 posts. Every one has a description for search results and social cards, and a tag that puts it on a topic page. I write both by hand, usually last, usually in a hurry.
A model could suggest them. But the posts I need help with are drafts, and drafts are the text I’d rather not send to an API. So I built the feature on a model that runs on my Mac with Ollama, and I made it reliable enough to sit in a real script: it validates what the model says, gives up on time, and still produces a usable answer when Ollama isn’t running.
This post walks through that build in Node.js, with the real output of every step:
- what’s inside the model file you download, and what quantization does to it
- calling Ollama’s local API, streaming, and measuring tokens per second
- structured JSON output with a schema, and why the schema isn’t enough
- validation, timeouts, cancellation and a deterministic fallback
- an evaluation set made of 24 real posts, and tests with
node --test - pinning the model, swapping the provider, and what it costs to run
Everything ran on an M4 Pro Mac with 48 GB of memory, Ollama 0.40.14 and Node.js 22.
If you haven’t installed Ollama yet, start with how to run an LLM locally and run a local LLM with Ollama. This post picks up after the first curl.
What’s inside a model file
When you run ollama pull gemma3:1b, Ollama downloads a few files and stores them by their SHA-256 hash in ~/.ollama/models/blobs. The manifest lists them with their sizes:
application/vnd.ollama.image.model     815310432 bytes
application/vnd.ollama.image.template        358 bytes
application/vnd.ollama.image.license        8432 bytes
application/vnd.ollama.image.params           77 bytes
The 815 MB one is the model. It’s a GGUF file, the single-file format used by llama.cpp, which Ollama runs under the hood. The first bytes say so:
xxd -l 32 ~/.ollama/models/blobs/sha256-7cd4618c1faf8b7233c6c906dac1694b6a47684b37b8895d470ac688520b9c0100000000: 4747 5546 0300 0000 5401 0000 0000 0000 GGUF....T.......
00000010: 1f00 0000 0000 0000 1b00 0000 0000 0000 ................GGUF, version 3, 0x154 (340) tensors, 0x1f (31) metadata entries. After that header comes the metadata, then a table describing every tensor, then the weights themselves.
I wrote a 70-line reader for it (gguf.js, it’s in the complete code at the end) to see what the file actually holds. Here’s the metadata of gemma3:1b, with some keys left out and long values cut:
GGUF version 3
gemma3.attention.head_count = 4
gemma3.attention.head_count_kv = 1
gemma3.attention.key_length = 256
gemma3.attention.sliding_window = 512
gemma3.block_count = 26
gemma3.context_length = 32768
gemma3.embedding_length = 1152
gemma3.feed_forward_length = 6912
general.architecture = gemma3
tokenizer.chat_template = {{ bos_token }} {%- if messages[0]['role...
tokenizer.ggml.bos_token_id = 2
tokenizer.ggml.eos_token_id = 1
tokenizer.ggml.model = llama
tokenizer.ggml.tokens = [262144 items]
general.file_type = 15
So one file carries everything a runtime needs: the architecture (26 transformer blocks, 1,152 numbers per token, 4 attention heads), the tokenizer with its 262,144 tokens, the chat template that turns system/user/assistant messages into the exact token sequence the model was trained on, and the weights. A wrong chat template makes good weights produce garbage, which is why GGUF ships it inside. What open weights means covers the licensing side of these downloads.
The other format you’ll see on Hugging Face is Safetensors: plain tensors, often split across model-00001-of-00004.safetensors files, with the config and tokenizer in separate JSON files next to them. Transformers and MLX load Safetensors. llama.cpp, and Ollama’s llama.cpp runner that served every model in this post, load GGUF. A GGUF file is a conversion of the original Safetensors release, made by whoever published it.
What Q4_K_M means
ollama show gemma3:1b says quantization Q4_K_M. The original weights are 16-bit numbers. Quantization stores them with fewer bits, in blocks that share a scale, so the file gets smaller and the model loads into less memory. You lose some precision.
The reader also counts the tensors by storage type. Here’s what that looks like for three versions of Gemma 3 1B from the Ollama library, plus the 4B model:
gemma3:1b (Q4_K_M)
F32: 157 tensors, 0M weights
Q8_0: 14 tensors, 306M weights
Q5_0: 117 tensors, 456M weights
Q4_K: 39 tensors, 134M weights
Q6_K: 13 tensors, 104M weights

gemma3:1b-it-q8_0
F32: 157 tensors, 0M weights
Q8_0: 183 tensors, 1000M weights

gemma3:1b-it-fp16
F16: 183 tensors, 1000M weights
F32: 157 tensors, 0M weights

gemma3:4b (Q4_K_M)
F16: 165 tensors, 419M weights
F32: 479 tensors, 1M weights
Q6_K: 34 tensors, 1159M weights
Q4_K: 205 tensors, 2721M weights
Q4_K_M is a recipe, not a bit width. In the 1B file only 134 million of the 1 billion weights are 4-bit. The token embedding table alone is 262,144 tokens × 1,152 numbers = 302 million weights, and it’s kept in 8-bit. Most of the rest landed in Q5_0, because K-quants work on blocks of 256 values and Gemma 1B’s rows of 1,152 values don’t divide by 256, so llama.cpp falls back to a format that fits. The tiny F32 tensors are normalization weights.
In the 4B file you can also spot something that isn’t text at all: 419 million F16 weights are the vision encoder, since gemma3:4b accepts images.
Divide the file size by the parameter count and you get the real bits per weight:
| Model file | Size on disk | Parameters | Bits per weight |
|---|---|---|---|
gemma3:1b (Q4_K_M) |
815 MB | 1.0B | 6.5 |
gemma3:1b-it-q8_0 |
1,069 MB | 1.0B | 8.6 |
gemma3:1b-it-fp16 |
2,007 MB | 1.0B | 16.1 |
gemma3:4b (Q4_K_M) |
3,339 MB | 4.3B | 6.2 |
So for this small model, going from Q8_0 to Q4_K_M saves 24%, not the 50% the names suggest. The usual estimate, parameters × bits ÷ 8, assumes every weight gets the same treatment. How much VRAM you need has that formula and the hardware tables.
What do you lose? That depends on the task, so you have to measure it on yours. Here’s what I measured on this one, with the evaluation set from later in this post:
The three quantizations of the 1B model pass the same 2 cases, while the 4B model at Q4_K_M passes 14. For this task, parameter count mattered and precision didn’t.
Memory: the weights plus the context
A loaded model takes more memory than its file. The runtime also reserves the KV cache: for every token in the context window, each layer stores the attention keys and values so it doesn’t recompute the whole prompt for every new token. It grows with the context length you configure, not with the prompt you send.
I loaded each model with a 4,096 and a 32,768 token window (num_ctx), and wrote down what ollama ps reports and what the process actually holds:
| Model | ollama ps, 4,096 |
ollama ps, 32,768 |
Process memory, 4,096 | Process memory, 32,768 |
|---|---|---|---|---|
gemma3:1b Q4_K_M |
0.88 GB | 1.01 GB | 0.94 GiB | 0.99 GiB |
gemma3:1b-it-q8_0 |
1.14 GB | 1.27 GB | 1.12 GiB | 1.22 GiB |
gemma3:1b-it-fp16 |
2.08 GB | 2.21 GB | 1.86 GiB | 2.18 GiB |
gemma3:4b Q4_K_M |
2.33 GB | 2.57 GB | 4.22 GiB | 5.03 GiB |
The process memory columns are the resident size of the llama-server process Ollama starts for each model (ps -o rss). For the 4B model ollama ps reports much less than the process holds, and for gemma4:26b it said 1.4 to 1.6 GB while the process held 17.7 GiB. When the two disagree, trust the process.
Here’s /api/ps, the endpoint behind ollama ps, opened in Chrome while both were loaded. It lists the 25.8B model at 1,574,405,405 bytes, less than a tenth of its 18 GB file:
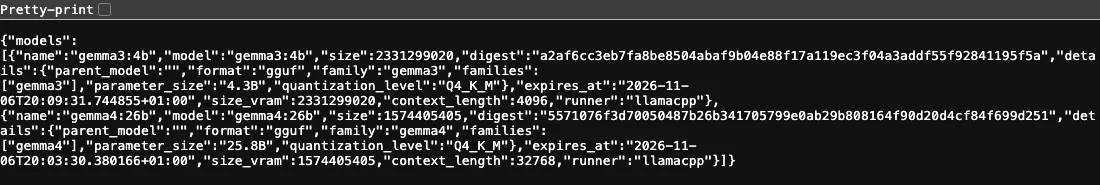
Going from 4,096 to 32,768 tokens costs between 0.05 and 0.3 GiB on the 1B models and 0.8 GiB on the 4B one.
Gemma 3 grows less than you’d expect because most of its layers use a 512-token sliding window (it’s in the metadata above, sliding_window = 512) and only one key/value head (head_count_kv = 1). Other architectures grow much faster with the same setting. Measure yours on your own machine instead of trusting the advertised context length.
A post body plus instructions is about 1,500 to 2,000 tokens here, so I set num_ctx: 4096 and cut every post at 6,000 characters. A longer window would cost memory and buy nothing.
The feature, and its contract
Before calling any model, I wrote down what the feature takes and returns.
Input: one post file from src/posts/, like docker-compose.md. We read the title and the body.
Output:
{
  "description": "Learn how to use Docker Compose to define and manage multi-container applications, simplifying deployment and development workflows.",
  "tag": "docker"
}
The rules for a good answer, which become code later:
tagis one of 19 tags this blog usesdescriptionis a full sentence between 50 and 160 characters- no em dashes, and it doesn’t start with “This post” or “In this”
- every number in the description appears in the post
And what happens when things go wrong. If Ollama isn’t running, the model isn’t installed, the request takes longer than 20 seconds, or the answer breaks a rule, the script still prints a suggestion built from the post itself, with no AI. A bug in my own code should still crash.
The frontmatter I write stays the source of truth. The script only suggests.
The project is a folder with no dependencies:
post-meta/
  config.js        model, URL, timeout, context size
  errors.js        ProviderError with a kind
  posts.js         read a post's frontmatter and body
  prompt.js        tags, JSON schema, messages
  validate.js      the rules above
  fallback.js      the answer without a model
  ollama.js        the Ollama provider
  openai.js        any OpenAI-compatible server
  meta.js          retry, validate, fall back
  check-model.js   is the pinned model installed?
  cli.js           node cli.js <post files>
  stream.js        streaming and timing
  gguf.js          the model file reader
  eval/            cases.json and run.js
  test/            node --test
Call Ollama from Node.js
Ollama listens on http://127.0.0.1:11434. Node has fetch() built in, so one request is enough to see what comes back:
const response = await fetch('http://127.0.0.1:11434/api/chat', {
  method: 'POST',
  body: JSON.stringify({
    model: 'gemma3:4b',
    messages: [{ role: 'user', content: 'Suggest a tag for a post about Docker Compose.' }],
    stream: false,
  }),
})

console.log(await response.json())
{
model: 'gemma3:4b',
created_at: '2026-11-06T18:52:09.295465Z',
message: {
role: 'assistant',
content: 'Okay, here are a bunch of tag suggestions for a post about Docker Compose, categorized by relevance and popularity:\n' +
'\n' +
'**Highly Relevant & Popular:**\n' +
'\n' +
'* #dockercompose\n' +
'* #docker\n' +
'* #devops\n' +
...
'* **What is the main focus of your post?** (e.g., a tutorial, a best practices guide, a specific use case?)'
},
done: true,
done_reason: 'stop',
total_duration: 9942617750,
load_duration: 1365494292,
prompt_eval_count: 20,
prompt_eval_cached_count: 0,
prompt_eval_duration: 105645000,
eval_count: 342,
eval_duration: 8468431000
}I cut about 30 lines of hashtags and tips from the middle.
The text is in message.content. Everything else is measurement: durations are in nanoseconds, prompt_eval_count is how many tokens the model read, and eval_count is how many it wrote. Tokens per second is eval_count / (eval_duration / 1e9).
That one call also shows the problem: the model answers in free Markdown, the way it would in a chat window. A script needs a known shape.
Ask for JSON with a schema
Ollama takes a JSON Schema in the format field and constrains generation to it, so the model can only produce tokens that keep the output valid against the schema. Here’s the schema for our two fields, with the tag as an enum:
export const schema = {
  type: 'object',
  properties: {
    description: { type: 'string' },
    tag: { type: 'string', enum: Object.keys(TAGS) },
  },
  required: ['description', 'tag'],
  additionalProperties: false,
}
The prompt says the same thing in words. The system message lists the tags with a short explanation each, and gives two real descriptions from this blog as examples:
const SYSTEM = `You write metadata for a post on flaviocopes.com, a programming blog.

Return JSON with:
- description: one short sentence, at most 18 words, saying what the reader learns or does. Use only facts from the post. Start with a verb like "Learn", "Build" or "Use", or with the subject. End with a period.
- tag: the one topic that fits best:
${Object.entries(TAGS).map(([tag, topic]) => `  ${tag}: ${topic}`).join('\n')}

Examples:
{"description": "Learn how the React Context API lets you share state across your app without prop drilling, using createContext and useContext.", "tag": "react"}
{"description": "Learn tmux from scratch: create persistent sessions, use windows and panes, and work safely over SSH.", "tag": "cli"}`
I set temperature: 0 and a fixed seed so the same post gives the same answer, and num_predict: 150 so a model that rambles stops after 150 tokens instead of running until the timeout.
The schema guarantees the shape, not the content
The obvious next step is to put the length limit in the schema too, with maxLength: 160. I tried it on the Docker Compose post:
{
  "description": "Learn how to use Docker Compose to define and manage multi-container applications, including a Node.js app and a PostgreSQL database, streamlining deployment,  ","tag": "docker"
}
Exactly 160 characters, ending in deployment, . The constraint doesn’t make the model write a shorter sentence. It cuts it off when the budget runs out, because the model doesn’t know the limit is coming. The JSON is valid and the description is broken.
So the schema stays loose, and the rules live in code.
Validate everything the model returns
validate() returns a list of problems. An empty list means the answer is usable:
export function validate(result, post) {
  const errors = []

  if (typeof result?.description !== 'string') errors.push('description missing')
  if (!Object.hasOwn(TAGS, result?.tag ?? '')) errors.push(`tag not allowed: ${result?.tag}`)
  if (errors.length) return errors

  const { description } = result
  if (description.length < 50) errors.push(`description too short: ${description.length}`)
  if (description.length > 160) errors.push(`description too long: ${description.length}`)
  if (description.includes('\u2014')) errors.push('description has an em dash')
  if (/^(this post|in this)/i.test(description)) errors.push('description starts with filler')
  if (!/[.!?]$/.test(description)) errors.push('description is not a full sentence')

  for (const number of description.match(/\d+(\.\d+)?/g) ?? []) {
    if (!post.title.includes(number) && !post.body.includes(number)) {
      errors.push(`number not in post: ${number}`)
    }
  }

  return errors
}
The last check is a cheap truth test. If the model writes “Postgres 15” and the post only mentions Postgres 16, the number isn’t in the post and the answer is rejected. It can’t catch every invented fact, but it catches invented numbers, which are the ones that do damage in a description.
These checks rejected a lot. My first prompt asked for “50 to 160 characters”, and on the 24 evaluation posts gemma3:4b wrote descriptions of 186 to 462 characters. Valid JSON every time, and 0 out of 24 usable. Small models can’t count characters. Asking for “at most 18 words” works better, because words are closer to what the model produces.
Stream and measure
For a script, the non-streaming call is simpler. But streaming is how you measure the two numbers that describe a local model’s speed: time to first token, which is load plus reading the prompt, and tokens per second while generating.
Ollama streams newline-delimited JSON: each line is a complete object, and a network chunk can end in the middle of one, so we keep the unfinished line in a buffer:
const decoder = new TextDecoder()
let buffer = ''
let firstTokenMs
let final

for await (const chunk of response.body) {
  buffer += decoder.decode(chunk, { stream: true })
  const lines = buffer.split('\n')
  buffer = lines.pop()

  for (const line of lines.filter(Boolean)) {
    const event = JSON.parse(line)
    if (event.message?.content && firstTokenMs === undefined) {
      firstTokenMs = performance.now() - start
    }
    process.stdout.write(event.message?.content ?? '')
    if (event.done) final = event
  }
}
The last event has done: true and the counters. Here’s stream.js on the Docker Compose post with gemma3:4b, first with the model unloaded, then again with it in memory:
$ node stream.js ~/www/flaviocopes.com/src/posts/docker-compose.md
{"description": "Learn how to use Docker Compose to define and manage multi-container applications, simplifying deployment and development workflows.", "tag": "docker"}

load:          2815 ms
prompt:        1898 tokens at 726 tok/s
first token:   5490 ms
output:        32 tokens at 40.7 tok/s
total:         6276 ms
$ node stream.js ~/www/flaviocopes.com/src/posts/docker-compose.md
{"description": "Learn how to use Docker Compose to define and manage multi-container applications, simplifying deployment and development workflows.", "tag": "docker"}
load: 2 ms
prompt: 1898 tokens at 47075 tok/s
first token: 102 ms
output: 32 tokens at 40.9 tok/s
total: 884 msThe second run didn’t load anything, and it didn’t really read the prompt either: Ollama kept the KV cache of the previous request and reused it, because the prompt was identical. The non-streaming response says so in prompt_eval_cached_count: 1,897 of the 1,898 prompt tokens came from the cache. Generation speed is the same, about 41 tokens per second.
With temperature: 0 and the same seed, the answer is identical too.
A real batch sends a different post each time, so the prompt has to be read. I measured each model cold on the Docker Compose post, then warm on three other posts (Kysely, cron, Git hooks), and took the median:
| Model | First token, cold | First token, warm | Reading the prompt | Writing |
|---|---|---|---|---|
gemma3:1b Q4_K_M |
1.9 s | 0.8 s | 2,728 tok/s | 116 tok/s |
gemma3:1b-it-q8_0 |
1.9 s | 0.7 s | 2,973 tok/s | 95 tok/s |
gemma3:1b-it-fp16 |
1.2 s | 0.7 s | 2,939 tok/s | 58 tok/s |
gemma3:4b Q4_K_M |
5.4 s | 3.0 s | 627 tok/s | 45 tok/s |
gemma4:26b Q4_K_M |
8.2 s | 3.9 s | 520 tok/s | 37 tok/s |
Other jobs were using the same GPU on and off, and speeds moved a lot between runs (the 1B model wrote anywhere from 32 to 143 tokens per second), so read these as rough sizes. A few things hold anyway.
For this feature, reading the prompt costs more than writing the answer. A post is about 1,800 tokens in and 35 tokens out, so gemma3:4b spends 3 seconds reading and under 1 second writing.
FP16 writes at half the speed of Q4_K_M. Generating a token means reading every weight from memory once, and the FP16 file is 2.5 times bigger. That’s the other half of the quantization trade: smaller files are faster, not only lighter.
gemma4:26b has 25.8 billion parameters and writes almost as fast as the 4B model. Its metadata explains why: expert_count = 128 and expert_used_count = 8. It’s a mixture-of-experts model, and each token only goes through 8 of the 128 experts in each layer. It still needs all of them in memory, 17.7 GiB.
If you forward this to a browser, streaming LLM responses with server-sent events covers the server side.
Timeouts and cancellation
A local request can still hang. The model may have to load from disk first, the Mac may be swapping because something else took the memory, or the model may keep generating.
Two things can stop a request: our time budget, and the caller deciding the answer no longer matters (you press Ctrl+C, or a user closes the page). AbortSignal.any() combines them into one signal for fetch():
const signals = [AbortSignal.timeout(timeoutMs)]
if (signal) signals.push(signal)

response = await fetch(`${url}/api/chat`, {
  method: 'POST',
  body: JSON.stringify(request),
  signal: AbortSignal.any(signals),
})
They end differently, though. A timeout is an expected failure that should fall back. A cancellation means nobody wants the answer, so we let the AbortError go up and print nothing. The provider turns every expected failure into a ProviderError with a kind:
} catch (error) {
  if (signal?.aborted) throw error
  if (error.name === 'TimeoutError') {
    throw new ProviderError('timeout', `no answer in ${timeoutMs} ms`)
  }
  throw new ProviderError('unreachable', `cannot reach ${url}`, { cause: error })
}
The kinds are timeout, unreachable, unavailable (the startup check failed), http (like a 404 for a model that isn’t installed), invalid (not JSON) and rejected (failed validation). They all fall back, but they show up in the log with different fixes: start Ollama, pull the model, shorten the prompt, change the model.
How long should the budget be? I picked 20 seconds after measuring: gemma3:4b answers a new post in about 4 seconds when it’s loaded, and in about 6 when it has to load first. Here’s the same post with a 500 ms budget:
$ TIMEOUT_MS=500 node cli.js ~/www/flaviocopes.com/src/posts/docker-compose.md
[docker-compose] timeout: no answer in 500 ms
{
  "slug": "docker-compose",
  "source": "fallback",
  "description": "Docker Compose runs multi-container setups from a single file.",
  "tag": "docker"
}
The log line goes to stderr, the JSON to stdout, so you can pipe the result and still see why it fell back.
A deterministic fallback
The fallback doesn’t pretend to be another model. It builds the answer from the post: the first sentence of prose (skipping headings, code, quotes and images) as the description, and the tag whose name appears most often in the text:
export function fallbackMeta(post) {
  return {
    description: firstSentence(post.body),
    tag: guessTag(post),
  }
}
It’s crude, and it’s honest. On the evaluation set it picked the right tag for 14 of 24 posts. Its descriptions are the post’s opening line, which is often a good hook and rarely a good summary:
Docker Compose runs multi-container setups from a single file.
I like SQL because I can see the tables, selected columns, and conditions that decide which rows come back.
meta.js puts the pieces together. It asks the model, validates, and falls back on any ProviderError. Anything else is a bug, and it throws:
export async function suggestMeta(post, { provider, signal, log = console.error }) {
  try {
    const { meta, stats } = await askModel(post, { provider, signal })
    return { source: provider.name, ...meta, stats }
  } catch (error) {
    if (signal?.aborted) throw error
    if (!error.kind) throw error
    log(`[${post.slug}] ${error.kind}: ${error.message}`)
  }

  return { source: 'fallback', ...fallbackMeta(post) }
}
source tells me which path produced the suggestion. With Ollama not running (I pointed the script at port 11435, where nothing listens, which is the same thing from the client’s side):
$ LLM_URL=http://127.0.0.1:11435 node cli.js ~/www/flaviocopes.com/src/posts/docker-compose.md
[docker-compose] unavailable: Ollama is not running at http://127.0.0.1:11435
{
  "slug": "docker-compose",
  "source": "fallback",
  "description": "Docker Compose runs multi-container setups from a single file.",
  "tag": "docker"
}
The message comes from the model check we’ll add in the pinning section, which runs before the first request. Without it, the fetch() fails with a connection error and the provider reports unreachable. Same fallback either way.
Retry once, with the errors
askModel() gives the model one more try before falling back. It sends the rejected answer back as the assistant’s message, followed by the validator’s list of problems:
export async function askModel(post, { provider, signal, retries = 1 }) {
  let feedback
  for (let attempt = 0; attempt <= retries; attempt++) {
    const { meta, stats } = await provider.suggest(post, { signal, feedback })
    const errors = validate(meta, post)
    if (errors.length === 0) return { meta, stats, attempts: attempt + 1 }
    feedback = { answer: meta, errors }
  }
  throw Object.assign(new ProviderError('rejected', feedback.errors.join(', ')), feedback)
}
if (feedback) {
messages.push(
{ role: 'assistant', content: JSON.stringify(feedback.answer) },
{ role: 'user', content: `Fix these problems and return the JSON again: ${feedback.errors.join(', ')}.` },
)
}A second request costs another 4 seconds, so I capped it at one.
Keep the provider swappable
Nothing outside ollama.js knows about Ollama’s response format. A provider is an object with a name and a suggest(post, { signal, feedback }) method that returns { meta, stats } or throws a ProviderError. That’s the whole interface, the same idea as the LLM adapter pattern I use on Cloudflare Workers.
The second provider talks to any OpenAI-compatible /v1/chat/completions endpoint. LM Studio, llama.cpp’s llama-server, vLLM and hosted APIs all speak it, and so does Ollama. The differences are in the request shape:
body: JSON.stringify({
model,
messages: buildMessages(post, feedback),
response_format: {
type: 'json_schema',
json_schema: { name: 'post_meta', schema, strict: true },
},
temperature: 0,
max_tokens: 150,
}),and in where the text comes back, data.choices[0].message.content. Everything that happens after the response is shared code. Here’s the same post through Ollama’s OpenAI-compatible endpoint:
$ PROVIDER=openai node cli.js ~/www/flaviocopes.com/src/posts/docker-compose.md
{
"slug": "docker-compose",
"source": "openai:gemma3:4b",
"description": "Learn how to use Docker Compose to define and manage multi-container applications, simplifying deployment and development workflows.",
"tag": "docker",
"stats": {
"promptTokens": 1898,
"outputTokens": 32
}
}Same model, same answer, and less information: the OpenAI format reports token counts but not Ollama’s load and timing durations.
Switching is configuration: PROVIDER, LLM_URL, MODEL. A different model behind the same interface still has to pass the same evaluation before it gets the job.
A small evaluation set
One good answer tells you nothing. I picked 24 published posts across 19 tags, from a 400-word Python tip to a 6,000-word guide, and used my own frontmatter as the expected answer:
[
"x-prevent-links", "browser-apis-replacing-libraries",
"claude-code-games-rule", "conductor-alternatives",
"npm-update-global", "npkill",
"zustand", "tanstack-query",
"css-oklch-color-mix", "css-scroll-driven-animations",
"python-check-string", "install-iphone-apps",
"deno-workers", "kysely",
"cron", "git-hooks",
"docker-compose", "build-astro-integration",
"macos-dmg-installer", "http2-http3",
"tailscale", "stripe-pay",
"html-dialog-tag", "golang-interfaces"
]A case passes when the answer passes validate() and the tag matches mine. The description’s quality is something I read myself, so the runner saves every answer to results/<model>.json.
eval/run.js runs the fallback first as a baseline, then each model given on the command line. It unloads the model before starting, so the first request includes the load time:
$ node eval/run.js gemma3:1b gemma3:1b-it-q8_0 gemma3:1b-it-fp16 gemma3:4b
fallback: valid 20/24, tag 14/24, pass 13/24
gemma3:1b: valid 4/24, tag 12/24, pass 2/24
retries used: 20
median 1035 ms per post, 143.4 tok/s, 0.9 GB in ollama ps
gemma3:1b-it-q8_0: valid 7/24, tag 7/24, pass 2/24
retries used: 17
median 850 ms per post, 129.3 tok/s, 1.1 GB in ollama ps
gemma3:1b-it-fp16: valid 6/24, tag 7/24, pass 2/24
retries used: 18
median 1004 ms per post, 91.9 tok/s, 2.1 GB in ollama ps
gemma3:4b: valid 18/24, tag 17/24, pass 14/24
retries used: 6
median 3099 ms per post, 63.8 tok/s, 2.3 GB in ollama psgemma4:26b was already loaded with a 32,768-token window, so I ran it warm with that context instead of reloading it:
$ COLD=0 NUM_CTX=32768 node eval/run.js gemma4:26b
fallback: valid 20/24, tag 14/24, pass 13/24
gemma4:26b: valid 24/24, tag 23/24, pass 23/24
retries used: 0
median 3021 ms per post, 52 tok/s, 1.6 GB in ollama psThe pass counts were identical to an earlier run of the same code, thanks to temperature: 0 and the fixed seed. The speeds were not: the 1B model had run at a quarter of this speed while other jobs were using the GPU.
I ran the set three times while changing the prompt:
| Prompt | Model | Valid answers | Tag matches mine | Passed |
|---|---|---|---|---|
| 1: “50 to 160 characters”, tags as a list | gemma3:1b |
3 | 2 | 0 |
gemma3:4b |
0 | 12 | 0 | |
| 2: “12 to 22 words”, tag descriptions, 2 examples | gemma3:1b |
3 | 9 | 0 |
gemma3:4b |
4 | 16 | 3 | |
| 3: “at most 18 words”, plus one retry | gemma3:1b |
4 | 12 | 2 |
gemma3:4b |
18 | 17 | 14 | |
gemma4:26b |
24 | 23 | 23 | |
| No model | fallback | 20 | 14 | 13 |
Some things the runs made obvious:
- With the first prompt the 1B model tagged most posts
ai, the first tag in the list. With tag descriptions it spread out, and got 9 to 12 tags right. - Quantization didn’t change the 1B result. Q4_K_M, Q8_0 and FP16 all passed 2 of 24.
gemma3:4bwent from 0 to 14 passing cases with prompt changes alone. Most of its remaining failures are descriptions over 160 characters that the retry didn’t shorten enough.gemma4:26bpassed 23 of 24 with the same prompt and never needed the retry. It also needs 17.7 GiB of memory while it runs.- The automatic fallback passes 13 of 24, nearly as many as
gemma3:4b. That says more about my checks than about the fallback: they can verify a shape, not whether a sentence summarizes the post.
So I read the answers. Here are a few, next to what I wrote:
| Post | What I wrote | gemma3:4b |
gemma4:26b |
|---|---|---|---|
kysely |
Build a small PostgreSQL-backed store with Kysely, from the first typed query to joins, transactions, migrations, debugging, and tests. | Learn how to use Kysely with TypeScript to build a type-safe database query builder for PostgreSQL, ensuring data integrity and catching errors early. | Learn how to use Kysely as a type-safe SQL query builder with TypeScript and PostgreSQL. |
cron |
Learn cron on Linux and macOS: crontab syntax, schedules, the cron environment, logs, overlapping runs, time zones, launchd and systemd timers. | Learn how to use cron jobs on Linux and macOS to schedule commands, including setting up a nightly backup job and understanding the cron syntax. | Learn how to schedule and manage cron jobs on Linux and macOS using crontab syntax and examples. |
install-iphone-apps |
Put the apps you build on your iPhone without the App Store: turn on Developer Mode, install from Xcode, update over Wi-Fi from the terminal, and renew them. | Learn how to install your own apps on your iPhone using Xcode, including building, signing, and updating from the terminal. (tag: cli) |
Learn how to install and update your own apps on an iPhone using Xcode and the terminal. (tag: swift) |
claude-code-games-rule |
Claude Code got a rule against recreating existing games, it misfired, and Anthropic narrowed it. I’d rather the tool did what I ask and left the legal side to me. | Learn how Claude Code’s rules regarding game creation have evolved, including a recent fix and the ongoing debate about copyright and AI tool usage. | Learn about the controversy surrounding Anthropic’s decision to implement restrictive copyright rules within Claude Code. |
The gemma3:4b descriptions are usable as drafts. They lean on “Learn how to” and add filler like “simplifying deployment and development workflows” that I’d cut, and it tagged the iPhone post cli where I used swift. The gemma4:26b ones are shorter and plainer, closer to what I’d write. Its one wrong tag was network for the post about stopping X from turning domains into links, which I filed under js. I can see its point.
Tests with node —test
The evaluation needs a running model and takes minutes. The tests need neither. They cover the parts I control: validation, the fallback, the retry, error handling, timeouts and cancellation, using a fake provider:
const fake = (suggest) => ({ name: 'fake', suggest })
test('falls back when Ollama is unreachable', async () => {
const provider = fake(async () => { throw new ProviderError('unreachable', 'down') })
const result = await suggestMeta(post, { provider, log: quiet })
assert.deepEqual(result, { source: 'fallback', ...fallbackMeta(post) })
})
test('does not hide programming errors', async () => {
const provider = fake(async () => { throw new TypeError('post.boddy is undefined') })
await assert.rejects(suggestMeta(post, { provider, log: quiet }), TypeError)
})The timeout test starts a local HTTP server that accepts the request and never answers, then points the real Ollama provider at it with a 200 ms budget:
test('a hanging server becomes a timeout', async (t) => {
const server = createServer(() => {})
await new Promise((resolve) => server.listen(0, '127.0.0.1', resolve))
t.after(() => server.closeAllConnections() || server.close())
const provider = createOllamaProvider({
url: `http://127.0.0.1:${server.address().port}`,
model: 'gemma3:4b',
timeoutMs: 200,
numCtx: 4096,
})
await assert.rejects(provider.suggest(post), { kind: 'timeout' })
})$ node --test --test-reporter=spec
✔ uses the model answer when it passes validation (12.135666ms)
✔ falls back when the model invents a number (1.291333ms)
✔ retries once with the validator errors (1.409ms)
✔ falls back when Ollama is unreachable (0.677541ms)
✔ does not hide programming errors (0.656584ms)
✔ the fallback is deterministic (0.124833ms)
✔ validate lists every problem (0.347166ms)
✔ a hanging server becomes a timeout (221.0935ms)
✔ the caller can cancel (60.507459ms)
ℹ tests 9
ℹ suites 0
ℹ pass 9
ℹ fail 0
ℹ cancelled 0
ℹ skipped 0
ℹ todo 0
ℹ duration_ms 660.2115These run anywhere, CI included. The evaluation runs on my Mac when I change the model or the prompt.
Pin the model
gemma3:4b is a name, and names move. If the publisher updates the tag, the next ollama pull replaces the weights and the behavior I evaluated. The digest identifies the exact files, and ollama list shows its first 12 characters:
NAME ID SIZE MODIFIED
gemma3:1b-it-fp16 d685bd623bd3 2.0 GB 38 minutes ago
gemma3:1b-it-q8_0 e3acf9b8e078 1.1 GB 41 minutes ago
gemma3:1b 8648f39daa8f 815 MB 7 months ago
gemma3:4b a2af6cc3eb7f 3.3 GB 7 months ago
gemma4:26b 5571076f3d70 17 GB 7 months agoThe config pins both, and check-model.js asks /api/tags before doing anything:
export async function checkModel({ url, model, digest }) {
let models
try {
({ models } = await (await fetch(`${url}/api/tags`, { signal: AbortSignal.timeout(1000) })).json())
} catch {
return `Ollama is not running at ${url}`
}
const installed = models.find((m) => m.name === model)
if (!installed) return `${model} is not installed: run ollama pull ${model}`
if (!installed.digest.startsWith(digest)) {
return `${model} is ${installed.digest.slice(0, 12)}, expected ${digest}`
}
return null
}When it returns a problem, the CLI skips the model and uses the fallback for every post. With a wrong digest in the config:
$ MODEL_DIGEST=1a2b3c4d5e6f node cli.js ~/www/flaviocopes.com/src/posts/kysely.md
[kysely] unavailable: gemma3:4b is a2af6cc3eb7f, expected 1a2b3c4d5e6f
{
"slug": "kysely",
"source": "fallback",
"description": "I like SQL because I can see the tables, selected columns, and conditions that decide which rows come back.",
"tag": "database"
}To upgrade, I pull the new model, run the evaluation, compare it with the saved results of the current one, and only then change model and digest in config.js. The old model stays installed until the new one has been used for a while, so going back is one config change.
What it costs
There’s no invoice, but it isn’t free.
gemma4:26b takes a median of 3 seconds per post, so the whole archive would keep the Mac busy for about 2 hours. Each post is about 1,800 tokens in and 35 out, so that’s around 4 million input tokens and 80,000 output tokens. Multiply by an API’s price per million tokens if you want the comparison.
The costs that do show up are physical. While it runs, gemma4:26b holds 17.7 GiB of memory that the browser, the editor and the dev server can’t use (gemma3:4b holds 4.2 GiB). The models I pulled for this post take 24 GB of disk. And every suggestion still costs me the time to read it, whichever model wrote it.
Local LLMs versus API costs does the hardware and electricity math for heavier use. For this feature the deciding factor wasn’t money. It was that drafts stay on my Mac, and that the script works on a plane.
How I would use it
I’d run it on drafts, as a suggestion I read and edit, never writing into the frontmatter by itself. The source field stays in the output, so I know when I’m looking at the fallback.
On this Mac I’d use gemma4:26b. On a 16 GB laptop it doesn’t fit next to a browser and an editor, and gemma3:4b is the one I’d pick there, with more editing. I’d skip the 1B models for this task whatever the quantization: they’re fast and fit anywhere, but they passed 2 of 24.
There’s also a job in the archive: 99 posts have an empty tag:. A batch run over those takes about 5 minutes with gemma4:26b and gives me a list to review in one sitting.
I wouldn’t let it retag the posts that already have a tag. Even 23 of 24 means dozens of wrong tags across the whole archive, and I’d have to review all of them to find those.
The complete code
Node.js 22 or later, no dependencies. Create a folder with these files, start Ollama, pull the model, and run node cli.js path/to/post.md.
package.json
{
"name": "post-meta",
"type": "module",
"private": true,
"scripts": {
"test": "node --test",
"eval": "node eval/run.js"
}
}config.js
export const config = {
provider: process.env.PROVIDER ?? 'ollama',
url: process.env.LLM_URL ?? 'http://127.0.0.1:11434',
model: process.env.MODEL ?? 'gemma3:4b',
digest: process.env.MODEL_DIGEST ?? 'a2af6cc3eb7f',
apiKey: process.env.LLM_API_KEY,
timeoutMs: Number(process.env.TIMEOUT_MS ?? 20000),
numCtx: Number(process.env.NUM_CTX ?? 4096),
}errors.js
export class ProviderError extends Error {
constructor(kind, message, options) {
super(message, options)
this.kind = kind
}
}posts.js
import { readFile } from 'node:fs/promises'
import { basename } from 'node:path'
export async function readPost(file) {
const raw = await readFile(file, 'utf8')
const [, frontmatter, body] = raw.match(/^---\n([\s\S]*?)\n---\n([\s\S]*)$/)
const field = (name) =>
frontmatter.match(new RegExp(`^${name}:\\s*"?(.*?)"?$`, 'm'))?.[1] ?? ''
return {
slug: basename(file, '.md'),
title: field('title'),
description: field('description'),
tag: field('tag'),
body: body.trim(),
}
}prompt.js
export const TAGS = {
ai: 'LLMs, AI models, coding agents, AI tools',
astro: 'the Astro framework',
business: 'running an online business, payments, pricing, SaaS',
cli: 'the terminal, shell, Linux command line tools',
cloudflare: 'Cloudflare Workers, Pages, D1, R2, Durable Objects',
css: 'CSS and styling',
database: 'SQL, Postgres, SQLite, query builders, data storage',
docker: 'Docker and containers',
git: 'Git, GitHub, hooks, pull requests',
go: 'the Go language',
html: 'HTML elements and attributes',
js: 'JavaScript in the browser and the language itself',
mac: 'macOS, Mac apps, distributing apps for the Mac',
network: 'HTTP, DNS, protocols, how the web works',
node: 'Node.js, npm, packages',
python: 'the Python language',
react: 'React and its libraries',
security: 'private networks, VPN, SSH, firewalls, server security',
swift: 'Swift, Xcode, iPhone and Apple platform apps',
}
export const schema = {
type: 'object',
properties: {
description: { type: 'string' },
tag: { type: 'string', enum: Object.keys(TAGS) },
},
required: ['description', 'tag'],
additionalProperties: false,
}
const MAX_BODY_CHARS = 6000
const SYSTEM = `You write metadata for a post on flaviocopes.com, a programming blog.
Return JSON with:
- description: one short sentence, at most 18 words, saying what the reader learns or does. Use only facts from the post. Start with a verb like "Learn", "Build" or "Use", or with the subject. End with a period.
- tag: the one topic that fits best:
${Object.entries(TAGS).map(([tag, topic]) => ` ${tag}: ${topic}`).join('\n')}
Examples:
{"description": "Learn how the React Context API lets you share state across your app without prop drilling, using createContext and useContext.", "tag": "react"}
{"description": "Learn tmux from scratch: create persistent sessions, use windows and panes, and work safely over SSH.", "tag": "cli"}`
export function buildMessages(post, feedback) {
const messages = [
{ role: 'system', content: SYSTEM },
{ role: 'user', content: `Title: ${post.title}\n\n${post.body.slice(0, MAX_BODY_CHARS)}` },
]
if (feedback) {
  messages.push(
    { role: 'assistant', content: JSON.stringify(feedback.answer) },
    { role: 'user', content: `Fix these problems and return the JSON again: ${feedback.errors.join(', ')}.` },
  )
}
return messages
}validate.js
import { TAGS } from './prompt.js'
export function validate(result, post) {
const errors = []
if (typeof result?.description !== 'string') errors.push('description missing')
if (!Object.hasOwn(TAGS, result?.tag ?? '')) errors.push(`tag not allowed: ${result?.tag}`)
if (errors.length) return errors
const { description } = result
if (description.length < 50) errors.push(`description too short: ${description.length}`)
if (description.length > 160) errors.push(`description too long: ${description.length}`)
if (description.includes('\u2014')) errors.push('description has an em dash')
if (/^(this post|in this)/i.test(description)) errors.push('description starts with filler')
if (!/[.!?]$/.test(description)) errors.push('description is not a full sentence')
for (const number of description.match(/\d+(\.\d+)?/g) ?? []) {
if (!post.title.includes(number) && !post.body.includes(number)) {
errors.push(`number not in post: ${number}`)
}
}
return errors
}fallback.js
import { TAGS } from './prompt.js'
export function fallbackMeta(post) {
return {
description: firstSentence(post.body),
tag: guessTag(post),
}
}
function firstSentence(body) {
const prose = body
.replace(/```[\s\S]*?```/g, '')
.split('\n')
.filter((line) => line.trim() && !/^[#>|!<-]/.test(line.trim()))
.join(' ')
.replace(/\[([^\]]+)\]\([^)]+\)/g, '$1')
.replace(/[`*_]/g, '')
const sentence = prose.match(/^.*?[.!?](\s|$)/)?.[0].trim() ?? prose
return sentence.length <= 160 ? sentence : `${sentence.slice(0, 157).trimEnd()}...`
}
function guessTag(post) {
const text = `${post.title} ${post.body}`.toLowerCase().replaceAll('javascript', 'js')
const count = (tag) => text.match(new RegExp(`\\b${tag}\\b`, 'g'))?.length ?? 0
const [best] = Object.keys(TAGS).map((tag) => [tag, count(tag)]).sort((a, b) => b[1] - a[1])
return best[1] > 0 ? best[0] : 'js'
}ollama.js
import { ProviderError } from './errors.js'
import { buildMessages, schema } from './prompt.js'
export function createOllamaProvider({ url, model, timeoutMs, numCtx }) {
return {
name: `ollama:${model}`,
async suggest(post, { signal, feedback } = {}) {
const signals = [AbortSignal.timeout(timeoutMs)]
if (signal) signals.push(signal)
let response
try {
response = await fetch(`${url}/api/chat`, {
method: 'POST',
headers: { 'content-type': 'application/json' },
body: JSON.stringify({
model,
messages: buildMessages(post, feedback),
format: schema,
stream: false,
think: false,
options: { temperature: 0, seed: 42, num_ctx: numCtx, num_predict: 150 },
}),
signal: AbortSignal.any(signals),
})
} catch (error) {
if (signal?.aborted) throw error
if (error.name === 'TimeoutError') {
throw new ProviderError('timeout', `no answer in ${timeoutMs} ms`)
}
throw new ProviderError('unreachable', `cannot reach ${url}`, { cause: error })
}
if (!response.ok) {
const text = await response.text()
throw new ProviderError('http', `HTTP ${response.status}: ${text}`)
}
const data = await response.json()
try {
return { meta: JSON.parse(data.message.content), stats: statsFrom(data) }
} catch {
throw new ProviderError('invalid', `not JSON: ${data.message.content.slice(0, 80)}`)
}
},
}
}
export function statsFrom(data) {
return {
promptTokens: data.prompt_eval_count,
outputTokens: data.eval_count,
loadMs: Math.round(data.load_duration / 1e6),
totalMs: Math.round(data.total_duration / 1e6),
tokensPerSecond: +(data.eval_count / (data.eval_duration / 1e9)).toFixed(1),
}
}openai.js
import { ProviderError } from './errors.js'
import { buildMessages, schema } from './prompt.js'
export function createOpenAIProvider({ url, model, apiKey = '', timeoutMs }) {
return {
name: `openai:${model}`,
async suggest(post, { signal, feedback } = {}) {
const signals = [AbortSignal.timeout(timeoutMs)]
if (signal) signals.push(signal)
let response
try {
response = await fetch(`${url}/v1/chat/completions`, {
method: 'POST',
headers: {
'content-type': 'application/json',
authorization: `Bearer ${apiKey}`,
},
body: JSON.stringify({
  model,
  messages: buildMessages(post, feedback),
  response_format: {
    type: 'json_schema',
    json_schema: { name: 'post_meta', schema, strict: true },
  },
  temperature: 0,
  max_tokens: 150,
}),
signal: AbortSignal.any(signals),
})
} catch (error) {
if (signal?.aborted) throw error
if (error.name === 'TimeoutError') {
throw new ProviderError('timeout', `no answer in ${timeoutMs} ms`)
}
throw new ProviderError('unreachable', `cannot reach ${url}`, { cause: error })
}
if (!response.ok) {
throw new ProviderError('http', `HTTP ${response.status}: ${await response.text()}`)
}
const data = await response.json()
const content = data.choices[0].message.content
try {
return {
meta: JSON.parse(content),
stats: { promptTokens: data.usage.prompt_tokens, outputTokens: data.usage.completion_tokens },
}
} catch {
throw new ProviderError('invalid', `not JSON: ${content.slice(0, 80)}`)
}
},
}
}meta.js
import { fallbackMeta } from './fallback.js'
import { ProviderError } from './errors.js'
import { validate } from './validate.js'
export async function askModel(post, { provider, signal, retries = 1 }) {
let feedback
for (let attempt = 0; attempt <= retries; attempt++) {
const { meta, stats } = await provider.suggest(post, { signal, feedback })
const errors = validate(meta, post)
if (errors.length === 0) return { meta, stats, attempts: attempt + 1 }
feedback = { answer: meta, errors }
}
throw Object.assign(new ProviderError('rejected', feedback.errors.join(', ')), feedback)
}
export async function suggestMeta(post, { provider, signal, log = console.error }) {
try {
const { meta, stats } = await askModel(post, { provider, signal })
return { source: provider.name, ...meta, stats }
} catch (error) {
if (signal?.aborted) throw error
if (!error.kind) throw error
log(`[${post.slug}] ${error.kind}: ${error.message}`)
}
return { source: 'fallback', ...fallbackMeta(post) }
}check-model.js
export async function checkModel({ url, model, digest }) {
let models
try {
({ models } = await (await fetch(`${url}/api/tags`, { signal: AbortSignal.timeout(1000) })).json())
} catch {
return `Ollama is not running at ${url}`
}
const installed = models.find((m) => m.name === model)
if (!installed) return `${model} is not installed: run ollama pull ${model}`
if (!installed.digest.startsWith(digest)) {
return `${model} is ${installed.digest.slice(0, 12)}, expected ${digest}`
}
return null
}cli.js
import { config } from './config.js'
import { checkModel } from './check-model.js'
import { ProviderError } from './errors.js'
import { createOllamaProvider } from './ollama.js'
import { createOpenAIProvider } from './openai.js'
import { suggestMeta } from './meta.js'
import { readPost } from './posts.js'
function createProvider() {
if (config.provider === 'openai') return createOpenAIProvider(config)
return createOllamaProvider(config)
}
const problem = config.provider === 'ollama' ? await checkModel(config) : null
const provider = problem
? { name: 'none', suggest: async () => { throw new ProviderError('unavailable', problem) } }
: createProvider()
const controller = new AbortController()
process.on('SIGINT', () => controller.abort())
for (const file of process.argv.slice(2)) {
const post = await readPost(file)
const result = await suggestMeta(post, { provider, signal: controller.signal })
console.log(JSON.stringify({ slug: post.slug, ...result }, null, 2))
}stream.js
import { config } from './config.js'
import { buildMessages, schema } from './prompt.js'
import { readPost } from './posts.js'
const [file, model = config.model] = process.argv.slice(2)
const post = await readPost(file)
const start = performance.now()
const response = await fetch(`${config.url}/api/chat`, {
method: 'POST',
body: JSON.stringify({
model,
messages: buildMessages(post),
format: schema,
think: false,
options: { temperature: 0, seed: 42, num_ctx: config.numCtx },
}),
})
const decoder = new TextDecoder()
let buffer = ''
let firstTokenMs
let final
for await (const chunk of response.body) {
buffer += decoder.decode(chunk, { stream: true })
const lines = buffer.split('\n')
buffer = lines.pop()
for (const line of lines.filter(Boolean)) {
const event = JSON.parse(line)
if (event.message?.content && firstTokenMs === undefined) {
firstTokenMs = performance.now() - start
}
process.stdout.write(event.message?.content ?? '')
if (event.done) final = event
}
}
console.log(`\n
load: ${(final.load_duration / 1e6).toFixed(0)} ms
prompt: ${final.prompt_eval_count} tokens at ${(final.prompt_eval_count / (final.prompt_eval_duration / 1e9)).toFixed(0)} tok/s
first token: ${firstTokenMs.toFixed(0)} ms
output: ${final.eval_count} tokens at ${(final.eval_count / (final.eval_duration / 1e9)).toFixed(1)} tok/s
total: ${(performance.now() - start).toFixed(0)} ms`)gguf.js
import { open } from 'node:fs/promises'
const TYPES = { 0: 'F32', 1: 'F16', 2: 'Q4_0', 6: 'Q5_0', 8: 'Q8_0', 12: 'Q4_K', 13: 'Q5_K', 14: 'Q6_K', 30: 'BF16' }
const file = await open(process.argv[2])
const { buffer } = await file.read({ buffer: Buffer.alloc(32 * 1024 * 1024), position: 0 })
await file.close()
let offset = 0
function read(size, method) {
offset += size
return buffer[method](offset - size)
}
const u32 = () => read(4, 'readUInt32LE')
const u64 = () => Number(read(8, 'readBigUInt64LE'))
function string() {
const length = u64()
offset += length
return buffer.toString('utf8', offset - length, offset)
}
function value(type) {
switch (type) {
case 0: case 1: case 7: return read(1, 'readUInt8')
case 4: return u32()
case 5: return read(4, 'readInt32LE')
case 6: return +read(4, 'readFloatLE').toPrecision(4)
case 8: return string()
case 9: {
const itemType = u32()
const count = u64()
for (let i = 0; i < count; i++) value(itemType)
return `[${count} items]`
}
case 10: return u64()
default: throw new Error(`unknown type ${type}`)
}
}
offset = 4
console.log(buffer.toString('ascii', 0, 4), 'version', u32())
const tensorCount = u64()
const kvCount = u64()
for (let i = 0; i < kvCount; i++) {
const key = string()
const text = String(value(u32()))
console.log(`${key} = ${text.length > 40 ? `${text.slice(0, 40).replaceAll('\n', ' ')}...` : text}`)
}
const byType = {}
for (let i = 0; i < tensorCount; i++) {
string()
const dims = u32()
let weights = 1
for (let d = 0; d < dims; d++) weights *= u64()
const type = TYPES[u32()]
u64()
byType[type] ??= { tensors: 0, weights: 0 }
byType[type].tensors++
byType[type].weights += weights
}
console.log(`${tensorCount} tensors`)
for (const [type, { tensors, weights }] of Object.entries(byType)) {
console.log(`${type}: ${tensors} tensors, ${(weights / 1e6).toFixed(0)}M weights`)
}eval/cases.json
[
  "x-prevent-links", "browser-apis-replacing-libraries",
  "claude-code-games-rule", "conductor-alternatives",
  "npm-update-global", "npkill",
  "zustand", "tanstack-query",
  "css-oklch-color-mix", "css-scroll-driven-animations",
  "python-check-string", "install-iphone-apps",
  "deno-workers", "kysely",
  "cron", "git-hooks",
  "docker-compose", "build-astro-integration",
  "macos-dmg-installer", "http2-http3",
  "tailscale", "stripe-pay",
  "html-dialog-tag", "golang-interfaces"
]eval/run.js
import { readFile, writeFile } from 'node:fs/promises'
import { config } from '../config.js'
import { createOllamaProvider } from '../ollama.js'
import { askModel } from '../meta.js'
import { fallbackMeta } from '../fallback.js'
import { readPost } from '../posts.js'
import { validate } from '../validate.js'
const POSTS = '/Users/flaviocopes/www/flaviocopes.com/src/posts'
const slugs = JSON.parse(await readFile(new URL('cases.json', import.meta.url)))
const posts = await Promise.all(slugs.map((slug) => readPost(`${POSTS}/${slug}.md`)))
const models = process.argv.slice(2)
const retries = Number(process.env.RETRIES ?? 1)
async function unload(model) {
await fetch(`${config.url}/api/generate`, {
method: 'POST',
body: JSON.stringify({ model, keep_alive: 0 }),
})
while ((await (await fetch(`${config.url}/api/ps`)).json()).models.some((m) => m.name === model)) {
await new Promise((resolve) => setTimeout(resolve, 200))
}
}
async function loadedSize(model) {
const { models } = await (await fetch(`${config.url}/api/ps`)).json()
const loaded = models.find((m) => m.name === model)
return (loaded.size / 1e9).toFixed(1)
}
async function evaluate(name, suggest) {
const rows = []
for (const post of posts) {
const row = { slug: post.slug, expected: post.tag }
try {
const { meta, stats, attempts } = await suggest(post)
Object.assign(row, meta, { stats, attempts, errors: validate(meta, post) })
} catch (error) {
row.errors = error.errors ?? [`${error.kind ?? error.name}: ${error.message}`]
Object.assign(row, error.answer, { attempts: retries + 1 })
}
row.tagOk = row.tag === post.tag
row.pass = row.errors.length === 0 && row.tagOk
rows.push(row)
}
const count = (key) => rows.filter((row) => row[key]).length
const valid = rows.filter((row) => row.errors.length === 0).length
console.log(`${name}: valid ${valid}/${rows.length}, tag ${count('tagOk')}/${rows.length}, pass ${count('pass')}/${rows.length}`)
await writeFile(new URL(`../results/${name.replace(/[:/]/g, '_')}.json`, import.meta.url), JSON.stringify(rows, null, 2))
return rows
}
await evaluate('fallback', async (post) => ({ meta: fallbackMeta(post), stats: null }))
for (const model of models) {
if (process.env.COLD !== '0') await unload(model)
const provider = createOllamaProvider({ ...config, model, timeoutMs: 120000 })
const rows = await evaluate(model, (post) => askModel(post, { provider, retries }))
const stats = rows.map((row) => row.stats).filter(Boolean)
console.log(` retries used: ${rows.filter((row) => row.attempts > 1).length}`)
const median = (values) => values.sort((a, b) => a - b)[Math.floor(values.length / 2)]
console.log(` median ${median(stats.map((s) => s.totalMs))} ms per post, ` +
`${median(stats.map((s) => s.tokensPerSecond))} tok/s, ${await loadedSize(model)} GB in ollama ps`)
}test/meta.test.js
import { test } from 'node:test'
import assert from 'node:assert/strict'
import { createServer } from 'node:http'
import { suggestMeta } from '../meta.js'
import { createOllamaProvider } from '../ollama.js'
import { ProviderError } from '../errors.js'
import { validate } from '../validate.js'
import { fallbackMeta } from '../fallback.js'
const post = {
slug: 'docker-compose',
title: 'Docker Compose',
body: 'Docker Compose runs multi-container apps from one docker-compose.yml file. ' +
'We start Node on port 3000 and Postgres 16 next to it.',
}
const fake = (suggest) => ({ name: 'fake', suggest })
const quiet = () => {}
test('uses the model answer when it passes validation', async () => {
const meta = { description: 'Run a Node app and Postgres 16 together from a single docker-compose.yml file.', tag: 'docker' }
const provider = fake(async () => ({ meta, stats: {} }))
const result = await suggestMeta(post, { provider, log: quiet })
assert.equal(result.source, 'fake')
assert.equal(result.tag, 'docker')
})
test('falls back when the model invents a number', async () => {
const meta = { description: 'Run a Node app and Postgres 15 together from a single docker-compose.yml file.', tag: 'docker' }
const provider = fake(async () => ({ meta, stats: {} }))
const result = await suggestMeta(post, { provider, log: quiet })
assert.equal(result.source, 'fallback')
})
test('retries once with the validator errors', async () => {
const answers = [
{ description: 'Run a Node app and Postgres 15 together from a single docker-compose.yml file.', tag: 'docker' },
{ description: 'Run a Node app and Postgres 16 together from a single docker-compose.yml file.', tag: 'docker' },
]
const calls = []
const provider = fake(async (post, options) => {
calls.push(options.feedback)
return { meta: answers[calls.length - 1], stats: {} }
})
const result = await suggestMeta(post, { provider, log: quiet })
assert.equal(result.source, 'fake')
assert.deepEqual(calls[1].errors, ['number not in post: 15'])
})
test('falls back when Ollama is unreachable', async () => {
const provider = fake(async () => { throw new ProviderError('unreachable', 'down') })
const result = await suggestMeta(post, { provider, log: quiet })
assert.deepEqual(result, { source: 'fallback', ...fallbackMeta(post) })
})
test('does not hide programming errors', async () => {
const provider = fake(async () => { throw new TypeError('post.boddy is undefined') })
await assert.rejects(suggestMeta(post, { provider, log: quiet }), TypeError)
})
test('the fallback is deterministic', () => {
assert.deepEqual(fallbackMeta(post), {
description: 'Docker Compose runs multi-container apps from one docker-compose.yml file.',
tag: 'docker',
})
})
test('validate lists every problem', () => {
const errors = validate({ description: 'This post explains Docker \u2014 briefly', tag: 'containers' }, post)
assert.deepEqual(errors, ['tag not allowed: containers'])
assert.deepEqual(validate({ description: 'This post explains Docker \u2014 briefly', tag: 'docker' }, post), [
'description too short: 35',
'description has an em dash',
'description starts with filler',
'description is not a full sentence',
])
})
test('a hanging server becomes a timeout', async (t) => {
  const server = createServer(() => {})
  await new Promise((resolve) => server.listen(0, '127.0.0.1', resolve))
  t.after(() => server.closeAllConnections() || server.close())

  const provider = createOllamaProvider({
    url: `http://127.0.0.1:${server.address().port}`,
    model: 'gemma3:4b',
    timeoutMs: 200,
    numCtx: 4096,
  })

  await assert.rejects(provider.suggest(post), { kind: 'timeout' })
})
test('the caller can cancel', async (t) => {
const server = createServer(() => {})
await new Promise((resolve) => server.listen(0, '127.0.0.1', resolve))
t.after(() => server.closeAllConnections() || server.close())
const provider = createOllamaProvider({
url: `http://127.0.0.1:${server.address().port}`,
model: 'gemma3:4b',
timeoutMs: 5000,
numCtx: 4096,
})
const controller = new AbortController()
setTimeout(() => controller.abort(), 50)
await assert.rejects(
suggestMeta(post, { provider, signal: controller.signal, log: quiet }),
{ name: 'AbortError' },
)
})Want me to talk about your product? You can sponsor this site.
Related posts about ai: